
Google News Scraper
Pricing
from $2.00 / 1,000 results
Google News Scraper
Scrape Google News by keyword, topic, or section. Get real publisher article URLs, not Google redirect links, plus descriptions, images, sources, and publish dates. Break past the 100-result limit, cover 70+ countries and languages, and export to JSON, CSV, or Excel for media monitoring and PR.
Pricing
from $2.00 / 1,000 results
Rating
0.0
(0)
Developer
SilentFlow
Maintained by CommunityActor stats
1
Bookmarked
2
Total users
1
Monthly active users
2 days ago
Last modified
Categories
Share
From SilentFlow. Creators of Facebook Search Scraper and Pinterest Scraper, with 500,000+ combined lifetime runs.
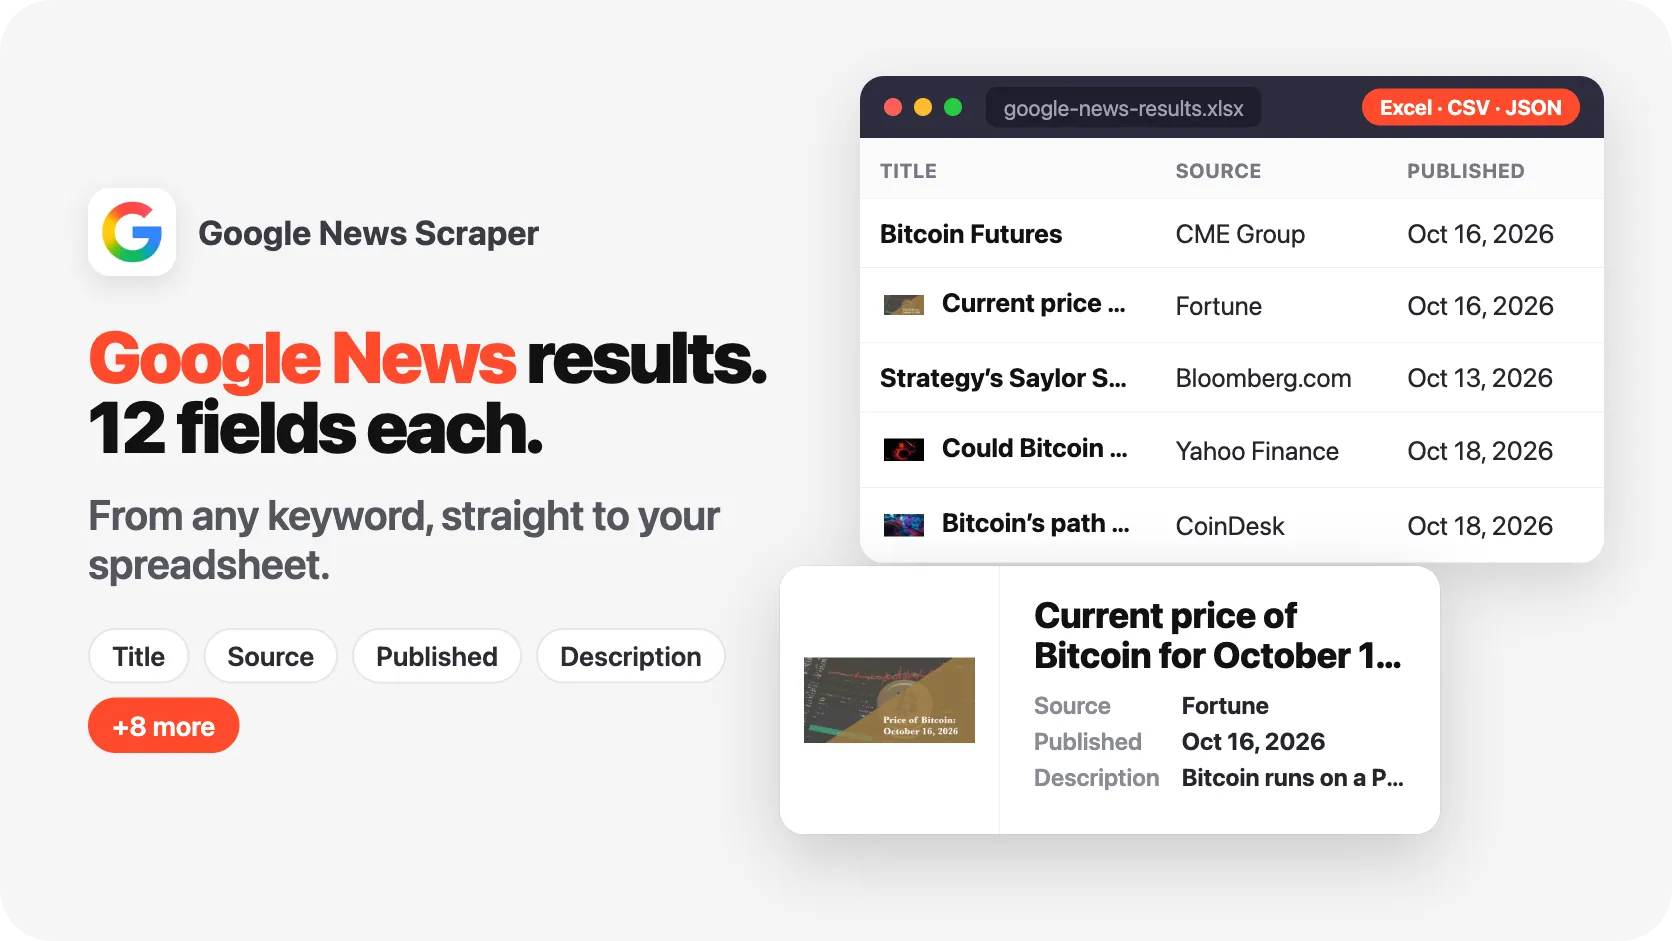
Get real, ready-to-click article URLs from Google News, not redirect links you have to decode yourself. Search any keyword or browse a topic and get titles, descriptions, images, and publish dates in structured JSON. 10 articles with full details in under 4 seconds.
How it works
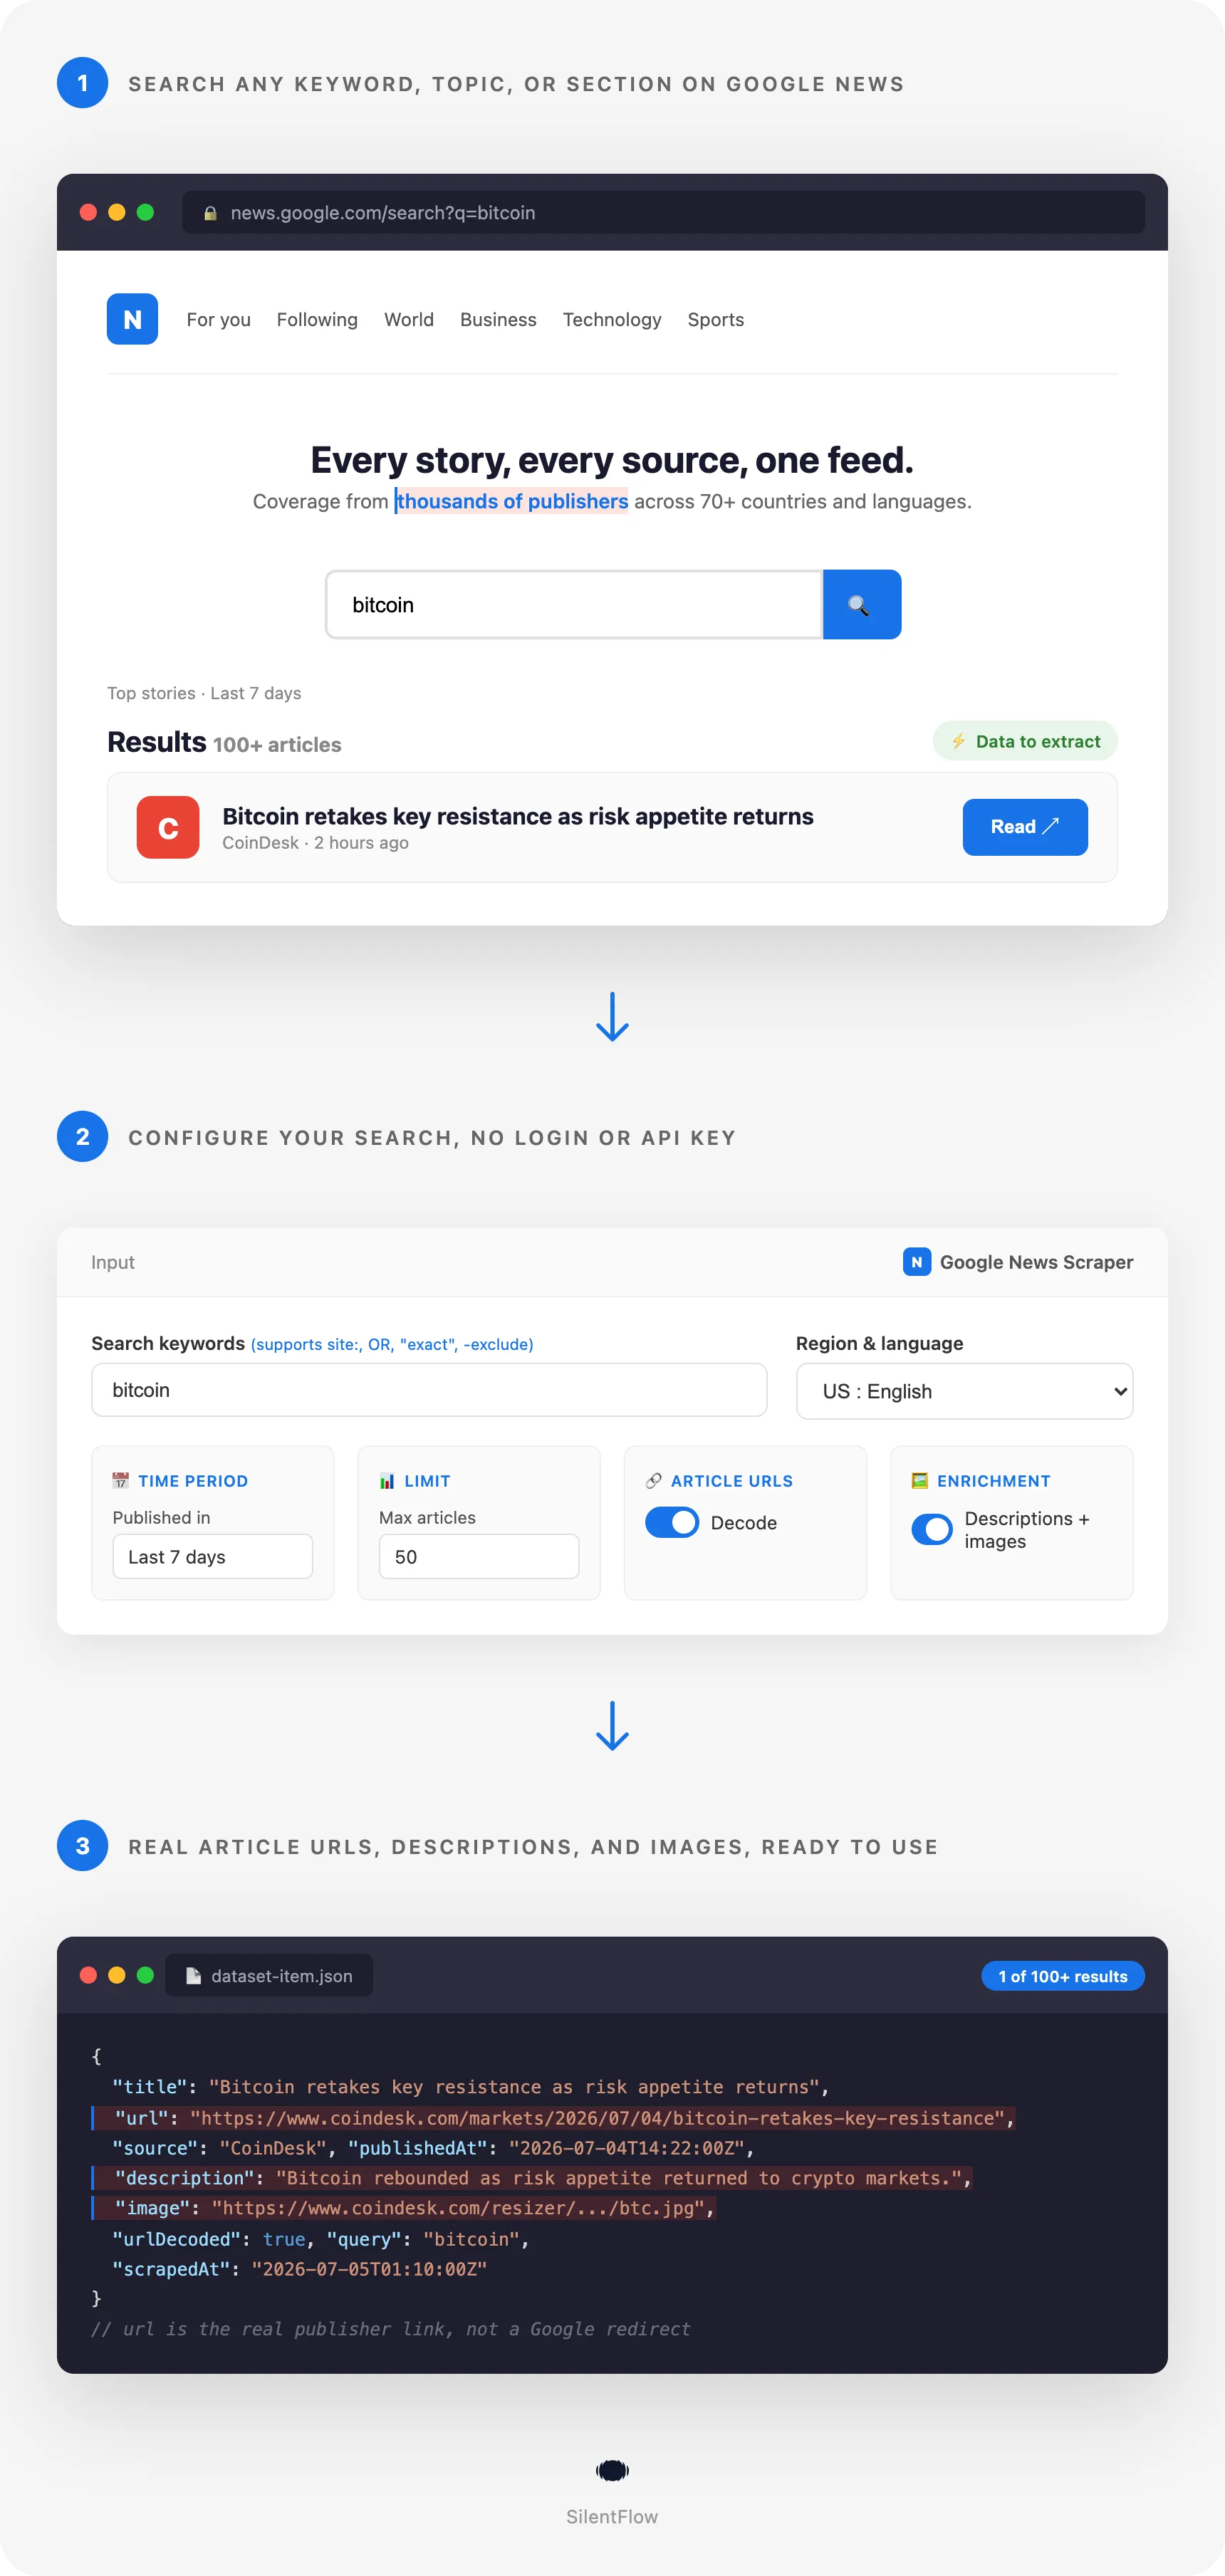
Three steps: (1) enter keywords, topics, or section URLs into the Apify input form, (2) the actor pulls matching Google News results, decodes each article link, and reads the publisher page for a description and image, (3) every article lands in your dataset as one clean JSON row with a working URL, a headline, a source, and a timestamp.
✨ Why teams choose this over other Google News scrapers
Ever run a Google News scraper and gotten a dataset full of news.google.com/rss/articles/CBMi... links instead of the actual article? Ever had to write your own script just to turn those links into something clickable? Ever hit a wall at exactly 100 results and wondered why?
- 🔗 Real article URLs, on by default. Other Google News scrapers ship Google's internal redirect links out of the box and make you flip on a "decode" option they warn is slow. Here, every
urlfield is already the publisher's real link. No extra setup, no extra step. - 📝 Descriptions and preview images included from the first run. Most competitors turn this off by default too. You get the article snippet and the
og:imagepreview picture without touching a single setting. - 📈 Break past the 100-article ceiling. Google News caps a single feed at around 100 results. Competitors stop there. This scraper automatically slices your time window into smaller chunks and stitches the results back together with zero duplicates, so a
maxItemsof 220 or more actually returns 220 or more. - 🌍 70+ country and language combinations. Search news the way people actually read it locally: US English, French from France or Quebec, Brazilian Portuguese, Simplified or Traditional Chinese, Arabic, Hindi, and dozens more.
- 🎯 Search operators just work. Use
site:reuters.com,"exact phrase",OR, and-excludethe same way you would on Google itself. No special query language to learn. - 🗞️ Predefined topics and custom sections. Pull the World, Business, Technology, Entertainment, Sports, Science, or Health feed directly, or point the scraper at any Google News section URL for a niche category.
- ⚡ Zero configuration. No login, no API key, no cookies to manage. Add a keyword or pick a topic and start the run.
- 💰 Pay for the articles you actually get delivered. No fixed monthly commitment standing between you and a first test run.
🎯 What you can do with Google News data
| Team | What they build |
|---|---|
| PR and communications | Real-time brand and executive mention monitors that alert the moment a competitor or your own company gets covered |
| Market and finance research | News-driven trading signals and sector watchlists built from headline volume and sentiment over time |
| Growth and SEO | Content gap trackers that show which publishers already cover a keyword you're targeting, and how often |
| Data science and NLP | Labeled datasets of headlines, descriptions, and publish dates for sentiment models and topic classifiers |
| Competitive intelligence | Daily digests of every article mentioning a competitor's product launches or funding rounds |
| Crisis communications | Early-warning feeds that catch a story spreading across outlets within the hour it breaks |
| Academic and policy research | Longitudinal datasets tracking how a topic (a bill, an election, a public health issue) gets covered across outlets |
| Content aggregators and newsletters | Curated topic digests pulled straight from predefined sections like Business or Technology |
📥 Input parameters
Search
| Parameter | Type | Description |
|---|---|---|
keywords | Array | Keywords or phrases to search. Supports Google search operators: quotes for an exact phrase, OR, - to exclude a term, and site: to restrict to one publisher. |
topics | Array | Predefined Google News topics: World, Nation, Business, Technology, Entertainment, Sports, Science, Health. |
topicUrls | Array | Any Google News topic or section URL, for niche categories not covered by the predefined list. |
At least one of keywords, topics, or topicUrls is required.
Filters
| Parameter | Type | Description |
|---|---|---|
timeframe | Select | How far back to search: last hour, last 24 hours, last 7 days, last 30 days, last year, or all time. Default 7d. Applies to keyword searches. |
regionLanguage | Select | Region and language pair for results, for example US:en, FR:fr, or JP:ja. 70+ combinations available. Default US:en. |
Options
| Parameter | Type | Description |
|---|---|---|
maxItems | Integer | Maximum articles per keyword or topic. Default 50. Set above 100 and the scraper automatically extends the search across additional time windows to keep delivering results. |
decodeUrls | Boolean | Resolve each Google News link to the real article URL on the publisher's site. Default true. |
enrichArticles | Boolean | Fetch each article's page to pull its description and preview image. Default true. |
📊 Output data
Searching bitcoin with defaults:
Browsing the Technology topic instead of searching a keyword swaps query for topic:
🗂️ Data fields
| Category | Fields |
|---|---|
| Article | title, publishedAt, description, image, position |
| Links | url (real publisher URL, present when urlDecoded is true), googleNewsUrl (the original Google News link), urlDecoded, ampUrl (the article's AMP version, included when the publisher offers one) |
| Source | source (publisher name), sourceUrl (publisher domain) |
| Provenance | query (the keyword that returned this article) or topic (the topic or section that returned it) |
| Metadata | scrapedAt |
Structured fields per article. publishedAt and scrapedAt are both UTC timestamps in ISO 8601 format, ready to sort or filter on directly. url is the publisher's own link and does not expire. description and image come from the publisher's own page metadata: most mainstream outlets publish both, but a share of smaller or paywalled sites omit one or both tags, in which case the field ships as an empty string rather than a missing key, so your schema stays consistent across every row.
🚀 Examples
Track mentions of a company
Watch a competitor with an exact phrase and a niche exclusion
Pull the daily Business and Technology digest
Go past 100 results on a broad keyword
Monitor one publisher for a niche keyword in French
Fast headline sweep with links and descriptions turned off
🤖 Copy to your AI assistant
Paste this block into Claude, ChatGPT, or Cursor to give it full context about this scraper:
💻 Integrations
Python: feed a brand-monitoring pipeline
JavaScript: build a daily topic digest
Export straight to CSV with the Apify CLI
📈 Performance
| Metric | Value |
|---|---|
| Articles per feed before time-window extension | ~100 |
| Small run (10 articles, URLs decoded, description and image enriched) | Under 4 seconds |
| Larger run past the 100-article cap (220 articles via automatic time slicing) | ~28 seconds, zero duplicates |
Fast mode (decodeUrls and enrichArticles off) | 20 headlines in under 1 second |
| URL decode success rate | Effectively 100% across tested keywords and topics |
| Region and language combinations | 70+ |
| Predefined topics | 8 |
| Fields per article | 12 |
💾 Data export
Every run's results are available on the dataset page in JSON, CSV, Excel, HTML table, and RSS formats, downloadable directly from the Apify Console. To pull results programmatically:
Swap format=csv for json, xlsx, html, or rss depending on what your pipeline needs. The dataset ID is returned by every run and visible on the Console's run overview page.
💡 Tips for best results
- Leave
decodeUrlsandenrichArticleson unless you only need raw headlines fast. The default already returns real URLs, descriptions, and images, so most users never need to touch these toggles. - Use
site:to scope a keyword to one or two trusted publishers when you want signal, not noise, from a broad term like a company name. - Set
maxItemsabove 100 for broad, evergreen keywords like an industry term or a public figure. The automatic time-window extension keeps returning fresh, non-duplicate articles well past the single-feed limit. - Match
regionLanguageto where the story is actually being covered. A US-based search on a European election will miss most of the local coverage; switching to the right country and language surfaces it. - Combine multiple keywords in one run (e.g. a brand name and its main competitors) to build a single comparative dataset instead of running the actor multiple times.
- Narrow
timeframeto1hor1dfor breaking-news monitoring and widen it to30dor1yfor trend and retrospective research.
❓ FAQ
Q: What exactly does this scraper extract? A: Structured articles from Google News: headline, real publisher URL, source, publish date, description, and preview image, one row per article.
Q: What is Google News, for anyone unfamiliar? A: Google's aggregated news feed. It indexes articles from thousands of publishers worldwide and organizes them by keyword search, topic (World, Business, Technology, and so on), and region or language.
Q: Do the article URLs actually work, or are they Google redirect links?
A: By default they resolve to the real article on the publisher's own site. The original Google News link is also kept in googleNewsUrl in case you want it, and urlDecoded tells you whether the resolution succeeded for that row.
Q: Can I search more than 100 articles for one keyword?
A: Yes. Set maxItems above 100 and the scraper automatically searches additional time windows and merges the results with no duplicates.
Q: Do I need a Google account or API key? A: No. The scraper reads publicly available news feeds. No login, no API key, no cookies.
Q: Can I run multiple keywords and topics in the same run?
A: Yes. keywords, topics, and topicUrls can all be set at once; each one is processed and tagged so you know which query or topic returned which article.
Q: Why are description or image sometimes empty?
A: Those two fields come from the publisher's own page metadata. Most mainstream outlets publish both, but some smaller sites or specific article types omit one or both tags. The row still ships with every other field filled in; only description and/or image come back empty for that article.
Q: How fresh is the data? A: Every run fetches live from Google News at the moment you start it. There is no caching layer, so results reflect what is published right now for your timeframe.
Q: Can I combine a timeframe filter with a specific region and language?
A: Yes, filters stack. A timeframe of 1d with regionLanguage set to FR:fr returns only French-language articles from the last 24 hours, for example.
Q: Are the article URLs permanent, or do they expire?
A: The decoded url is the publisher's own permanent article link. googleNewsUrl and image point to third-party infrastructure and can change over time at the publisher's discretion; the same is true of any article you'd bookmark directly from a browser.
⚖️ Legal
This Actor extracts publicly available data from Google News and the linked publisher pages. It does not bypass any login, paywall, or CAPTCHA. Users are responsible for complying with Google's and each publisher's terms of service and with applicable data protection laws (GDPR, CCPA, and other regional regulations where relevant). The data returned reflects publicly published news content; verify accuracy independently before using it for regulated or high-stakes decisions.
🔗 Related scrapers
Looking for other data sources to pair with news monitoring? Check the full catalog: silentflow on Apify, including social listening, e-commerce, and job market scrapers that combine well with news-driven research.
More SilentFlow scrapers
🛒 E-commerce
 Pinterest - Pinterest Scraper | Pins, Boards and Profiles
 Leboncoin - Leboncoin Scraper | Classified Ads, Prices and Sellers
 JD - JD Products Scraper | JD.com Prices, Brands and Barcodes
 Leboncoin - Leboncoin Ad Details Scraper
 TikTok Shop - TikTok Shop Scraper | Products, Sellers and Creator Videos
 Back Market - Back Market Scraper | Refurbished Prices
 ImportYeti - US Customs Records, Suppliers & Trade Data - ImportYeti Scraper - US Customs Records, Suppliers & Trade Data
 Naver - Naver Scraper | Shopping Products, Prices and Reviews
 Udemy Course - Udemy Course Scraper
 1688 - 1688 Scraper | Products, Details, Wholesale Prices, Suppliers
 Naver - Naver Products Scraper | Shopping Prices, Sellers and Ratings
 Amazon Seller - Amazon Seller Scraper | Emails, Phones and Ratings
 Naver - Naver Reviews Scraper | Shopping Product Reviews
 Store Leads Ecommerce - Store Leads Ecommerce Scraper
 Store Leads - Store Leads Scraper | Shopify Data
 Leboncoin - Leboncoin Scraper
 Bring a Trailer - Bring a Trailer Scraper
 Coupang - Coupang Detail Scraper | Product Prices and Options
 Lowes - Lowes Products Scraper | Prices, Stock and Specs
 Mobile.de - Mobile.de Scraper
 Taobao - Taobao Scraper | Products, Details, Prices and Sellers
 Alibaba - Alibaba Products Scraper | Wholesale Prices and MOQ
 Allegro - Allegro Scraper | Products, Prices and Sellers
 Avito - Avito Scraper | Listings, Prices and Sellers
 Udemy - Udemy Scraper
 Agoda - Agoda Scraper | Hotel Prices and Guest Ratings
 Alibaba - Alibaba Scraper | Products, Supplier Companies and Prices
 AliExpress - AliExpress Reviews Scraper | Feedback, Ratings and Photos
 AliExpress - AliExpress Scraper | Products, Prices and Sales
 Avito - Avito Profiles Scraper | Sellers, Ratings and Reviews
 Back Market - Back Market Scraper | Refurbished Electronics Prices
 BAUHAUS - BAUHAUS Scraper | Product Prices, EAN and Specs
 CARFAX - CARFAX Scraper | Used Cars, Prices and History
 eBay Marketplace - eBay Marketplace Scraper
 Europages - Europages Scraper | Suppliers and B2B Companies
 Eventim - Eventim Scraper | Events, Ticket Prices and Venues
 Goofish - Goofish Detail Scraper | Listings, Prices and Sellers
 Google Hotels - Google Hotels Scraper | Prices, Offers and Ratings
 Homedepot - Homedepot Reviews Scraper | Customer Reviews and Ratings
 Leboncoin - Leboncoin Details Scraper | Full Ad Data and Sellers
 Mafengwo - Mafengwo Scraper | Attractions, Ratings and Tickets
 Mercari - Mercari Scraper | Listings, Sold Prices and Sellers
 Pinterest - Pinterest Scraper
 Vinted Marketplace - Vinted Marketplace Scraper
 Webmotors - Webmotors Scraper | Car Listings, Prices and FIPE
 Amazon - Amazon Product Scraper
 Amazon Marketplace - Amazon Marketplace Scraper
 AutoScout24 - AutoScout24 Scraper
 eBay Listings - eBay Listings Scraper
 Europages Deep Dive Extractor - Europages Deep Dive Extractor | VAT, Decision Makers, ISO Certs
 GasBuddy - GasBuddy Scraper | Gas Prices by Station
 Trip - Trip Scraper | Hotels, Prices and Reviews
 Vinted - Vinted Scraper
 Walmart - Walmart Scraper | Prices, Reviews, Sellers, Availability
 Walmart - Walmart Product Scraper
💼 Jobs
 ZipRecruiter - ZipRecruiter Jobs Scraper | Salary, Company & Location Filters
 Indeed - Indeed Company Reviews Scraper
 Multi Board - Multi Board Job Scraper
 Glassdoor Job Listings - Glassdoor Job Listings Scraper
 🔥 Glassdoor - 🔥 Glassdoor Scraper
 Jora - Jora Jobs Scraper
 Malt Freelancer - Malt Freelancer Scraper
 Malt - Malt Scraper | Freelance Profiles
 ATS - ATS Jobs Scraper | Greenhouse, Lever and Ashby
 Glassdoor - Glassdoor Jobs Scraper
 LinkedIn Job Search - LinkedIn Job Search Scraper | Salaries & Seniority
 Welcome to the Jungle - Welcome to the Jungle Job Scraper
 All - All Jobs Scraper
 Arbeitsagentur - Arbeitsagentur Jobs Scraper
 Cutshort - Cutshort Jobs Scraper | Salaries, Skills and Companies
 Dice - Dice Jobs Scraper | US Tech Jobs, Salaries, Skills
 Dice Tech - Dice Tech Jobs Scraper
 iimjobs - iimjobs Jobs Scraper | MBA, Finance and Hirist Tech Jobs
 Indeed - Indeed Jobs Scraper | Job Listings in 73 Countries
 Instahyre - Instahyre Jobs Scraper | Companies, Recruiters and Ratings
 Jobright - Jobright Scraper | Jobs, Salaries and H1B Sponsors
 Jora - Jora Scraper | Jobs in Australia, New Zealand, Singapore
 StepStone - StepStone Scraper
 YCombinator - YCombinator Jobs Scraper | Startup Jobs, Salaries and Founders
 Arbeitsagentur - Arbeitsagentur Scraper | German and Austrian Job Board
 iimjobs - iimjobs Scraper | Jobs, Companies and Recruiters
 Indeed - Indeed Companies Scraper | Reviews, Salaries, Interviews
 Indeed - Indeed Jobs Scraper | NLP Skills
 LinkedIn - LinkedIn Jobs Scraper
 Naukri & NaukriGulf - Naukri & NaukriGulf Jobs Scraper
 Seek - Seek Job Scraper
 Welcome to the Jungle - Welcome to the Jungle Scraper | Jobs and Company Data
 Ziprecruiter - Ziprecruiter Scraper
🏠 Real estate
 SeLoger - SeLoger Scraper | Real Estate Listings
 Realtor Rental Listings - Realtor Rental Listings Scraper
 Airbnb Pro Host Contact & - Airbnb Pro Host Contact & Email Scraper
 Airbnb Professional Host - Airbnb Professional Host Scraper | Emails, Phones, SIRET
 Bien'ici - Bien'ici Scraper | Property Listings
 Rightmove - Rightmove Scraper
 Trulia Rental Listings - Trulia Rental Listings Scraper
 SeLoger - SeLoger Scraper | French Property Listings and Agencies
 Airbnb Search - Airbnb Search Scraper
 Bienici - Bienici Scraper
 Idealista - Idealista Scraper
 Realestate.com.au - Realestate.com.au Scraper
 Airbnb Search - Airbnb Search Scraper | Prices, Fees, Amenities, Hosts
 Anjuke - Anjuke Scraper | Rental Listings, Prices and Agents
 Idealista - Idealista Scraper
 Realtor Rental - Realtor Rental Scraper
 Trulia Rental - Trulia Rental Scraper | US Rentals, Prices, Pet Policy
 Zillow - Zillow Scraper
📣 Social media
 LinkedIn Post Search - LinkedIn Post Search Scraper | Keywords, Hashtags & Profiles
 Facebook Search - Facebook Search Scraper
 Instagram - Instagram Story Scraper | Stories & Highlights
 LinkedIn Leads - LinkedIn Leads Scraper | Sales Navigator Export
 YouTube - YouTube Channel Scraper | Videos, Shorts and Views
 Facebook Search - Facebook Search Profiles Scraper | People by Name or Keyword
 TikTok - TikTok Scraper
 Instagram Engagement - Instagram Engagement Scraper
 OnlyFans - OnlyFans Profile Scraper
 TikTok Trend - TikTok Trend Scraper | Trending Hashtags and Videos
 Meta Ad Library - Meta Ad Library Scraper
 OnlyFans - OnlyFans Creator Scraper
 Skool Community - Skool Community Scraper
 Discord - Discord Scraper | Servers, Member Counts and Invites
 Douyin - Douyin Comments Scraper | Comments, Likes and IP Regions
 Facebook Thread - Facebook Thread Profiles Scraper | Followers, Bios & Engagement
 Kuaishou - Kuaishou Scraper | Videos, Comments and Creator Stats
 Likee - Likee Scraper | Videos, Hashtags and Creators
 LinkedIn Ads Library - No Cookies - LinkedIn Ads Library Scraper - No Cookies
 LinkedIn Event - LinkedIn Event Scraper
 LinkedIn Hashtag & - LinkedIn Hashtag & Post Scraper | No Cookies
 Pinterest - Pinterest Ads Scraper | Ad Library, Reach & Targeting
 Pinterest - Pinterest Profiles Scraper | Followers, Emails and Bios
 Pinterest - Pinterest Videos Scraper | Video Downloader, MP4 Links, Stats
 Reddit - Reddit Comments Scraper | Search, Threads and Replies
 Reddit - Reddit Profiles Scraper | User Karma, Activity and Communities
 Reddit - Reddit Scraper | Posts, Comments and Subreddits
 Reddit - Reddit Scraper | Comments, Posts and Users
 RedNote - RedNote Detail Scraper | Xiaohongshu Details, Images, Videos
 RedNote - RedNote Videos Scraper | Downloader, Transcripts and Stats
 Snapchat - Snapchat Contacts Scraper | Phones, Emails and Websites
 Snapchat - Snapchat Videos Scraper | Spotlight Videos, MP4 and Stats
 TikTok Lookalike - TikTok Lookalike Scraper | Influencers, Emails and Engagement
 TwitchTracker - TwitchTracker Scraper | Twitch Streamer Stats and Rankings
 Weibo - Weibo Scraper | Posts, Profiles and Engagement
 Xigua - Xigua Scraper | Videos, Creators and Downloads
 YouTube Autocomplete - YouTube Autocomplete Scraper | Keyword Suggestions
 Facebook - Facebook Company Scraper | Emails, Phones, Ratings
 Facebook Business Page - Facebook Business Page Scraper
 Kwai - Kwai Scraper | Videos, Creators and Hashtags
 Skool Group - Skool Group Scraper
 Snapchat - Snapchat Ads Scraper | Ad Library, Impressions & Targeting
 YouTube - YouTube Transcript Scraper
🏢 Business data
 Tencent - Tencent Scraper | Maps Places, Phones and Ratings
 LinkedIn Company Search - LinkedIn Company Search Scraper | Profiles & Firmographics
 LinkedIn People Search - LinkedIn People Search Scraper | Profiles & Companies
 Justdial - Justdial Companies Scraper | Business Leads, Phones and Emails
 Bilibili - Bilibili Scraper | Videos, Profiles, Comments, Danmaku
 Company Data - Company Data Scraper | Emails, Phones and Tech Stack
 Ctrip - Ctrip Scraper | Attractions, Tickets and Reviews
 FanDuel - FanDuel Scraper | Odds, Spreads and Player Props
 ForexFactory - ForexFactory Scraper | Economic Calendar and Forecasts
 Kakao - Kakao Scraper | Map Places, Reviews and Phones
 LinkedIn Sales Navigator - LinkedIn Sales Navigator Scraper
 OpenTable - OpenTable Reviews Scraper | Restaurant Reviews and Ratings
 SoftwareAdvice - SoftwareAdvice Scraper | Reviews, Ratings and Pros & Cons
 Teachable Course - Teachable Course Scraper
 Website Tech Stack - Website Tech Stack Scraper
 Zomato - Zomato Reviews Scraper | Restaurant Ratings and Replies
 2GIS - 2GIS Reviews Scraper | Ratings, Photos and Owner Replies
 Teachable - Courses, Prices & Instructors - Teachable Scraper - Courses, Prices & Instructors
 Trustpilot - Trustpilot Scraper | Reviews, Ratings and Company Contacts
✈️ Travel
 Google Maps - Google Maps Scraper
 Flight Price - Flight Price Scraper
 Booking.com Hotel - Booking.com Hotel Scraper
 Trip - Trip Reviews Scraper | Hotel Reviews and Ratings
 Booking - Booking Scraper | Hotel Prices, Photos, Availability
🎯 Lead generation
 Northdata - Northdata Company Scraper
 ZocDoc - ZocDoc Scraper | Doctors, Reviews and Availability
 Dealroom - Dealroom Scraper | Companies and Investors
 UK Companies House - UK Companies House Enricher
 CNPJ Brazilian - CNPJ Brazilian Company Enricher
 Google Ads Transparency - Google Ads Transparency Scraper
 BuiltWith - BuiltWith Scraper | Tech Stacks and Top Sites
 Domain - Domain Enricher
 French Company Prospector - French Company Prospector
 PagesJaunes - PagesJaunes Scraper | French Business Emails and SIRET
 SEC - SEC Scraper | EDGAR Filings and Company Data
 SIRET - SIRET Company Enricher
 USPTO - USPTO Scraper | Trademark Search and Status
 Clutch - Clutch Scraper | Agencies, Reviews, Ratings, Services
 Clutch Agency - Clutch Agency Scraper
 Dealroom Startup Data - Dealroom Startup Data Scraper
 G2 - G2 Reviews Scraper
 PagesJaunes - PagesJaunes Business Scraper
 SIRET French - SIRET French Company Enricher
 ThomasNet Suppliers - ThomasNet Suppliers Scraper
 ZocDoc - ZocDoc Scraper
🔎 SEO
 Similarweb - Similarweb Scraper | Website Traffic, Rankings and Competitors
 Apple - Apple Scraper | App Store Apps, Ratings and Charts
📈 Marketing
 Pexels - Pexels Scraper | Photos, Videos and Download Stats
 Douyin - Douyin Transcript Scraper | Subtitles and Speech to Text
🧰 More tools
 Apple - Apple Reviews Scraper | App Store Reviews and Ratings
 PrizePicks - PrizePicks Scraper | Player Props, Lines and Projections
📬 Support
Need something this scraper doesn't do yet? We ship features fast.
- Feature requests go straight to our backlog
- Enterprise needs? We do custom integrations and high-volume plans
- Pricing questions? Check the Monetization tab on the actor page
Response time: usually under 24 hours.
Check out our other scrapers: silentflow on Apify


