
Teachable Course Scraper
Pricing
from $3.80 / 1,000 results
Teachable Course Scraper
Scrape every course from any Teachable school: title, price, original price, currency, instructor, enrolled students, rating, reviews and the section-by-section curriculum. Reads both catalogue layouts and custom domains. Paste a school URL or specific course URLs. Export JSON, CSV or Excel.
Pricing
from $3.80 / 1,000 results
Rating
0.0
(0)
Developer
SilentFlow
Maintained by CommunityActor stats
1
Bookmarked
2
Total users
1
Monthly active users
5 days ago
Last modified
Share
From SilentFlow. Creators of Facebook Search Scraper and Pinterest Scraper, with 590,000+ combined lifetime runs.
Turn any Teachable school into a structured course catalog. Prices, instructors, enrolment numbers, ratings and the full lesson outline for every course a school sells. A 36 course school in about three minutes.
How it works
Three steps, no setup.
- Paste a school URL. Anything that shows courses in your browser works:
https://yourschool.teachable.com, its/coursespage, its/l/productscatalog, or a custom domain. - Press Start. The Actor walks the catalog, then opens each course to read its price, instructor, outline and reviews.
- Take your rows. One row per course, 31 fields each, ready to view in a table or pull as JSON, CSV or Excel.
Already know which courses you want? Give it course URLs instead and skip the catalog entirely.
✨ Why teams choose this over other Teachable scrapers
Ever pointed a scraper at a school and got nothing back, with no idea whether the school was empty or the tool had failed? Ever built a price list, then found half the prices missing? Ever needed the lesson outline and got only a title?
- 🏫 Reads both kinds of Teachable catalog. Teachable runs two catalog templates side by side, the older
/coursesgrid and the newer/l/productsone, and a school serves whichever it was built with. This Actor reads both. On a modern catalog that returns nothing elsewhere, it returned all 27 listings. - 📚 Gets the whole catalog, not part of it. A school's grid links its courses in two different ways, and reading only one of them quietly drops the rest. On a 36 course school, that is the difference between 36 rows and 14. Both forms are followed, and the same course is never billed twice.
- 💵 Prices you can trust. The price comes from the pricing plans the course page publishes, with the currency, and the cheapest paid plan when a course offers several. A paid course is never reported as free, and a
$49course never arrives as$4,900. - 🧭 The lesson outline, section by section. Every course carries its curriculum: section titles, their order, and the number of lessons in each. One course came back with 29 lessons across 7 sections, another with 83 across 21.
- 👤 The person behind the course. Instructor name, bio, title and avatar, pulled from the school's own instructor block, so you can qualify a creator and not just a listing.
- 🔍 An empty run tells you why. When a run returns nothing it says whether the school lists no courses publicly or its pages could not be read. You never have to guess which.
- 🌐 Subdomains and custom domains both work. Plenty of schools run on their own domain. Paste whichever URL your browser shows.
- 🎯 Point it at courses, not just schools. Mix school URLs and direct course URLs in the same run, in either page style.
🎯 What you can do with Teachable data
| Team | What they build |
|---|---|
| Pricing | A benchmark of what courses in one niche actually charge, with original prices next to current ones, before setting their own |
| Growth | Lead lists of course creators worth partnering with, filtered by student count, topic and whether they sell paid or free courses |
| Content | Curriculum gap analysis across rival schools: which sections everyone teaches, and the 29 lesson course that goes deeper than your 9 lesson one |
| Marketplace | A course directory that refreshes itself, with titles, prices, thumbnails, instructors and descriptions for every listing |
| Affiliate | Catalog pages built from real listings, so a retired course stops earning clicks that go nowhere |
| Research | Datasets on the creator economy: price distribution, catalog size and enrolment per school across a sample of schools |
| Sales | Qualified outreach to creators, using their own course topics, audience size and ratings as the opening line |
| Competitive | A weekly snapshot of a rival school, so a new launch or a price change shows up as a diff |
📥 Input parameters
| Parameter | Type | Default | Description |
|---|---|---|---|
schoolUrls | array | Teachable schools to scrape. A homepage, a /courses page, a /l/products catalog, or a custom domain | |
courseUrls | array | Direct course URLs, in either page style: /p/course-name or /l/pdp/course-name | |
scrapeDetails | boolean | true | Open each course for its price, instructor, outline, rating and reviews. Turn it off for a fast catalog of titles and links |
scrapeSalesPage | boolean | false | Also keep the sales page copy as text, for marketing and positioning analysis |
maxItems | integer | 100 | Stop after this many courses. Set it to what you actually need |
Give it schoolUrls, courseUrls, or both.
📊 Output data
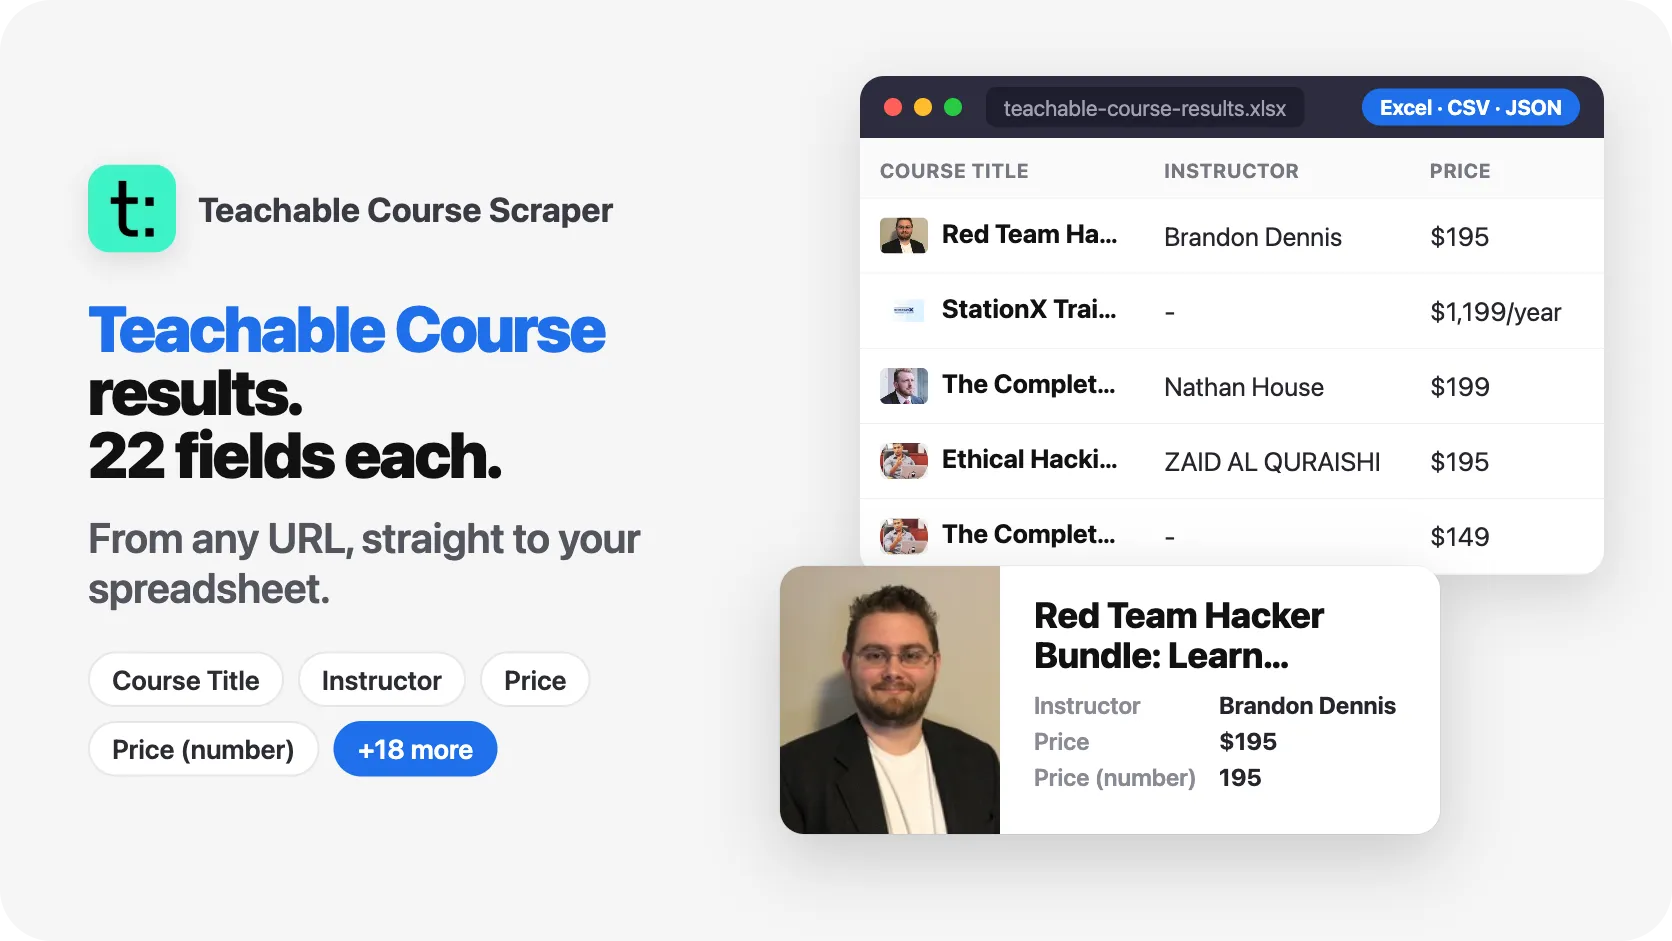
One row per course. Every field is what a visitor sees on the school's public pages.
A course from a modern catalog carries its outline:
🗂️ Data fields
31 fields per course. Empty fields are omitted rather than filled with a guess.
| Group | Fields |
|---|---|
| Identity | id, title, slug, url, schoolName, schoolUrl, scrapedAt |
| Text | description, shortDescription, salesPageContent |
| Price | price, originalPrice, priceText, currency, isFree |
| Audience | studentsCount, reviewsCount, averageRating |
| Content | lessonsCount, curriculum, category, subCategory, tags |
| Instructor | instructorName, instructorTitle, instructorBio, instructorAvatar |
| Media | thumbnail, promoVideo, images |
| Reviews | testimonials |
Nested objects carry more:
curriculumis a list of sections, 4 fields each:title,lessonsCount,position,lectures.lectures, where the school publishes them, holds 5 fields per lesson:title,type,duration,isFree,position.testimonialsholds 5 fields per review:author,content,rating,date,avatar.
Usability notes: id is Teachable's own course or product id and is stable. url is permanent. scrapedAt is UTC in RFC 3339. priceText is the string the page displays, such as $195, $1,199/year or FREE, while price is the number, so a yearly plan is readable both ways. category is Teachable's own label for the listing: Course, Digital product or Collection.
🚀 Examples
Get every course in a school
Scrape a school on the newer catalog
Pull a fast catalog without opening every course
Read three specific courses you already know
Keep the sales page copy for positioning analysis
Benchmark several schools in one run
| SilentFlow · Teachable Course suite | |
 Teachable Course Scraper You are here |  Teachable Scraper - Courses, Prices & Instructors Teachable Scraper - Courses, |
🤖 Copy to your AI assistant
Paste this into Claude, ChatGPT or Cursor to give it full context about this Actor:
💻 Integrations
Build a course price benchmark in Python
Build a creator lead list in Node.js
Export a catalog to CSV for the content team
Watch one school on a schedule with the Apify CLI
📤 Data export
Results are available on the dataset page as JSON, CSV, Excel, XML, HTML and RSS, and through the API:
The dataset also has a Courses view, which shows the columns most people want first: title, instructor, price, lessons, students, rating and link.
📈 Performance
Measured on 12 September 2026:
| Run | Result |
|---|---|
| 36 course school, full details | 36 of 36 courses, every page read, about 3 minutes |
| Modern catalog, full details | 27 listings found, details at roughly 2 seconds per course |
Catalog only, scrapeDetails: false | 5 courses in 1 second |
Catalog reads are a single page per school. Detail reads are one page per course, so a run's length tracks maxItems almost exactly.
💡 Tips for best results
- Paste the URL that works in your browser. If your browser shows the courses, the Actor will too. The homepage, the
/coursespage and the/l/productscatalog all resolve to the same catalog. - Turn off
scrapeDetailsto map a school first. You get titles, links and thumbnails in one page read, then run again with details only for the courses you care about. - Set
maxItemsto the size of the job. A school with 30 courses does not need a ceiling of 5,000, and the run length follows the number you set. - Use
courseUrlsfor monitoring. Once you know the courses you track, naming them directly is faster and steadier than walking a catalog that reorders itself. - Check
priceTextwhen a course has several plans.priceholds the cheapest paid plan as a number;priceTextkeeps the wording, so$1,199/yearstays legible as a yearly plan. - Read the run's final message when a run is empty. It distinguishes a school that lists nothing publicly from pages that could not be read, and only the second is worth running again.
❓ FAQ
Q: What exactly does it extract? Everything a visitor can see without logging in: the course catalog, and for each course its title, description, price and currency, original price, free flag, instructor details, student and review counts, rating, product type, thumbnail, testimonials, and the curriculum outline. Optionally the sales page copy.
Q: Do I need a Teachable account? No. No login, no API key.
Q: Will it work on my school? Yes, on both catalog templates Teachable serves and on custom domains. If your courses are visible to a visitor, they are readable.
Q: How do I scrape only some courses?
Put their URLs in courseUrls. Both page styles are accepted, /p/course-name and /l/pdp/course-name. You can mix courseUrls and schoolUrls in one run.
Q: How fresh is the data? It is read live at the moment of the run. Nothing is cached, so a price changed this morning is the price you get.
Q: Why does a course sometimes have no price? Some schools send their course pages to their own website instead of keeping them on Teachable, and a page on a school's own site states its price however its theme happens to. When no price can be read from the page, the field is left empty rather than filled with a number found somewhere on the page. Every other field still ships.
Q: Why do some courses have section titles but no individual lessons?
On the newer course page, a section reveals its lessons only when a visitor expands it, so the section title, its position and its lesson count are published but the lesson titles are not. Older sales pages publish the full lesson list, and it comes back in lectures.
Q: Can I scrape several schools at once?
Yes. Put as many as you like in schoolUrls. maxItems applies to the run as a whole, so raise it when you add schools.
Q: What happens with a school that is switched off or empty? A switched off school answers normally and lists nothing, so the run finishes with no rows and says so in its final message. That is the honest answer rather than an error.
Q: Does maxItems count catalog pages or courses?
Courses. It is the number of rows you get.
Q: Are the image and video URLs permanent?
thumbnail and images point at the school's own media and stay valid as long as the school keeps them. url is permanent.
Q: What is Teachable? Teachable is a platform where independent creators host and sell their own online courses, each school on its own subdomain or custom domain. It is the counterpart to a marketplace like Udemy, except the catalog belongs to the creator rather than to a central storefront, which is why there is no single place to query and why per school scraping is the way to see it.
⚖️ Legal
This Actor extracts publicly available data from Teachable schools. It does not bypass any login, paywall or CAPTCHA, and it does not access course content that requires enrolment. Users are responsible for complying with Teachable's terms of service and with applicable data protection laws, including GDPR and CCPA. The output contains personal data where a school publishes it, such as instructor names, bios and avatars, and reviewer names in testimonials, and must be handled accordingly. The data returned is informational; verify it before using it for regulated purposes.
🔗 Related scrapers
- Udemy Scraper for the marketplace side of online courses
- YouTube Transcript Scraper to turn a creator's free content into text
- Instagram Engagement Scraper to size up a creator's audience
- LinkedIn Profiles & Companies Scraper to enrich a creator lead list
More SilentFlow scrapers
🛒 E-commerce
 Pinterest - Pinterest Scraper | Pins, Boards and Profiles
 JD - JD Products Scraper | JD.com Prices, Brands and Barcodes
 Leboncoin - Leboncoin Scraper | Classified Ads, Prices and Sellers
 Leboncoin - Leboncoin Ad Details Scraper
 TikTok Shop - TikTok Shop Scraper | Products, Sellers and Creator Videos
 Back Market - Back Market Scraper | Refurbished Prices
 ImportYeti - US Customs Records, Suppliers & Trade Data - ImportYeti Scraper - US Customs Records, Suppliers & Trade Data
 Naver - Naver Scraper | Shopping Products, Prices and Reviews
 Udemy Course - Udemy Course Scraper
 Naver - Naver Products Scraper | Shopping Prices, Sellers and Ratings
 1688 - 1688 Scraper | Products, Details, Wholesale Prices, Suppliers
 Amazon Seller - Amazon Seller Scraper | Emails, Phones and Ratings
 Naver - Naver Reviews Scraper | Shopping Product Reviews
 Store Leads Ecommerce - Store Leads Ecommerce Scraper
 Store Leads - Store Leads Scraper | Shopify Data
 Allegro - Allegro Scraper | Products, Prices and Sellers
 Leboncoin - Leboncoin Scraper
 Lowes - Lowes Products Scraper | Prices, Stock and Specs
 Mobile.de - Mobile.de Scraper
 Taobao - Taobao Scraper | Products, Details, Prices and Sellers
 Agoda - Agoda Scraper | Hotel Prices and Guest Ratings
 Alibaba - Alibaba Products Scraper | Wholesale Prices and MOQ
 Avito - Avito Scraper | Listings, Prices and Sellers
 Bring a Trailer - Bring a Trailer Scraper
 Eventim - Eventim Scraper | Events, Ticket Prices and Venues
 Homedepot - Homedepot Reviews Scraper | Customer Reviews and Ratings
 Pinterest - Pinterest Scraper
 Udemy - Udemy Scraper
 Alibaba - Alibaba Scraper | Products, Supplier Companies and Prices
 AliExpress - AliExpress Reviews Scraper | Feedback, Ratings and Photos
 AliExpress - AliExpress Scraper | Products, Prices and Sales
 Avito - Avito Profiles Scraper | Sellers, Ratings and Reviews
 Back Market - Back Market Scraper | Refurbished Electronics Prices
 BAUHAUS - BAUHAUS Scraper | Product Prices, EAN and Specs
 CARFAX - CARFAX Scraper | Used Cars, Prices and History
 Coupang - Coupang Detail Scraper | Product Prices and Options
 eBay Marketplace - eBay Marketplace Scraper
 Europages - Europages Scraper | Suppliers and B2B Companies
 Google Hotels - Google Hotels Scraper | Prices, Offers and Ratings
 Leboncoin - Leboncoin Details Scraper | Full Ad Data and Sellers
 Mafengwo - Mafengwo Scraper | Attractions, Ratings and Tickets
 Mercari - Mercari Scraper | Listings, Sold Prices and Sellers
 Vinted Marketplace - Vinted Marketplace Scraper
 Webmotors - Webmotors Scraper | Car Listings, Prices and FIPE
 Amazon - Amazon Product Scraper
 Amazon Marketplace - Amazon Marketplace Scraper
 AutoScout24 - AutoScout24 Scraper
 eBay Listings - eBay Listings Scraper
 Europages Deep Dive Extractor - Europages Deep Dive Extractor | VAT, Decision Makers, ISO Certs
 GasBuddy - GasBuddy Scraper | Gas Prices by Station
 Goofish - Goofish Detail Scraper | Listings, Prices and Sellers
 Trip - Trip Scraper | Hotels, Prices and Reviews
 Vinted - Vinted Scraper
 Walmart - Walmart Scraper | Prices, Reviews, Sellers, Availability
 Walmart - Walmart Product Scraper
💼 Jobs
 ZipRecruiter - ZipRecruiter Jobs Scraper | Salary, Company & Location Filters
 Indeed - Indeed Company Reviews Scraper
 Multi Board - Multi Board Job Scraper
 Glassdoor Job Listings - Glassdoor Job Listings Scraper
 Jobright - Jobright Scraper | Jobs, Salaries and H1B Sponsors
 LinkedIn Job Search - LinkedIn Job Search Scraper | Salaries & Seniority
 Malt Freelancer - Malt Freelancer Scraper
 Malt - Malt Scraper | Freelance Profiles
 🔥 Glassdoor - 🔥 Glassdoor Scraper
 Jora - Jora Jobs Scraper
 ATS - ATS Jobs Scraper | Greenhouse, Lever and Ashby
 Glassdoor - Glassdoor Jobs Scraper
 Arbeitsagentur - Arbeitsagentur Jobs Scraper
 Cutshort - Cutshort Jobs Scraper | Salaries, Skills and Companies
 Dice - Dice Jobs Scraper | US Tech Jobs, Salaries, Skills
 Dice Tech - Dice Tech Jobs Scraper
 iimjobs - iimjobs Jobs Scraper | MBA, Finance and Hirist Tech Jobs
 Indeed - Indeed Jobs Scraper | Job Listings in 73 Countries
 Instahyre - Instahyre Jobs Scraper | Companies, Recruiters and Ratings
 Jora - Jora Scraper | Jobs in Australia, New Zealand, Singapore
 StepStone - StepStone Scraper
 Welcome to the Jungle - Welcome to the Jungle Job Scraper
 YCombinator - YCombinator Jobs Scraper | Startup Jobs, Salaries and Founders
 All - All Jobs Scraper
 Arbeitsagentur - Arbeitsagentur Scraper | German and Austrian Job Board
 iimjobs - iimjobs Scraper | Jobs, Companies and Recruiters
 Indeed - Indeed Companies Scraper | Reviews, Salaries, Interviews
 Indeed - Indeed Jobs Scraper | NLP Skills
 LinkedIn - LinkedIn Jobs Scraper
 Naukri & NaukriGulf - Naukri & NaukriGulf Jobs Scraper
 Seek - Seek Job Scraper
 Welcome to the Jungle - Welcome to the Jungle Scraper | Jobs and Company Data
 Ziprecruiter - Ziprecruiter Scraper
🏠 Real estate
 SeLoger - SeLoger Scraper | Real Estate Listings
 Realtor Rental Listings - Realtor Rental Listings Scraper
 Airbnb Professional Host - Airbnb Professional Host Scraper | Emails, Phones, SIRET
 Airbnb Pro Host Contact & - Airbnb Pro Host Contact & Email Scraper
 Trulia Rental Listings - Trulia Rental Listings Scraper
 Bien'ici - Bien'ici Scraper | Property Listings
 Rightmove - Rightmove Scraper
 SeLoger - SeLoger Scraper | French Property Listings and Agencies
 Airbnb Search - Airbnb Search Scraper
 Bienici - Bienici Scraper
 Idealista - Idealista Scraper
 Realestate.com.au - Realestate.com.au Scraper
 Airbnb Search - Airbnb Search Scraper | Prices, Fees, Amenities, Hosts
 Anjuke - Anjuke Scraper | Rental Listings, Prices and Agents
 Idealista - Idealista Scraper
 Realtor Rental - Realtor Rental Scraper
 Trulia Rental - Trulia Rental Scraper | US Rentals, Prices, Pet Policy
 Zillow - Zillow Scraper
📣 Social media
 LinkedIn Post Search - LinkedIn Post Search Scraper | Keywords, Hashtags & Profiles
 Facebook Search - Facebook Search Scraper
 Instagram - Instagram Story Scraper | Stories & Highlights
 LinkedIn Leads - LinkedIn Leads Scraper | Sales Navigator Export
 Facebook Search - Facebook Search Profiles Scraper | People by Name or Keyword
 YouTube - YouTube Channel Scraper | Videos, Shorts and Views
 TikTok - TikTok Scraper
 Instagram Engagement - Instagram Engagement Scraper
 OnlyFans - OnlyFans Profile Scraper
 TikTok Trend - TikTok Trend Scraper | Trending Hashtags and Videos
 Discord - Discord Scraper | Servers, Member Counts and Invites
 Likee - Likee Scraper | Videos, Hashtags and Creators
 Meta Ad Library - Meta Ad Library Scraper
 OnlyFans - OnlyFans Creator Scraper
 Skool Community - Skool Community Scraper
 TikTok Lookalike - TikTok Lookalike Scraper | Influencers, Emails and Engagement
 Douyin - Douyin Comments Scraper | Comments, Likes and IP Regions
 Facebook Thread - Facebook Thread Profiles Scraper | Followers, Bios & Engagement
 Kuaishou - Kuaishou Scraper | Videos, Comments and Creator Stats
 LinkedIn Ads Library - No Cookies - LinkedIn Ads Library Scraper - No Cookies
 LinkedIn Event - LinkedIn Event Scraper
 LinkedIn Hashtag & - LinkedIn Hashtag & Post Scraper | No Cookies
 Pinterest - Pinterest Ads Scraper | Ad Library, Reach & Targeting
 Pinterest - Pinterest Profiles Scraper | Followers, Emails and Bios
 Pinterest - Pinterest Videos Scraper | Video Downloader, MP4 Links, Stats
 Reddit - Reddit Comments Scraper | Search, Threads and Replies
 Reddit - Reddit Profiles Scraper | User Karma, Activity and Communities
 Reddit - Reddit Scraper | Posts, Comments and Subreddits
 Reddit - Reddit Scraper | Comments, Posts and Users
 RedNote - RedNote Videos Scraper | Downloader, Transcripts and Stats
 Snapchat - Snapchat Contacts Scraper | Phones, Emails and Websites
 Snapchat - Snapchat Videos Scraper | Spotlight Videos, MP4 and Stats
 TikTok Creative - TikTok Creative Ads Scraper | Top Ads, Landing Pages & Metrics
 Weibo - Weibo Scraper | Posts, Profiles and Engagement
 Xigua - Xigua Scraper | Videos, Creators and Downloads
 YouTube Autocomplete - YouTube Autocomplete Scraper | Keyword Suggestions
 Facebook - Facebook Company Scraper | Emails, Phones, Ratings
 Facebook Business Page - Facebook Business Page Scraper
 Kwai - Kwai Scraper | Videos, Creators and Hashtags
 RedNote - RedNote Detail Scraper | Xiaohongshu Details, Images, Videos
 Skool Group - Skool Group Scraper
 Snapchat - Snapchat Ads Scraper | Ad Library, Impressions & Targeting
 TwitchTracker - TwitchTracker Scraper | Twitch Streamer Stats and Rankings
 YouTube - YouTube Transcript Scraper
🏢 Business data
 Tencent - Tencent Scraper | Maps Places, Phones and Ratings
 LinkedIn Company Search - LinkedIn Company Search Scraper | Profiles & Firmographics
 LinkedIn People Search - LinkedIn People Search Scraper | Profiles & Companies
 Bilibili - Bilibili Scraper | Videos, Profiles, Comments, Danmaku
 Ctrip - Ctrip Scraper | Attractions, Tickets and Reviews
 LinkedIn Sales Navigator - LinkedIn Sales Navigator Scraper
 SoftwareAdvice - SoftwareAdvice Scraper | Reviews, Ratings and Pros & Cons
 Website Tech Stack - Website Tech Stack Scraper
 Zomato - Zomato Reviews Scraper | Restaurant Ratings and Replies
 2GIS - 2GIS Reviews Scraper | Ratings, Photos and Owner Replies
 Trustpilot - Trustpilot Scraper | Reviews, Ratings and Company Contacts
✈️ Travel
 Google Maps - Google Maps Scraper
 Flight Price - Flight Price Scraper
 Booking.com Hotel - Booking.com Hotel Scraper
 Kakao - Kakao Scraper | Map Places, Reviews and Phones
 OpenTable - OpenTable Reviews Scraper | Restaurant Reviews and Ratings
 TheFork - TheFork Scraper | Restaurants, Menus and Ratings
 Trip - Trip Reviews Scraper | Hotel Reviews and Ratings
 Booking - Booking Scraper | Hotel Prices, Photos, Availability
🎯 Lead generation
 Northdata - Northdata Company Scraper
 ZocDoc - ZocDoc Scraper | Doctors, Reviews and Availability
 Dealroom - Dealroom Scraper | Companies and Investors
 UK Companies House - UK Companies House Enricher
 CNPJ Brazilian - CNPJ Brazilian Company Enricher
 Google Ads Transparency - Google Ads Transparency Scraper
 Justdial - Justdial Companies Scraper | Business Leads, Phones and Emails
 PagesJaunes - PagesJaunes Scraper | French Business Emails and SIRET
 BuiltWith - BuiltWith Scraper | Tech Stacks and Top Sites
 Company Data - Company Data Scraper | Emails, Phones and Tech Stack
 Dealroom Startup Data - Dealroom Startup Data Scraper
 Domain - Domain Enricher
 French Company Prospector - French Company Prospector
 KVK - KVK Scraper | Dutch Companies and SBI Codes
 PagesJaunes - PagesJaunes Business Scraper
 SEC - SEC Scraper | EDGAR Filings and Company Data
 SIRET - SIRET Company Enricher
 SpyFu - SpyFu Scraper | SEO, PPC and Competitor Data
 Sunbiz - Sunbiz Scraper | Florida Companies and Officers
 USPTO - USPTO Scraper | Trademark Search and Status
 Clutch - Clutch Scraper | Agencies, Reviews, Ratings, Services
 Clutch Agency - Clutch Agency Scraper
 G2 - G2 Reviews Scraper
 SIRET French - SIRET French Company Enricher
 ThomasNet Suppliers - ThomasNet Suppliers Scraper
 ZocDoc - ZocDoc Scraper
🔎 SEO
 Similarweb - Similarweb Scraper | Website Traffic, Rankings and Competitors
 Apple - Apple Reviews Scraper | App Store Reviews and Ratings
 Apple - Apple Scraper | App Store Apps, Ratings and Charts
 Bing - Bing Enricher Scraper | Mobile Friendly Test and Indexing
 Google News - Google News Scraper
📈 Marketing
 Douyin -
🎬 Video
 Pexels -
📰 News
 ForexFactory - ForexFactory Scraper | Economic Calendar and Forecasts
🧰 More tools
 FanDuel - FanDuel Scraper | Odds, Spreads and Player Props
 PrizePicks - PrizePicks Scraper | Player Props, Lines and Projections
📬 Support
Need a field this Actor does not return yet, or a school shape it does not read? Tell us what you are trying to build and we ship quickly.


