
X Timeline Scraper | Tweets and Engagement Stats
Pricing
from $0.30 / 1,000 posts
X Timeline Scraper | Tweets and Engagement Stats
X (Twitter) timeline scraper: get the posts of any account without login, each tweet with full text, likes, reposts, replies, quotes, bookmarks, views, images, videos and the author's followers. The default run returned 40 posts in 3 seconds, 29 fields each. Many accounts per run, date filters.
Pricing
from $0.30 / 1,000 posts
Rating
0.0
(0)
Developer
SilentFlow
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
a day ago
Last modified
Categories
Share
X Timeline Scraper (Twitter) | Tweets, Likes, Views and Media from Any Account (2026)
From SilentFlow. Creators of Facebook Search Scraper and Pinterest Scraper, with 600,000+ combined lifetime runs.
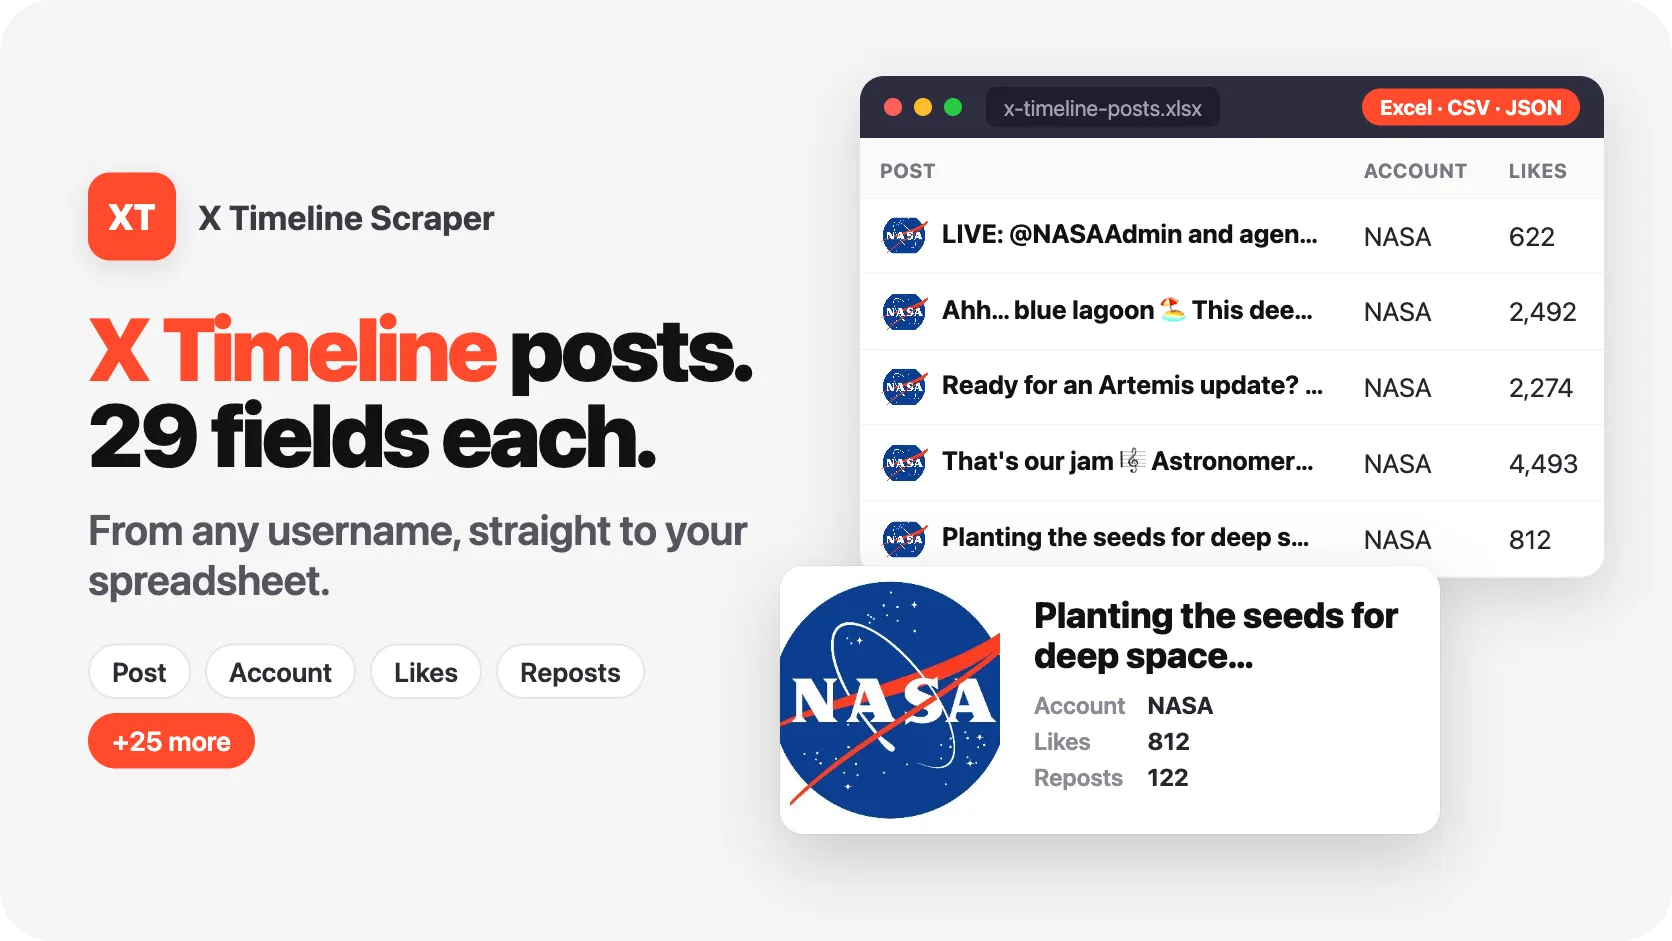
Every post an X (Twitter) account shows on its timeline, one clean row each, with the full text, the likes, reposts, replies, quotes, bookmarks and views, the images and videos, and the account's own numbers on the same row. Type a handle or paste a link, press Start: the prefilled form returned the 40 latest posts of NASA and SpaceX on our test run, with 28 data fields filled on at least half of the rows. No X account, no API key, no developer portal.
Why choose this actor?
Copying tweets into a spreadsheet one by one, and losing the view counts on the way? Running one job per account when you follow twenty? Getting a repost back as a cut-off "RT @..." line with zero likes?
- 28 filled data fields per post, the account included. Each row carries the post (id, link, full text, language, mentions, links), its engagement (likes, reposts, replies, quotes, bookmarks, views), its context (reply, repost and quote flags with the original post and author, pinned and sensitive flags), its media, and the account behind it (name, avatar, followers, following, post count, location, blue badge and verified type). On the default run (40 posts of NASA and SpaceX), 28 of the 39 data fields were filled on at least half the rows: 18 posts came with images, 8 with a video file, 24 with expanded links, and the 6 reposts carried the full text and engagement of the original post.
- Start from a handle, a profile link or the link of any post, for as many accounts as you need. Type
NASAor@OpenAI, pastehttps://x.com/SpaceX, or drop the link of a post you saw and the actor reads its author's timeline. One run with four accounts (NASA, SpaceX, OpenAI and Google), kept to the last 7 days without reposts, returned 52 posts on our test run. - Nothing to fill in before you press Start. No field is mandatory: one handle or one link is enough, the post cap has a default, and every filter is optional. The prefilled form, left as it is, returned 40 posts from 2 accounts.
Try your first X posts
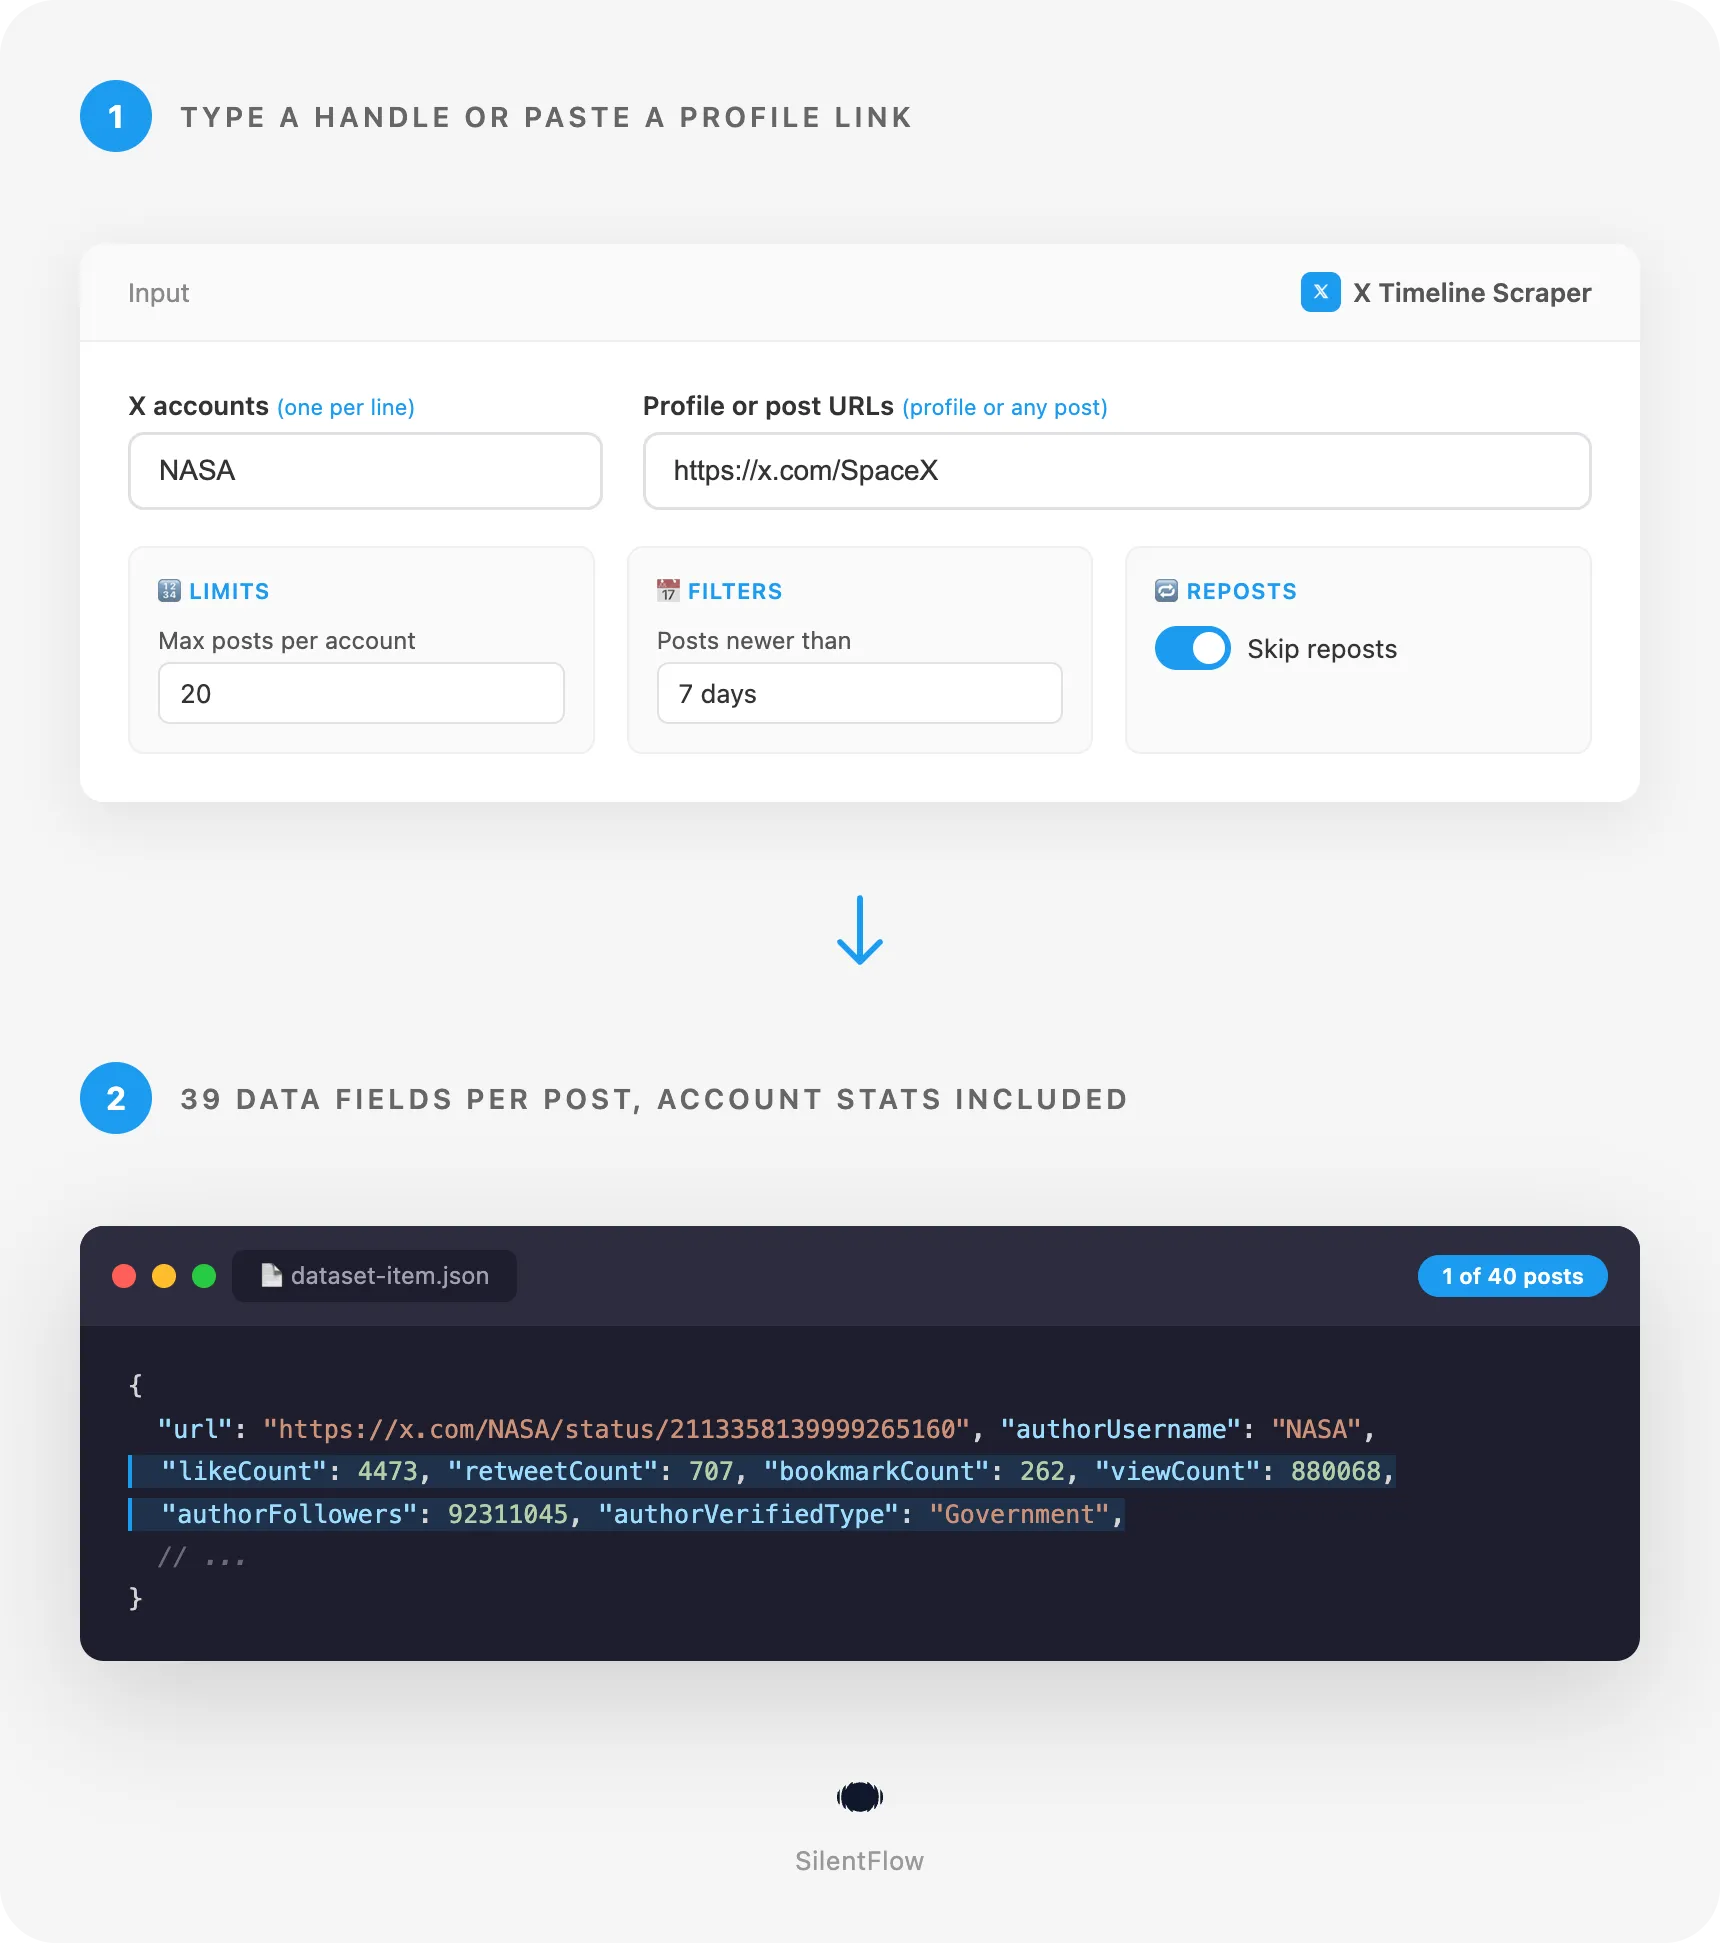
Paste this input in the JSON tab, or keep the prefilled form and press Start. It reads the 20 latest posts of NASA and of SpaceX, each with its text, engagement, media and the account's follower count, and finished in a few seconds on our test runs.
Runs on the Apify Free plan: sign up, open the actor, press Start. Each post lands as one row of the dataset, which you can open as a table, download as CSV, Excel or JSON, or read from the API. Swap NASA for the accounts you follow (a competitor, a public figure, a newsroom, your own brand) and the dataset fills with their posts instead.
Copy to your AI assistant
Paste this block into Claude, ChatGPT or Cursor to give it full context about this scraper:
How to scrape X (Twitter) posts from any account
Get the latest posts of one account
Type the handle as it appears on the profile, with or without the @. The posts come back newest first, the pinned post included and flagged.
Pull only what an account wrote itself
Switch reposts off to keep the account's own posts, threads and quotes. On our test run, OpenAI without reposts returned 60 posts over 4 timeline pages, the pinned post included.
Read a watch list for the last 7 days
List the accounts and an age. Each account stops being read as soon as its timeline goes past the date, so a daily or weekly schedule stays short. Four accounts over the last 7 days, without reposts, returned 52 posts on our test run: 18 from Google, 16 from SpaceX, 9 from NASA and 9 from OpenAI.
Input parameters
| Field | Type | Description |
|---|---|---|
usernames | array of strings | The accounts to read, one per line. NASA, @NASA and https://x.com/NASA all work. |
startUrls | array of { "url": ... } | x.com or twitter.com links: a profile, or the link of any post (the actor reads the timeline of the post's author). |
maxItems | integer, default 20 | Posts per account, newest first, from 1 to 3,200. |
onlyPostsNewerThan | string | Keep posts published on or after a date (2026-09-01, 2026-09-01T08:00:00Z) or within an age (24 hours, 7 days, 2 weeks, 3 months, 1 year). |
onlyPostsOlderThan | string | Keep posts published before a date or an age. With the field above it reads one period. |
excludeRetweets | boolean, default false | Leave out the posts the account reposted from others. |
excludePinned | boolean, default false | Leave out the post pinned at the top of the profile. |
debugMode | boolean, default false | Adds detailed lines to the run log. Leave it off for normal runs. |
Formats accepted for an account, in either field:
- a handle:
NASA,@NASA(1 to 15 letters, digits or underscores, case does not matter) - a profile link:
https://x.com/NASA,https://twitter.com/NASA,https://mobile.twitter.com/NASA,x.com/NASA/media - a post link:
https://x.com/NASA/status/2113358139999265160, which reads NASA's timeline
The same account typed twice, in two spellings, is read once. An entry that is not an X account (a Google link, a 30-character name) is skipped with a line in the log and the rest of the run goes on.
What data can you extract from X?
One row per post, 40 keys: 39 data fields and the time of the run. Lists come back as [] when empty and values X does not publish for a post are null, never an empty text.
| Group | Fields |
|---|---|
| Identity (2) | id, url |
| Content (5) | text, lang, hashtags, mentions, links |
| Account (10) | authorId, authorUsername, authorName, authorAvatar, authorFollowers, authorFollowing, authorPostsCount, authorLocation, isAuthorBlueVerified, authorVerifiedType |
| Engagement (6) | likeCount, retweetCount, replyCount, quoteCount, bookmarkCount, viewCount |
| Context (13) | conversationId, isReply, inReplyToId, inReplyToUsername, isRetweet, retweetedPostId, retweetedUsername, isQuote, quotedPostId, quotedUsername, quotedText, isPinned, isSensitive |
| Time (1) | createdAt (RFC 3339, UTC) |
| Media (2) | images, videos |
| Meta (1) | scrapedAt (RFC 3339, UTC) |
Output example
A post of NASA from the default run, as it lands in the dataset:
A quote post of SpaceX from the same run carries the post it quotes (account block left out here):
Good to know when you store the data:
idis X's own post id andurlthe permanent link of the post: both are stable keys to join runs on.authorIdnever changes, even when an account renames its handle.textis the whole post, not the preview: on the September run of OpenAI, 30 of the 64 posts were longer than 280 characters and came back complete. Short links are expanded to their real address, and a reply loses the leading list of @handles that X adds in front of it.- A repost is a row of the account that reposted it:
createdAtis the time of the repost (the order of the timeline), whiletext, the engagement and the media are those of the original post, with its id and author inretweetedPostIdandretweetedUsername. - Engagement counts are the exact numbers X publishes (
4473likes, not "4.4K"), read at the time of the run. imagesandvideosare direct links to X's media servers, the best quality offered for each video. They stop working when the post is deleted, so download the files you want to keep.viewCountisnullon posts published before X started counting views at the end of 2022: 34 of the 100 posts elonmusk showed on our test run were that old.langisnullon a post with no words (a photo alone, a link alone).
Advanced usage
Monitor a list of accounts every morning
Schedule this input daily. Each run returns only the posts of the last 24 hours, and each account stops being read once its timeline is older, so a long watch list stays quick.
Archive one month of an account from a post link
Paste the link of any post of the account and set both ends of the period. On our test run, September 2026 of OpenAI, started from one of its posts, returned 64 posts over 6 timeline pages in 13 seconds.
Benchmark the engagement of competitors
Pull the last 100 original posts of each brand, without reposts or the pinned post, then sort by viewCount or by likes per view in the Engagement view of the dataset.
Collect the videos and images an account posted
Run the account, then open the Media and links view: each row lists its images and its best-quality video file. On the default run, 18 of the 40 posts had images (23 images in all) and 8 had a video.
Feed new posts to a spreadsheet or a model
Call the actor from Python, keep the posts with more than 100,000 views and send them to your sheet, your database or your AI pipeline.
FAQ
What does this X timeline scraper return? One row per post of each account's timeline, newest first: the post itself (text, language, hashtags, mentions, links), its engagement (likes, reposts, replies, quotes, bookmarks, views), its context (reply, repost, quote, pinned), its images and videos, and the account's name, followers, following, post count, location and badges.
Do I need an X account, a developer account or an API key? No. The actor reads what X shows any visitor of a profile. You do not connect an account and you do not create anything on X's developer portal.
How many posts can I get per account?
Up to 3,200 per account, the most X keeps on a timeline, set with maxItems. A few very large accounts show visitors a selection rather than their full timeline: on our test run, elonmusk returned 100 posts, chosen by X and spread from 2018 to 2026. The run tells you in the log when it reaches the end of what X shows.
Does it return replies to other people?
It returns the timeline as the profile shows it: the account's posts, its reposts, its quotes and the threads it writes as replies to itself, each flagged with isReply and the post it answers. Replies the account sends to other people's posts are not on that timeline.
Can I scrape several accounts in one run?
Yes, as many as you like. List handles in usernames, links in startUrls, or both. maxItems applies to each account, and the same account typed twice is read once.
Can I combine the filters?
Yes, they stack. onlyPostsNewerThan: "30 days" with excludeRetweets: true and excludePinned: true returns only what the account wrote itself in the last 30 days, without the old pinned post. Add onlyPostsOlderThan to close the period.
How fresh is the data? Live. Every run reads X at the time of the run, so counts of likes and views are those of that moment. Schedule the actor to follow how a post's numbers grow.
What happens with a private, suspended or misspelled account? A protected account, a suspended account and a handle that does not exist return no row and a clear line in the log; the other accounts of the run are read normally. When no account returns a post, the run says why on its status line.
What is X? X is the social network formerly called Twitter. Posts are what used to be called tweets, reposts were retweets. Links on twitter.com and x.com both work in this actor.
Are the links in the output permanent?
The post url is permanent while the post is online. Image and video links point to X's media servers and stop working if the post is deleted: download the files you need to keep.
More SilentFlow scrapers
🛒 E-commerce
 JD - JD Products Scraper | JD.com Prices, Brands and Barcodes
 Pinterest - Pinterest Scraper | Pins, Boards and Profiles
 Leboncoin - Leboncoin Scraper | Classified Ads, Prices and Sellers
 TikTok Shop - TikTok Shop Scraper | Products, Sellers and Creator Videos
 Leboncoin - Leboncoin Ad Details Scraper
 Back Market - Back Market Scraper | Refurbished Prices
 ImportYeti - US Customs Records, Suppliers & Trade Data - ImportYeti Scraper - US Customs Records, Suppliers & Trade Data
 Naver - Naver Scraper | Shopping Products, Prices and Reviews
 Udemy Course - Udemy Course Scraper
 Naver - Naver Products Scraper | Shopping Prices, Sellers and Ratings
 1688 - 1688 Scraper | Products, Details, Wholesale Prices, Suppliers
 Amazon Seller - Amazon Seller Scraper | Emails, Phones and Ratings
 Naver - Naver Reviews Scraper | Shopping Product Reviews
 Store Leads Ecommerce - Store Leads Ecommerce Scraper
 Store Leads - Store Leads Scraper | Shopify Data
 Allegro - Allegro Scraper | Products, Prices and Sellers
 Leboncoin - Leboncoin Scraper
 Lowes - Lowes Products Scraper | Prices, Stock and Specs
 Mobile.de - Mobile.de Scraper
 Taobao - Taobao Scraper | Products, Details, Prices and Sellers
 Agoda - Agoda Scraper | Hotel Prices and Guest Ratings
 Alibaba - Alibaba Products Scraper | Wholesale Prices and MOQ
 Avito - Avito Scraper | Listings, Prices and Sellers
 Bring a Trailer - Bring a Trailer Scraper
 Coupang - Coupang Detail Scraper | Product Prices and Options
 Eventim - Eventim Scraper | Events, Ticket Prices and Venues
 Homedepot - Homedepot Reviews Scraper | Customer Reviews and Ratings
 Pinterest - Pinterest Scraper
 Udemy - Udemy Scraper
 Alibaba - Alibaba Scraper | Products, Supplier Companies and Prices
 AliExpress - AliExpress Reviews Scraper | Feedback, Ratings and Photos
 AliExpress - AliExpress Scraper | Products, Prices and Sales
 Avito - Avito Profiles Scraper | Sellers, Ratings and Reviews
 Back Market - Back Market Scraper | Refurbished Electronics Prices
 BAUHAUS - BAUHAUS Scraper | Product Prices, EAN and Specs
 CARFAX - CARFAX Scraper | Used Cars, Prices and History
 eBay Marketplace - eBay Marketplace Scraper
 Google Hotels - Google Hotels Scraper | Prices, Offers and Ratings
 Leboncoin - Leboncoin Details Scraper | Full Ad Data and Sellers
 Mafengwo - Mafengwo Scraper | Attractions, Ratings and Tickets
 Mercari - Mercari Scraper | Listings, Sold Prices and Sellers
 Trip - Trip Scraper | Hotels, Prices and Reviews
 Vinted Marketplace - Vinted Marketplace Scraper
 Webmotors - Webmotors Scraper | Car Listings, Prices and FIPE
 Woolworths - Woolworths Products Scraper | Prices, Specials and Nutrition
 Amazon - Amazon Product Scraper
 Amazon Marketplace - Amazon Marketplace Scraper
 AutoScout24 - AutoScout24 Scraper
 eBay Listings - eBay Listings Scraper
 Europages Deep Dive Extractor - Europages Deep Dive Extractor | VAT, Decision Makers, ISO Certs
 Europages - Europages Scraper | Suppliers and B2B Companies
 GasBuddy - GasBuddy Scraper | Gas Prices by Station
 Goofish - Goofish Detail Scraper | Listings, Prices and Sellers
 Vinted - Vinted Scraper
 Walmart - Walmart Scraper | Prices, Reviews, Sellers, Availability
 Walmart - Walmart Product Scraper
💼 Jobs
 ZipRecruiter - ZipRecruiter Jobs Scraper | Salary, Company & Location Filters
 Indeed - Indeed Company Reviews Scraper
 Multi Board - Multi Board Job Scraper
 Jobright - Jobright Scraper | Jobs, Salaries and H1B Sponsors
 Jora - Jora Jobs Scraper
 LinkedIn Job Search - LinkedIn Job Search Scraper | Salaries & Seniority
 Malt - Malt Scraper | Freelance Profiles
 Glassdoor Job Listings - Glassdoor Job Listings Scraper
 🔥 Glassdoor - 🔥 Glassdoor Scraper
 Malt Freelancer - Malt Freelancer Scraper
 ATS - ATS Jobs Scraper | Greenhouse, Lever and Ashby
 Glassdoor - Glassdoor Jobs Scraper
 Arbeitsagentur - Arbeitsagentur Jobs Scraper
 Cutshort - Cutshort Jobs Scraper | Salaries, Skills and Companies
 Dice - Dice Jobs Scraper | US Tech Jobs, Salaries, Skills
 Dice Tech - Dice Tech Jobs Scraper
 iimjobs - iimjobs Jobs Scraper | MBA, Finance and Hirist Tech Jobs
 Indeed - Indeed Jobs Scraper | Job Listings in 73 Countries
 Instahyre - Instahyre Jobs Scraper | Companies, Recruiters and Ratings
 Jora - Jora Scraper | Jobs in Australia, New Zealand, Singapore
 StepStone - StepStone Scraper
 Welcome to the Jungle - Welcome to the Jungle Job Scraper
 YCombinator - YCombinator Jobs Scraper | Startup Jobs, Salaries and Founders
 All - All Jobs Scraper
 Arbeitsagentur - Arbeitsagentur Scraper | German and Austrian Job Board
 iimjobs - iimjobs Scraper | Jobs, Companies and Recruiters
 Indeed - Indeed Companies Scraper | Reviews, Salaries, Interviews
 Indeed - Indeed Jobs Scraper | NLP Skills
 LinkedIn - LinkedIn Jobs Scraper
 Naukri & NaukriGulf - Naukri & NaukriGulf Jobs Scraper
 Seek - Seek Job Scraper
 Welcome to the Jungle - Welcome to the Jungle Scraper | Jobs and Company Data
 Ziprecruiter - Ziprecruiter Scraper
🏠 Real estate
 SeLoger - SeLoger Scraper | Real Estate Listings
 Realtor Rental Listings - Realtor Rental Listings Scraper
 Airbnb Professional Host - Airbnb Professional Host Scraper | Emails, Phones, SIRET
 Airbnb Pro Host Contact & - Airbnb Pro Host Contact & Email Scraper
 Trulia Rental Listings - Trulia Rental Listings Scraper
 Bien'ici - Bien'ici Scraper | Property Listings
 Rightmove - Rightmove Scraper
 SeLoger - SeLoger Scraper | French Property Listings and Agencies
 Airbnb Search - Airbnb Search Scraper
 Bienici - Bienici Scraper
 Idealista - Idealista Scraper
 Realestate.com.au - Realestate.com.au Scraper
 Airbnb Search - Airbnb Search Scraper | Prices, Fees, Amenities, Hosts
 Anjuke - Anjuke Scraper | Rental Listings, Prices and Agents
 Idealista - Idealista Scraper
 Realtor Rental - Realtor Rental Scraper
 Trulia Rental - Trulia Rental Scraper | US Rentals, Prices, Pet Policy
 Zillow - Zillow Scraper
📣 Social media
 LinkedIn Post Search - LinkedIn Post Search Scraper | Keywords, Hashtags & Profiles
 Facebook Search - Facebook Search Scraper
 Instagram - Instagram Story Scraper | Stories & Highlights
 LinkedIn Leads - LinkedIn Leads Scraper | Sales Navigator Export
 Facebook Search - Facebook Search Profiles Scraper | People by Name or Keyword
 YouTube - YouTube Channel Scraper | Videos, Shorts and Views
 TikTok - TikTok Scraper
 Instagram Engagement - Instagram Engagement Scraper
 TikTok Trend - TikTok Trend Scraper | Trending Hashtags and Videos
 Discord - Discord Scraper | Servers, Member Counts and Invites
 Douyin - Douyin Comments Scraper | Comments, Likes and IP Regions
 Likee - Likee Scraper | Videos, Hashtags and Creators
 Meta Ad Library - Meta Ad Library Scraper
 OnlyFans - OnlyFans Creator Scraper
 OnlyFans - OnlyFans Profile Scraper
 Reddit - Reddit Scraper | Posts, Comments and Subreddits
 Skool Community - Skool Community Scraper
 Bandsintown - Bandsintown Scraper | Concerts and Tour Dates
 Discord - Discord Profiles Scraper | Users, Badges and Server Tags
 Facebook Thread - Facebook Thread Profiles Scraper | Followers, Bios & Engagement
 Kuaishou - Kuaishou Scraper | Videos, Comments and Creator Stats
 LinkedIn Ads Library - No Cookies - LinkedIn Ads Library Scraper - No Cookies
 LinkedIn Event - LinkedIn Event Scraper
 LinkedIn Hashtag & - LinkedIn Hashtag & Post Scraper | No Cookies
 Pinterest - Pinterest Ads Scraper | Ad Library, Reach & Targeting
 Pinterest - Pinterest Profiles Scraper | Followers, Emails and Bios
 Pinterest - Pinterest Videos Scraper | Video Downloader, MP4 Links, Stats
 Reddit - Reddit Comments Scraper | Search, Threads and Replies
 Reddit - Reddit Profiles Scraper | User Karma, Activity and Communities
 Reddit - Reddit Scraper | Comments, Posts and Users
 RedNote - RedNote Videos Scraper | Downloader, Transcripts and Stats
 Snapchat - Snapchat Contacts Scraper | Phones, Emails and Websites
 Snapchat - Snapchat Videos Scraper | Spotlight Videos, MP4 and Stats
 TikTok Creative - TikTok Creative Ads Scraper | Top Ads, Landing Pages & Metrics
 TikTok Lookalike - TikTok Lookalike Scraper | Influencers, Emails and Engagement
 Xigua - Xigua Scraper | Videos, Creators and Downloads
 YouTube Autocomplete - YouTube Autocomplete Scraper | Keyword Suggestions
 Facebook - Facebook Company Scraper | Emails, Phones, Ratings
 Facebook Business Page - Facebook Business Page Scraper
 Kwai - Kwai Scraper | Videos, Creators and Hashtags
 RedNote - RedNote Detail Scraper | Xiaohongshu Details, Images, Videos
 Skool Group - Skool Group Scraper
 Snapchat - Snapchat Ads Scraper | Ad Library, Impressions & Targeting
 TwitchTracker - TwitchTracker Scraper | Twitch Streamer Stats and Rankings
 Weibo - Weibo Scraper | Posts, Profiles and Engagement
 YouTube - YouTube Transcript Scraper
🏢 Business data
 Tencent - Tencent Scraper | Maps Places, Phones and Ratings
 LinkedIn Company Search - LinkedIn Company Search Scraper | Profiles & Firmographics
 LinkedIn People Search - LinkedIn People Search Scraper | Profiles & Companies
 LinkedIn Sales Navigator - LinkedIn Sales Navigator Scraper
 Bilibili - Bilibili Scraper | Videos, Profiles, Comments, Danmaku
 Ctrip - Ctrip Scraper | Attractions, Tickets and Reviews
 SoftwareAdvice - SoftwareAdvice Scraper | Reviews, Ratings and Pros & Cons
 Teachable Course - Teachable Course Scraper
 Website Tech Stack - Website Tech Stack Scraper
 Zomato - Zomato Reviews Scraper | Restaurant Ratings and Replies
 2GIS - 2GIS Reviews Scraper | Ratings, Photos and Owner Replies
 Teachable - Courses, Prices & Instructors - Teachable Scraper - Courses, Prices & Instructors
 Trustpilot - Trustpilot Scraper | Reviews, Ratings and Company Contacts
✈️ Travel
 Google Maps - Google Maps Scraper
 Flight Price - Flight Price Scraper
 Booking.com Hotel - Booking.com Hotel Scraper
 Kakao - Kakao Scraper | Map Places, Reviews and Phones
 OpenTable - OpenTable Reviews Scraper | Restaurant Reviews and Ratings
 TheFork - TheFork Scraper | Restaurants, Menus and Ratings
 Trip - Trip Reviews Scraper | Hotel Reviews and Ratings
 Booking - Booking Scraper | Hotel Prices, Photos, Availability
🎯 Lead generation
 Northdata - Northdata Company Scraper
 Dealroom - Dealroom Scraper | Companies and Investors
 ZocDoc - ZocDoc Scraper | Doctors, Reviews and Availability
 UK Companies House - UK Companies House Enricher
 CNPJ Brazilian - CNPJ Brazilian Company Enricher
 Google Ads Transparency - Google Ads Transparency Scraper
 PagesJaunes - PagesJaunes Scraper | French Business Emails and SIRET
 BuiltWith - BuiltWith Scraper | Tech Stacks and Top Sites
 Company Data - Company Data Scraper | Emails, Phones and Tech Stack
 Dealroom Startup Data - Dealroom Startup Data Scraper
 Domain - Domain Enricher
 French Company Prospector - French Company Prospector
 G2 - G2 Reviews Scraper
 Justdial - Justdial Companies Scraper | Business Leads, Phones and Emails
 KVK - KVK Scraper | Dutch Companies and SBI Codes
 PagesJaunes - PagesJaunes Business Scraper
 SEC - SEC Scraper | EDGAR Filings and Company Data
 SIRET - SIRET Company Enricher
 SpyFu - SpyFu Scraper | SEO, PPC and Competitor Data
 Sunbiz - Sunbiz Companies Scraper | New Florida Business Leads
 Sunbiz - Sunbiz Scraper | Florida Companies and Officers
 USPTO - USPTO Scraper | Trademark Search and Status
 Clutch - Clutch Scraper | Agencies, Reviews, Ratings, Services
 Clutch Agency - Clutch Agency Scraper
 SIRET French - SIRET French Company Enricher
 ThomasNet Suppliers - ThomasNet Suppliers Scraper
 ZocDoc - ZocDoc Scraper
🔎 SEO
 Similarweb - Similarweb Scraper | Website Traffic, Rankings and Competitors
 Apple - Apple Reviews Scraper | App Store Reviews and Ratings
 Apple - Apple Scraper | App Store Apps, Ratings and Charts
 Bing - Bing Enricher Scraper | Mobile Friendly Test and Indexing
 Google News - Google News Scraper
 Scribd - Scribd Scraper | Documents, Authors and Views
📈 Marketing
 Douyin -
🎬 Video
 Pexels -
📰 News
 ForexFactory - ForexFactory Scraper | Economic Calendar and Forecasts
🧰 More tools
 FanDuel - FanDuel Scraper | Odds, Spreads and Player Props
 PrizePicks - PrizePicks Scraper | Player Props, Lines and Projections
Support
Need something this scraper doesn't do yet? We ship features fast.
- Feature requests go straight to our backlog
- Enterprise needs? We do custom integrations and high-volume plans
- Pricing questions? Check the Monetization tab on the actor page
Response time: usually under 24 hours.
Legal compliance
This Actor extracts publicly available data from X (x.com). It does not bypass any login, paywall or CAPTCHA, and it reads only the posts X shows to any visitor: protected accounts are never read. Users are responsible for complying with X's terms of service and applicable data protection laws (GDPR, CCPA, and PIPL where relevant). The output contains personal data (account names, handles, avatars, locations and the content people post), which users must handle accordingly: collect only what they need, keep it secure and honour deletion requests. The data returned is informational; verify accuracy for regulated use cases.
X Timeline Scraper by SilentFlow: the posts of any X account, as clean rows, on demand or on a schedule.


