
Yandexsearch Scraper | Search Results and Rankings
Pricing
from $2.51 / 1,000 rankings
Yandexsearch Scraper | Search Results and Rankings
Yandex Search scraper (Яндекс Поиск): organic Yandex SERP results by keyword or search URL, with rank, title, URL, snippet, domain, displayed URL and country, by city, language and date. 50 results in 8 seconds, 19 fields each. A Парсер выдачи Яндекса for SEO rank tracking in 2026. No account.
Pricing
from $2.51 / 1,000 rankings
Rating
0.0
(0)
Developer
SilentFlow
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
3 days ago
Last modified
Share
Yandexsearch Scraper (Яндекс Поиск) | Search Results and Rankings (2026)
From SilentFlow. Creators of Facebook Search Scraper and JD Products Scraper (#1 for “jd scraper” in Apify Store search), with 750,000+ combined lifetime runs.
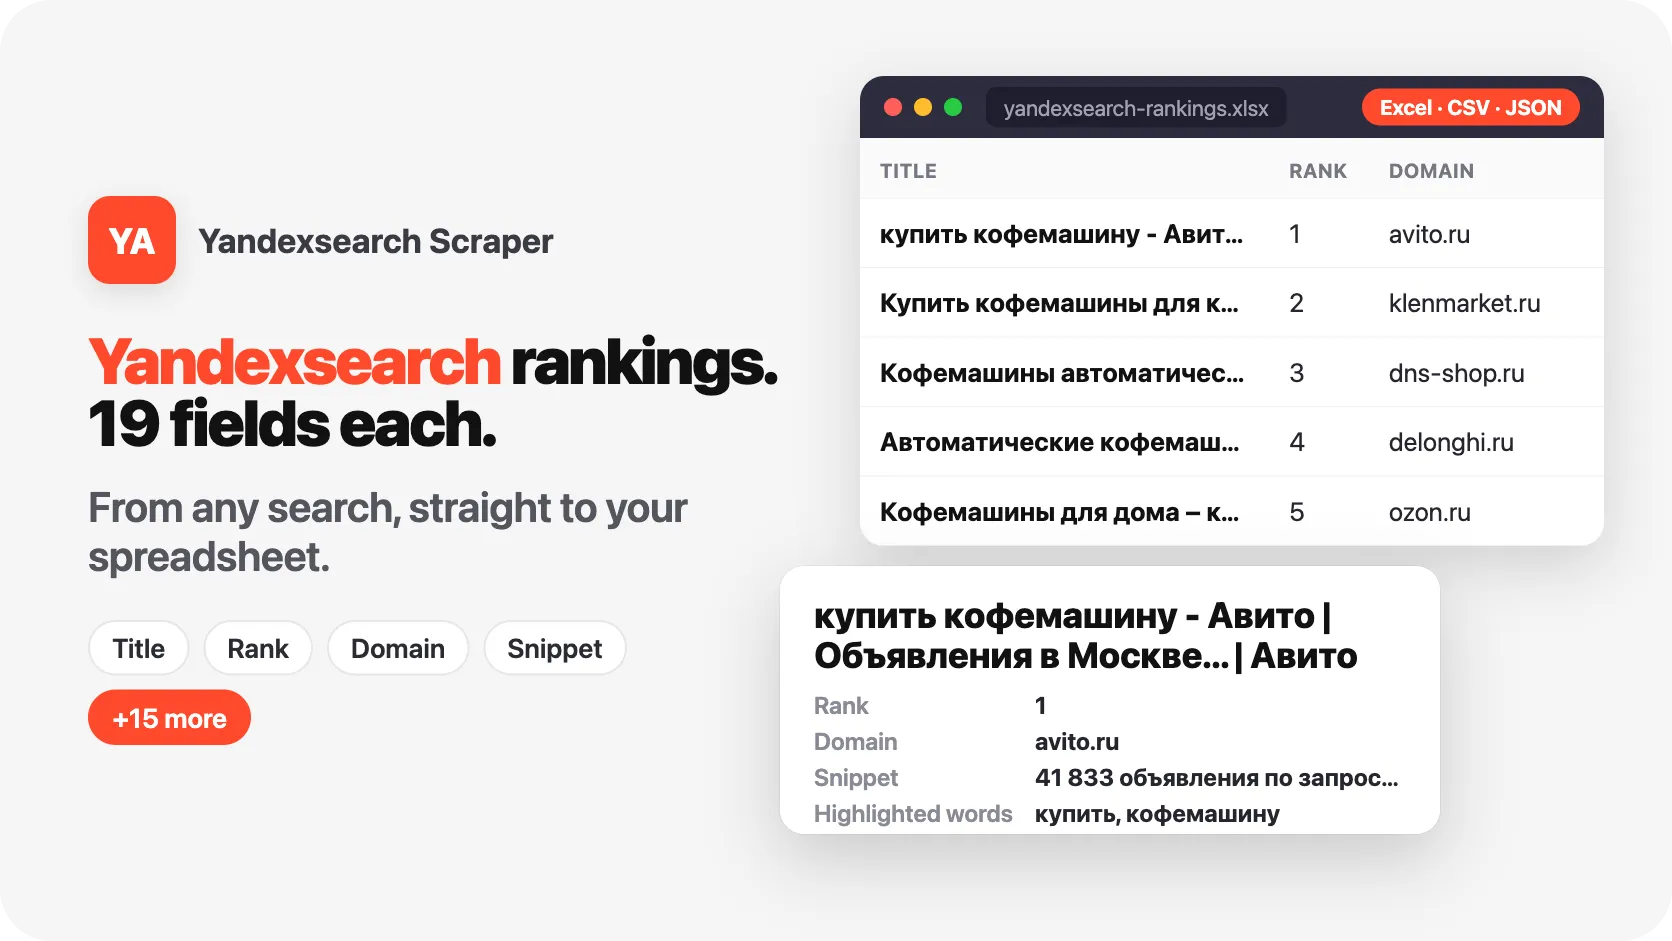
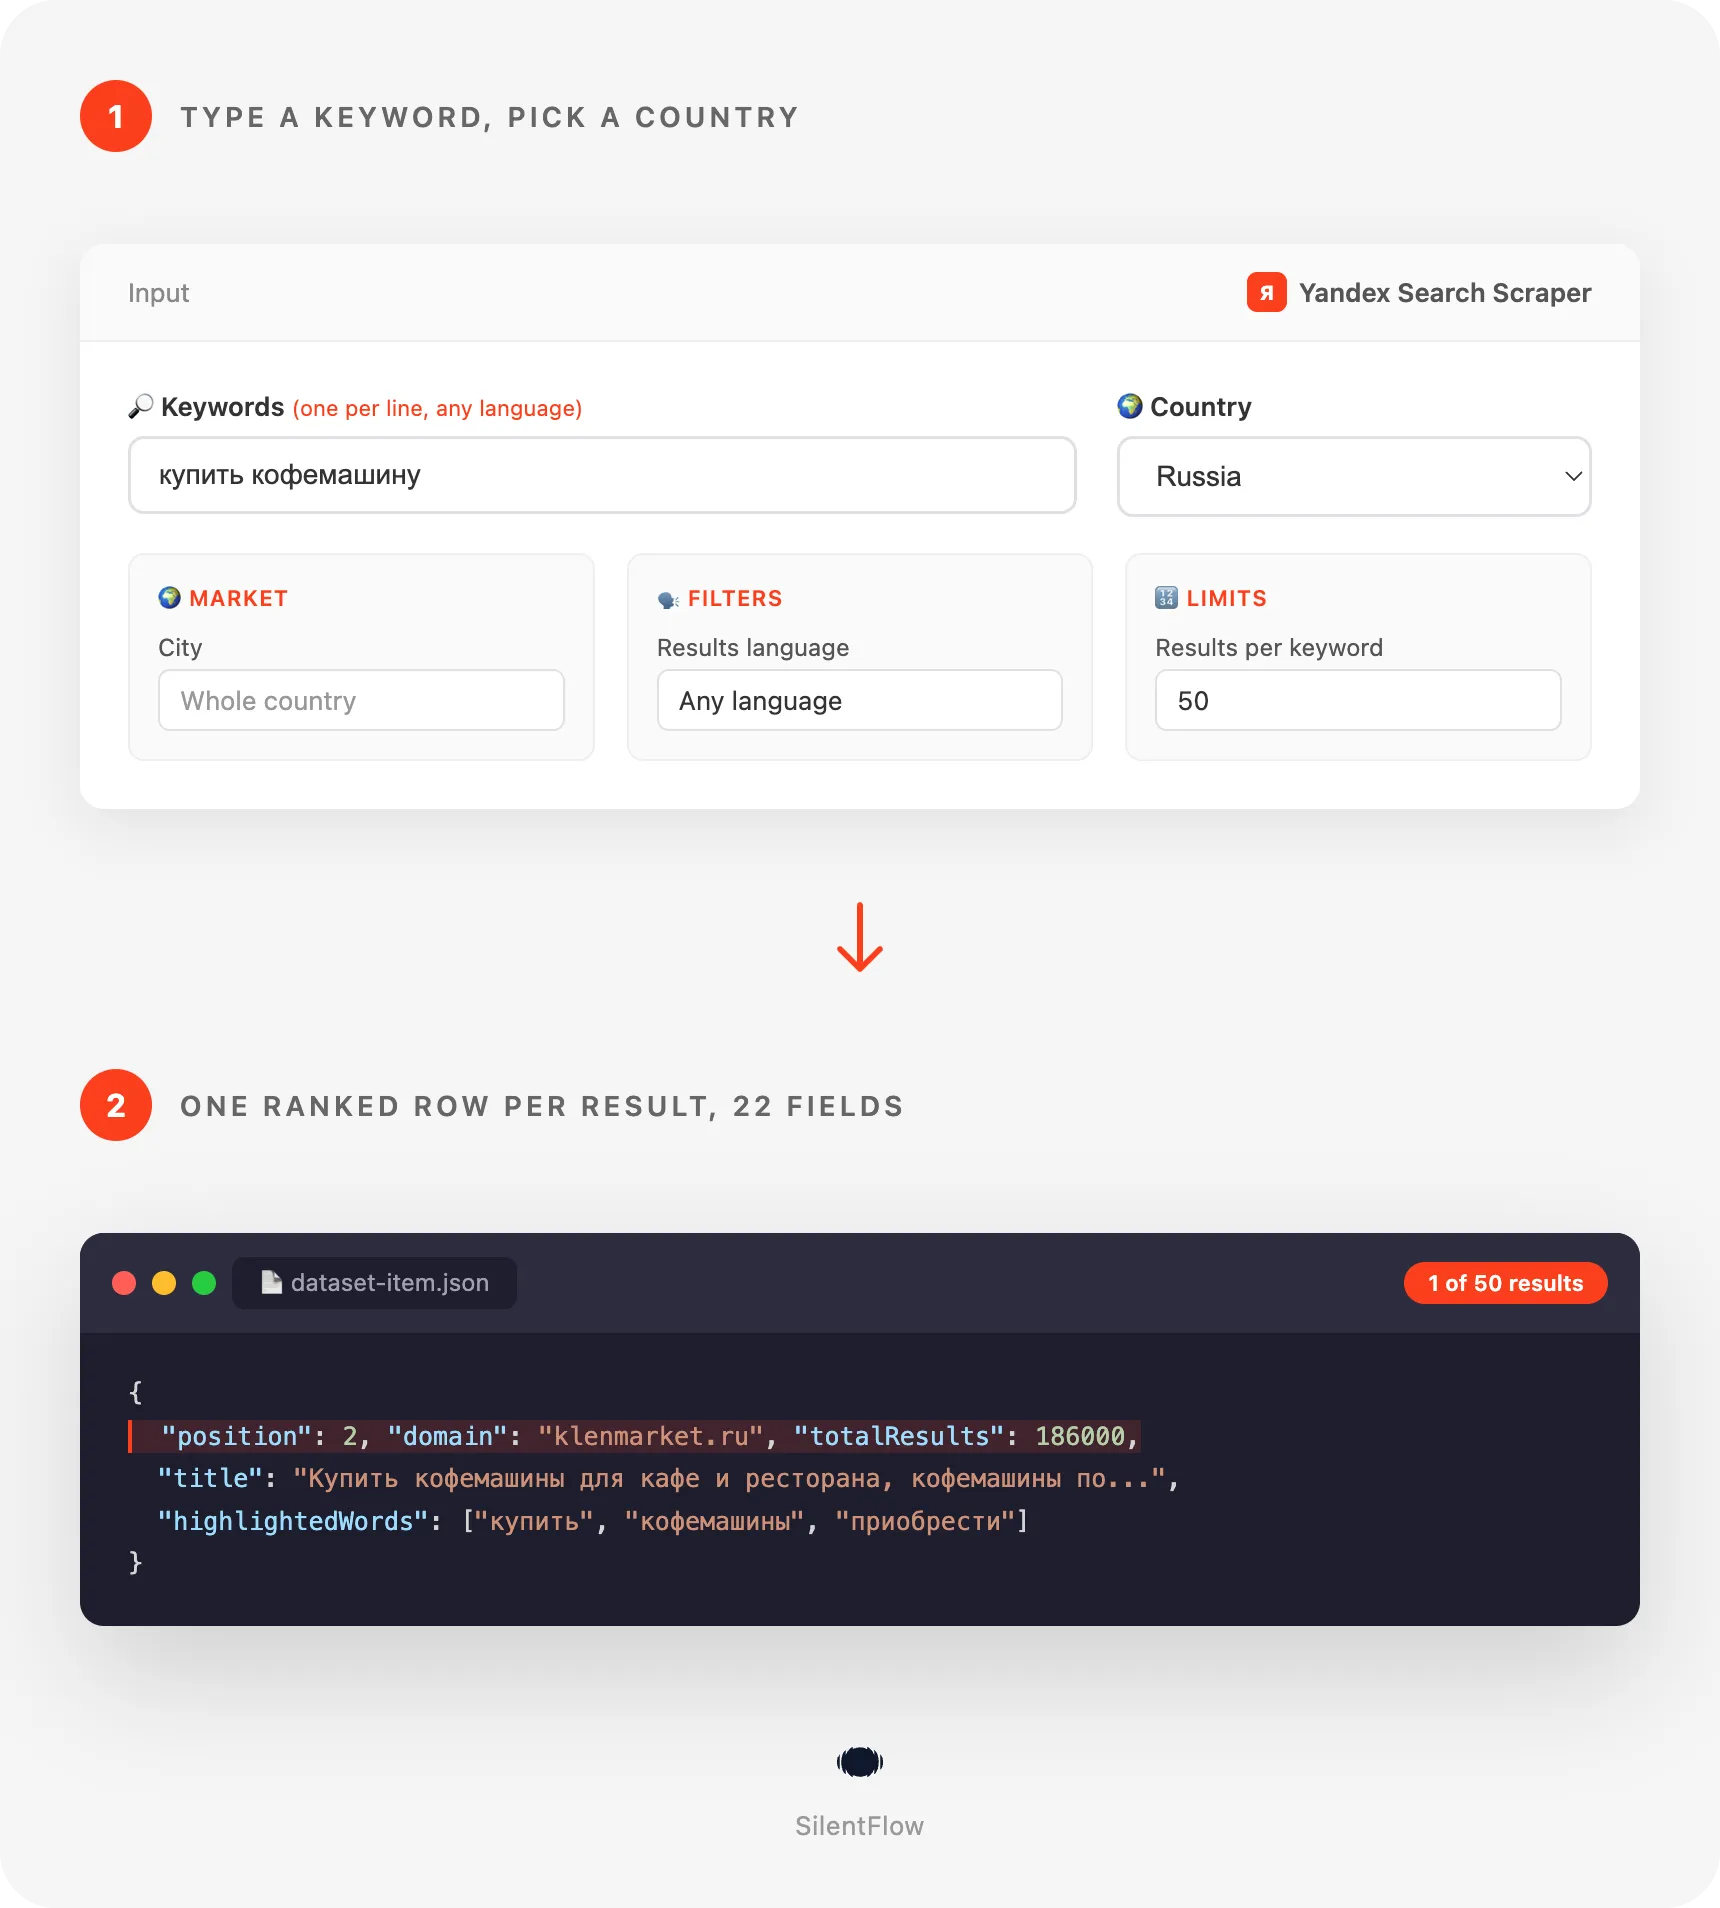
Every organic Yandex result for your keywords, one ranked row per page, by country and by city. Our default test run typed купить кофемашину (buy a coffee machine), searched Yandex for Russia and saved the top 50 organic results in 6 seconds: rank, title, URL, snippet, the address Yandex displays, the domain, the words Yandex highlighted and its count of matches (186,000). No Yandex account, no API key. A Yandex SERP API and a Парсер выдачи Яндекса in one form.
Why choose this actor?
Checking your Yandex positions by hand, city by city? Copying the top 10 into a spreadsheet every Monday? Unpacking nested page objects before you can sort results by domain?
- Type a keyword, or paste the Yandex search you already have open. Two ways in: keywords in any language, or search URLs from yandex.ru, yandex.com, yandex.com.tr, yandex.kz, yandex.by or ya.ru, whose keyword, city, results language and date filter are kept. In our test a pasted Saint Petersburg search for
ремонт квартирand a typed keyword ran side by side and returned 19 dated rows in 4 seconds. The most used Yandex scraper on the Store takes a typed query only. - One flat row per result, 22 fields, 18 of them filled on every row. On our default run (50 results in Russia), every row carried its rank, page, title, URL, snippet, displayed address, domain, highlighted words, favicon, Yandex's match count, the country, region and Yandex site it was ranked for, and the keyword and page it came from; 66% also had Yandex's link to more results from the same site. No arrays of results to unpack: sort by
domain, filter byposition, done. - Nothing to fill in before the first run. No field is required. The form opens with a keyword and Russia already set: press Start and the first 50 results arrive in about 6 seconds. Change the keyword, the country or the city when you are ready.
Try your first 50 rankings
Paste this input in the JSON tab of the Input page and press Start. It reads the top 50 organic Yandex results for купить кофемашину in Russia.
It runs on the Apify Free plan. Each result becomes one row of your dataset: open the Output tab to see the ranking table (keyword, rank, title, domain, snippet, Yandex's match count, URL), or switch to the full view for all 22 fields. Export the rows as JSON, CSV, Excel or HTML, or read them from the API.
Copy to your AI assistant
Paste this block into Claude, ChatGPT or Cursor to give it the full picture of this scraper:
How to scrape Yandex search results
Three inputs, from the simplest to a full regional setup. Each one runs as is.
Get the top 50 Yandex results for a keyword
One keyword, the default market (Russia). The run returns 50 rows in Yandex's order, ranks 1 to 50.
Track your rankings in one city
Yandex ranks by region: the same keyword ranks differently in Moscow and in Saint Petersburg. Pick the city, give your keywords and take the top 100 of each. Filter the rows on domain to find your site's position.
Search Turkey in Turkish, ranked for Istanbul
The country sets the Yandex site (yandex.com.tr for Turkey), the city sets the ranking, the language keeps Turkish pages only. Our test run of this input returned 60 rows (30 per keyword) in 6 seconds.
Input parameters
| Field | Type | Default | What it does |
|---|---|---|---|
queries | list of texts | ["купить кофемашину"] in the form | Keywords to search, one per line, in any language. Yandex operators such as site: and quotes work. |
startUrls | list of URLs | none | Yandex search pages to read. Keyword, city, results language and date filter come from the URL. |
country | text | ru | The Yandex site and region to search from: a two-letter code, a three-letter code or an English name. |
region | text | none | A city from the list or typed in English or Russian, or any Yandex region code (lr). Ranks for that city instead of the whole country. |
language | choice | any | Keep only pages written in Russian, English, Turkish, Ukrainian, Kazakh, Belarusian, Uzbek, Azerbaijani, German, French, Indonesian or Tatar. |
timeRange | choice | any | Keep only pages Yandex dated within the past day, 3 days, week, 2 weeks, month, 3 months, 6 months or year. Adds publishedAt to every row. |
maxResultsPerQuery | number | 50 | Results per keyword or URL, at most 250 (Yandex shows 25 pages of 10). |
maxItems | number | 1000 | Rows saved in total across all keywords and URLs. The run stops there. |
debugMode | true or false | false | Writes detailed progress to the run log. |
Accepted formats.
- Keywords: any text Yandex accepts, Cyrillic, Latin or Turkish characters, with operators (
site:apify.com scraper,"точная фраза"). A Yandex search URL typed in the keyword list is read as a URL. - Yandex URLs:
https://yandex.ru/search/?text=...&lr=213,https://ya.ru/search/?text=...,https://yandex.com.tr/search/touch/?text=...,https://yandex.kz/search/site/?text=..., and the other Yandex country sites. A URL withouttext=is skipped with a message in the log. - Country:
ru,rus,Russia;tr,tur,Turkey;kz,kaz,Kazakhstan, and so on for the 21 countries of the list. Any other country runs on yandex.com with Yandex's worldwide ranking, and the log says so. - City: the 25 cities of the list (Moscow, Saint Petersburg, Novosibirsk, Yekaterinburg, Kazan, Nizhny Novgorod, Chelyabinsk, Samara, Rostov-on-Don, Ufa, Krasnodar, Omsk, Krasnoyarsk, Voronezh, Perm, Volgograd, Vladivostok, Irkutsk, Izhevsk, Minsk, Almaty, Astana, Istanbul, Tbilisi, Yerevan) in English or Russian (
Москва,Санкт-Петербург,spb), or any Yandex region code as a number.
What data can you extract from Yandex?
Each row is one organic result of one search. A page that ranks for two of your keywords appears once per keyword, each time with its own rank and its own id.
| Group | Fields |
|---|---|
| Identity | id, url, title |
| Content | snippet, displayedUrl, domain, highlightedWords, fileType |
| Rank | position, page, totalResults |
| Place and time | publishedAt, country, regionId, regionName, language, yandexDomain |
| Links | faviconUrl, moreFromSiteUrl |
| Search | searchQuery, searchUrl, scrapedAt |
What the fields tell you:
positionis the organic rank, counted from 1 across pages, after Yandex's own widgets are left out.pageis the Yandex results page (10 results each).highlightedWordsare the words Yandex bolded in the title and snippet. They show how Yandex reads the keyword: forкупить кофемашинуit also highlightedприобрестиandкофемашины, the synonyms and word forms it matched.totalResultsis Yandex's own estimate of matching pages (186,000 forкупить кофемашинуin Russia on our run). It moves from one run to the next, and it isnullwhen the Yandex site does not print it, which happens on yandex.com and yandex.com.tr.fileTypeis set when the result is a document (pdf,doc,xls...),nullfor a web page.publishedAtis the date Yandex shows for the page, in RFC 3339 UTC. With a time range set, every row has it; without one, Yandex dates only some results (14 of 215 on our Almaty test) and the others arenull.idstays the same for the same page found by the same keyword in the same market and filters, run after run: join two runs onidto follow a page's rank over time.urlis the page's own address and does not expire.searchUrlandmoreFromSiteUrlopen live Yandex searches: they show today's results when you open them later.
Output example
One row of our default run, as it lands in the dataset:
Advanced usage
Five recipes for what the examples above do not show. Each JSON runs as is.
Compare one keyword across several cities in one run
The form takes one city per run, a URL carries its own. Paste one Yandex URL per city with its lr code (here доставка цветов, flower delivery, in Moscow, Saint Petersburg and Yekaterinburg): each search is ranked for its city, and regionId on every row tells them apart in the same dataset.
Watch fresh pages about a brand every morning
A time range keeps only recently dated pages and adds publishedAt to every row. Save this input as a task and schedule it daily: each run lists what Yandex dated in the past 24 hours. In our test, the past week of биткоин returned 10 results, all dated within the 7 days. Recent periods return fewer results than Yandex's match count suggests.
Pull the full top 250 for a keyword
Yandex shows 25 pages of 10 results per search, and this input reads them all. Use it to map the whole competitive field of a keyword, then count rows per domain to see who owns the most places. Our test of this input returned 215 results in 26 seconds: Yandex repeats some pages across its 25 pages, and each page is kept once, at its best rank.
Keep only English pages for an English keyword in Russia
Yandex mixes Russian pages into English searches. The results language keeps the pages written in English, ranked for the market you set.
Check which pages of a site Yandex shows for a topic
Yandex operators work in keywords. site: limits a search to one website: Yandex returns the few pages of that site it ranks best for the topic, a quick check of what it surfaces first.
FAQ
What is Yandex? Yandex (Яндекс) is Russia's main search engine. It also runs country sites for Turkey (yandex.com.tr), Kazakhstan, Belarus, Uzbekistan, Azerbaijan and Georgia. Its results differ from Google's, which is why SEO teams working on these markets track both.
Do I need a Yandex account or an API key? No. The actor reads the results Yandex shows publicly. No account, no Yandex Cloud project, no API key.
What does one row contain?
One organic result of one search: its rank, page, title, URL, snippet, the address Yandex displays, the domain, the words Yandex highlighted, the favicon, Yandex's link to more results from that site, Yandex's count of matches, and the country, city, Yandex site, language and keyword it was found for. 22 fields; values Yandex does not give are null.
How many results can I get per keyword?
Up to 250, the 25 pages of 10 that Yandex shows for any search. Set maxResultsPerQuery to 10 for the first page, 100 for a top 100. When Yandex has fewer results, the run returns what it has and moves on.
Does it return ads, Yandex widgets or AI answers?
No. Rows are organic results only. Yandex's own entries (currency converter, answer widgets) are left out, and position counts organic results only, so position 1 is the first web page Yandex ranks.
Why can positions differ from what I see on yandex.ru?
Your browser's Yandex page is personalized: your history, your login, your exact location and your device change the order, and ads and Yandex services push organic results down. This actor returns Yandex's ranking for the region, language and period you set, without personalization. Each row's searchUrl opens the exact results page it was read from.
How do I rank results for a city?
Pick it in the City field (25 cities in Russia, Belarus, Kazakhstan, Turkey, Georgia and Armenia), type its name in English or Russian, or type any Yandex region code (lr), the number Yandex puts in its own search URLs (213 Moscow, 2 Saint Petersburg). Leave it empty to rank for the whole country.
Can I combine the filters?
Yes, they stack. country: tr + region: Istanbul + language: tr + timeRange: month returns Turkish pages dated in the past month, as yandex.com.tr ranks them for Istanbul. Every keyword of the run uses the same filters; a pasted URL keeps its own.
Can I scrape many keywords in one run?
Yes. Add as many keywords and URLs as you need: each one gets its own ranking, from position 1. Set maxItems to cap the total. A page that ranks for several of your keywords appears once per keyword, with a different id each time.
How fresh is the data?
Live. Every run reads Yandex at the moment it runs, nothing is cached. Schedule the actor daily or weekly to build a ranking history, and join runs on id.
Why is totalResults sometimes null? Yandex prints its count of matches on yandex.ru, yandex.kz, yandex.by and the other country sites, but yandex.com and yandex.com.tr often leave it out of the page. The rows are complete; only that estimate is missing.
Why does a time range return fewer results?
With a period set, Yandex lists only the pages it dated in that period, and fewer of them than its match count suggests: in our test, the past week of ремонт квартир in Saint Petersburg returned 9 results while Yandex counted 11,000 matches. Use timeRange to watch what is new, and leave it on any to measure rankings.
Are the links permanent?
url is the page's own address and stays valid as long as the site keeps the page. faviconUrl is a stable Yandex image link. searchUrl and moreFromSiteUrl are live Yandex searches: they show the current results whenever they are opened.
Is it legal to scrape Yandex search results? The actor reads public search result pages: titles, links and snippets that Yandex shows to anyone. It does not log in or read anything behind an account. You are responsible for how you use the data; see the Legal compliance section below.
More SilentFlow scrapers
🛒 E-commerce
 JD - JD Products Scraper | JD.com Prices, Brands and Barcodes
 Pinterest - Pinterest Scraper | Pins, Boards and Profiles
 Leboncoin - Leboncoin Scraper | Classified Ads, Prices and Sellers
 TikTok Shop - TikTok Shop Scraper | Products, Sellers and Creator Videos
 Leboncoin - Leboncoin Ad Details Scraper
 Back Market - Back Market Scraper | Refurbished Prices
 Naver - Naver Scraper | Shopping Products, Prices and Reviews
 ImportYeti - ImportYeti Scraper | Suppliers, Importers and Bills of Lading
 Amazon Seller - Amazon Seller Scraper | Emails, Phones and Ratings
 Naver - Naver Products Scraper | Shopping Prices, Sellers and Ratings
 Naver - Naver Reviews Scraper | Shopping Product Reviews
 Udemy Course - Udemy Course Scraper
 1688 - 1688 Scraper | Products, Details, Wholesale Prices, Suppliers
 Allegro - Allegro Scraper | Products, Prices and Sellers
 Store Leads Ecommerce - Store Leads Ecommerce Scraper
 Store Leads - Store Leads Scraper | Shopify Data
 Coupang - Coupang Detail Scraper | Product Prices and Options
 Taobao - Taobao Scraper | Products, Details, Prices and Sellers
 Avito - Avito Scraper | Listings, Prices and Sellers
 Bring a Trailer - Bring a Trailer Scraper
 Leboncoin - Leboncoin Scraper
 Lowes - Lowes Products Scraper | Prices, Stock and Specs
 Mobile.de - Mobile.de Scraper
 Pinterest - Pinterest Scraper
 Alibaba - Alibaba Products Scraper | Wholesale Prices and MOQ
 Eventim - Eventim Scraper | Events, Ticket Prices and Venues
 Leboncoin - Leboncoin Details Scraper | Full Ad Data and Sellers
 Udemy - Udemy Scraper
 Agoda - Agoda Scraper | Hotel Prices and Guest Ratings
 Alibaba - Alibaba Scraper | Products, Supplier Companies and Prices
 AliExpress - AliExpress Reviews Scraper | Feedback, Ratings and Photos
 AliExpress - AliExpress Scraper | Products, Prices and Sales
 Avito - Avito Profiles Scraper | Sellers, Ratings and Reviews
 Back Market - Back Market Scraper | Refurbished Electronics Prices
 BAUHAUS - BAUHAUS Scraper | Product Prices, EAN and Specs
 CARFAX - CARFAX Scraper | Used Cars, Prices and History
 eBay Marketplace - eBay Marketplace Scraper
 Europages - Europages Scraper | Suppliers and B2B Companies
 Google Hotels - Google Hotels Scraper | Prices, Offers and Ratings
 Homedepot - Homedepot Reviews Scraper | Customer Reviews and Ratings
 Judge - Judge Scraper | Reviews, Ratings and Store Profiles
 MakersRow - MakersRow Scraper | Manufacturers, Capabilities and Reviews
 Mercari - Mercari Scraper | Listings, Sold Prices and Sellers
 Ticombo - Ticombo Scraper | Ticket Prices and Listings
 Trip - Trip Scraper | Hotels, Prices and Reviews
 Vinted Marketplace - Vinted Marketplace Scraper
 Walmart - Walmart Scraper | Prices, Reviews, Sellers, Availability
 Webmotors - Webmotors Scraper | Car Listings, Prices and FIPE
 Woolworths - Woolworths Products Scraper | Prices, Specials and Nutrition
 Amazon - Amazon Product Scraper
 Amazon Marketplace - Amazon Marketplace Scraper
 AutoScout24 - AutoScout24 Scraper
 eBay Listings - eBay Listings Scraper
 Europages Deep Dive Extractor - Europages Deep Dive Extractor | VAT, Decision Makers, ISO Certs
 GasBuddy - GasBuddy Scraper | Gas Prices by Station
 Goofish - Goofish Detail Scraper | Listings, Prices and Sellers
 Mafengwo - Mafengwo Scraper | Attractions, Ratings and Tickets
 Vinted - Vinted Scraper
 Walmart - Walmart Product Scraper
💼 Jobs
 ZipRecruiter - ZipRecruiter Jobs Scraper | Salary, Company & Location Filters
 Indeed - Indeed Company Reviews Scraper
 Multi Board - Multi Board Job Scraper
 Jobright - Jobright Scraper | Jobs, Salaries and H1B Sponsors
 Malt Freelancer - Malt Freelancer Scraper
 Malt - Malt Scraper | Freelance Profiles
 Glassdoor - Glassdoor Jobs Scraper
 Glassdoor Job Listings - Glassdoor Job Listings Scraper
 🔥 Glassdoor - 🔥 Glassdoor Scraper
 Jora - Jora Jobs Scraper
 LinkedIn Job Search - LinkedIn Job Search Scraper | Salaries & Seniority
 ATS - ATS Jobs Scraper | Greenhouse, Lever and Ashby
 Cutshort - Cutshort Jobs Scraper | Salaries, Skills and Companies
 Arbeitsagentur - Arbeitsagentur Jobs Scraper
 Dice - Dice Jobs Scraper | US Tech Jobs, Salaries, Skills
 Dice Tech - Dice Tech Jobs Scraper
 iimjobs - iimjobs Jobs Scraper | MBA, Finance and Hirist Tech Jobs
 Instahyre - Instahyre Jobs Scraper | Companies, Recruiters and Ratings
 Jora - Jora Scraper | Jobs in Australia, New Zealand, Singapore
 StepStone - StepStone Scraper
 Welcome to the Jungle - Welcome to the Jungle Job Scraper
 YCombinator - YCombinator Jobs Scraper | Startup Jobs, Salaries and Founders
 All - All Jobs Scraper
 Arbeitsagentur - Arbeitsagentur Scraper | German and Austrian Job Board
 iimjobs - iimjobs Scraper | Jobs, Companies and Recruiters
 Indeed - Indeed Companies Scraper | Reviews, Salaries, Interviews
 Indeed - Indeed Jobs Scraper | NLP Skills
 Indeed - Indeed Jobs Scraper | Job Listings in 73 Countries
 LinkedIn - LinkedIn Jobs Scraper
 Naukri & NaukriGulf - Naukri & NaukriGulf Jobs Scraper
 Seek - Seek Job Scraper
 Welcome to the Jungle - Welcome to the Jungle Scraper | Jobs and Company Data
 Ziprecruiter - Ziprecruiter Scraper
🏠 Real estate
 SeLoger - SeLoger Scraper | Real Estate Listings
 Realtor Rental Listings - Realtor Rental Listings Scraper
 Airbnb Professional Host - Airbnb Professional Host Scraper | Emails, Phones, SIRET
 Airbnb Pro Host Contact & - Airbnb Pro Host Contact & Email Scraper
 Bien'ici - Bien'ici Scraper | Property Listings
 Rightmove - Rightmove Scraper
 SeLoger - SeLoger Scraper | French Property Listings and Agencies
 Trulia Rental Listings - Trulia Rental Listings Scraper
 Idealista - Idealista Scraper
 Airbnb Search - Airbnb Search Scraper
 Bienici - Bienici Scraper
 Realestate.com.au - Realestate.com.au Scraper
 Zapimoveis - Zapimoveis Scraper | Real Estate Listings and Prices
 Zillow - Zillow Scraper
 Airbnb Search - Airbnb Search Scraper | Prices, Fees, Amenities, Hosts
 Anjuke - Anjuke Scraper | Rental Listings, Prices and Agents
 Idealista - Idealista Scraper
 Realtor Rental - Realtor Rental Scraper
 Trulia Rental - Trulia Rental Scraper | US Rentals, Prices, Pet Policy
📣 Social media
 Facebook Search - Facebook Search Scraper
 LinkedIn Post Search - LinkedIn Post Search Scraper | Keywords, Hashtags & Profiles
 Instagram - Instagram Story Scraper | Stories & Highlights
 LinkedIn Leads - LinkedIn Leads Scraper | Sales Navigator Export
 Facebook Search - Facebook Search Profiles Scraper | People by Name or Keyword
 YouTube - YouTube Channel Scraper | Videos, Shorts and Views
 TikTok Trend - TikTok Trend Scraper | Trending Hashtags and Videos
 LinkedIn Sales Navigator - LinkedIn Sales Navigator Scraper
 Reddit - Reddit Scraper | Posts, Comments and Subreddits
 TikTok - TikTok Scraper
 Discord - Discord Scraper | Servers, Member Counts and Invites
 Likee - Likee Scraper | Videos, Hashtags and Creators
 LinkedIn Event - LinkedIn Event Scraper
 LinkedIn Hashtag & - LinkedIn Hashtag & Post Scraper | No Cookies
 Meta Ad Library - Meta Ad Library Scraper
 OnlyFans - OnlyFans Profile Scraper
 Pinterest - Pinterest Ads Scraper | Ad Library, Reach & Targeting
 Snapchat - Snapchat Videos Scraper | Spotlight Videos, MP4 and Stats
 Bandsintown - Bandsintown Scraper | Concerts and Tour Dates
 Discord - Discord Profiles Scraper | Users, Badges and Server Tags
 Facebook Thread - Facebook Thread Profiles Scraper | Followers, Bios & Engagement
 Instagram Engagement - Instagram Engagement Scraper
 Kuaishou - Kuaishou Scraper | Videos, Comments and Creator Stats
 Kwai - Kwai Scraper | Videos, Creators and Hashtags
 LinkedIn Ads Library - No Cookies - LinkedIn Ads Library Scraper - No Cookies
 Pinterest - Pinterest Profiles Scraper | Followers, Emails and Bios
 Pinterest - Pinterest Videos Scraper | Video Downloader, MP4 Links, Stats
 Reddit - Reddit Comments Scraper | Search, Threads and Replies
 Reddit - Reddit Profiles Scraper | User Karma, Activity and Communities
 RedNote - RedNote Videos Scraper | Downloader, Transcripts and Stats
 Snapchat - Snapchat Contacts Scraper | Phones, Emails and Websites
 TikTok Creative - TikTok Creative Ads Scraper | Top Ads, Landing Pages & Metrics
 TikTok Lookalike - TikTok Lookalike Scraper | Influencers, Emails and Engagement
 TwitchTracker - TwitchTracker Scraper | Twitch Streamer Stats and Rankings
 X Timeline - X Timeline Scraper | Tweets and Engagement Stats
 Xigua - Xigua Scraper | Videos, Creators and Downloads
 YouTube Autocomplete - YouTube Autocomplete Scraper | Keyword Suggestions
 Douyin - Douyin Comments Scraper | Comments, Likes and IP Regions
 Facebook - Facebook Company Scraper | Emails, Phones, Ratings
 Facebook Business Page - Facebook Business Page Scraper
 OnlyFans - OnlyFans Creator Scraper
 Reddit - Reddit Scraper | Comments, Posts and Users
 RedNote - RedNote Detail Scraper | Xiaohongshu Details, Images, Videos
 Skool Group - Skool Group Scraper
 Skool Community - Skool Community Scraper
 Snapchat - Snapchat Ads Scraper | Ad Library, Impressions & Targeting
 Weibo - Weibo Scraper | Posts, Profiles and Engagement
 YouTube - YouTube Transcript Scraper
🏢 Business data
 Tencent - Tencent Scraper | Maps Places, Phones and Ratings
 LinkedIn Company Search - LinkedIn Company Search Scraper | Profiles & Firmographics
 Ctrip - Ctrip Scraper | Attractions, Tickets and Reviews
 LinkedIn People Search - LinkedIn People Search Scraper | Profiles & Companies
 Bilibili - Bilibili Scraper | Videos, Profiles, Comments, Danmaku
 Teachable Course - Teachable Course Scraper
 Website Tech Stack - Website Tech Stack Scraper
 2GIS - 2GIS Reviews Scraper | Ratings, Photos and Owner Replies
 Teachable - Courses, Prices & Instructors - Teachable Scraper - Courses, Prices & Instructors
 Trustpilot - Trustpilot Scraper | Reviews, Ratings and Company Contacts
✈️ Travel
 Flight Price - Flight Price Scraper
 Booking.com Hotel - Booking.com Hotel Scraper
 Despegar - Despegar Reviews Scraper | Hotel Reviews and Ratings
 Google Maps - Google Maps Scraper
 Kakao - Kakao Scraper | Map Places, Reviews and Phones
 OpenTable - OpenTable Reviews Scraper | Restaurant Reviews and Ratings
 TheFork - TheFork Scraper | Restaurants, Menus and Ratings
 Zomato - Zomato Reviews Scraper | Restaurant Ratings and Replies
 Booking - Booking Scraper | Hotel Prices, Photos, Availability
 Trip - Trip Reviews Scraper | Hotel Reviews and Ratings
🎯 Lead generation
 Northdata - Northdata Company Scraper
 Dealroom - Dealroom Scraper | Companies and Investors
 ZocDoc - ZocDoc Scraper | Doctors, Reviews and Availability
 UK Companies House - UK Companies House Enricher
 CNPJ Brazilian - CNPJ Brazilian Company Enricher
 Justdial - Justdial Companies Scraper | Business Leads, Phones and Emails
 PagesJaunes - PagesJaunes Scraper | French Business Emails and SIRET
 SIRET - SIRET Company Enricher
 BuiltWith - BuiltWith Scraper | Tech Stacks and Top Sites
 Company Data - Company Data Scraper | Emails, Phones and Tech Stack
 Dealroom Startup Data - Dealroom Startup Data Scraper
 French Company Prospector - French Company Prospector
 KVK - KVK Scraper | Dutch Companies and SBI Codes
 PagesJaunes - PagesJaunes Business Scraper
 SEC - SEC Scraper | EDGAR Filings and Company Data
 SoftwareAdvice - SoftwareAdvice Scraper | Reviews, Ratings and Pros & Cons
 Sunbiz - Sunbiz Companies Scraper | New Florida Business Leads
 Sunbiz - Sunbiz Scraper | Florida Companies and Officers
 USPTO - USPTO Scraper | Trademark Search and Status
 Clutch - Clutch Scraper | Agencies, Reviews, Ratings, Services
 Clutch Agency - Clutch Agency Scraper
 Domain - Domain Enricher
 G2 - G2 Reviews Scraper
 Google Ads Transparency - Google Ads Transparency Scraper
 SIRET French - SIRET French Company Enricher
 ThomasNet Suppliers - ThomasNet Suppliers Scraper
 ZocDoc - ZocDoc Scraper
🔎 SEO
 Similarweb - Similarweb Scraper | Website Traffic, Rankings and Competitors
 SpyFu - SpyFu Scraper | SEO, PPC and Competitor Data
 Apple - Apple Reviews Scraper | App Store Reviews and Ratings
 Apple - Apple Scraper | App Store Apps, Ratings and Charts
 Bing - Bing Enricher Scraper | Mobile Friendly Test and Indexing
 Google News - Google News Scraper
 Scribd - Scribd Scraper | Documents, Authors and Views
📈 Marketing
 Douyin -
🎬 Video
 Pexels -
📰 News
 ForexFactory - ForexFactory Scraper | Economic Calendar and Forecasts
🧰 More tools
 FanDuel - FanDuel Scraper | Odds, Spreads and Player Props
 PrizePicks - PrizePicks Scraper | Player Props, Lines and Projections
Support
Need something this scraper doesn't do yet? We ship features fast.
- Feature requests go straight to our backlog
- Enterprise needs? We do custom integrations and high-volume plans
- Pricing questions? Check the Monetization tab on the actor page
Response time: usually under 24 hours.
Legal compliance
This actor extracts publicly available data from Yandex search results: page titles, URLs, snippets and the ranking Yandex shows to any visitor. It does not bypass any login or paywall and reads nothing behind an account. Users are responsible for complying with Yandex's terms of service and with the data protection laws that apply to them (GDPR in the EU, CCPA in California, PIPL in China, and Russia's personal data law 152-FZ where relevant). Search results can contain personal data when a person's name or page ranks for a keyword: handle such rows accordingly. The data is informational; verify it before any regulated use.
Built by SilentFlow for SEO teams, analysts and agents who work on the Yandex markets.


