
Gupy Jobs Scraper | Brazil Jobs and Employers
Pricing
from $0.76 / 1,000 jobs
Gupy Jobs Scraper | Brazil Jobs and Employers
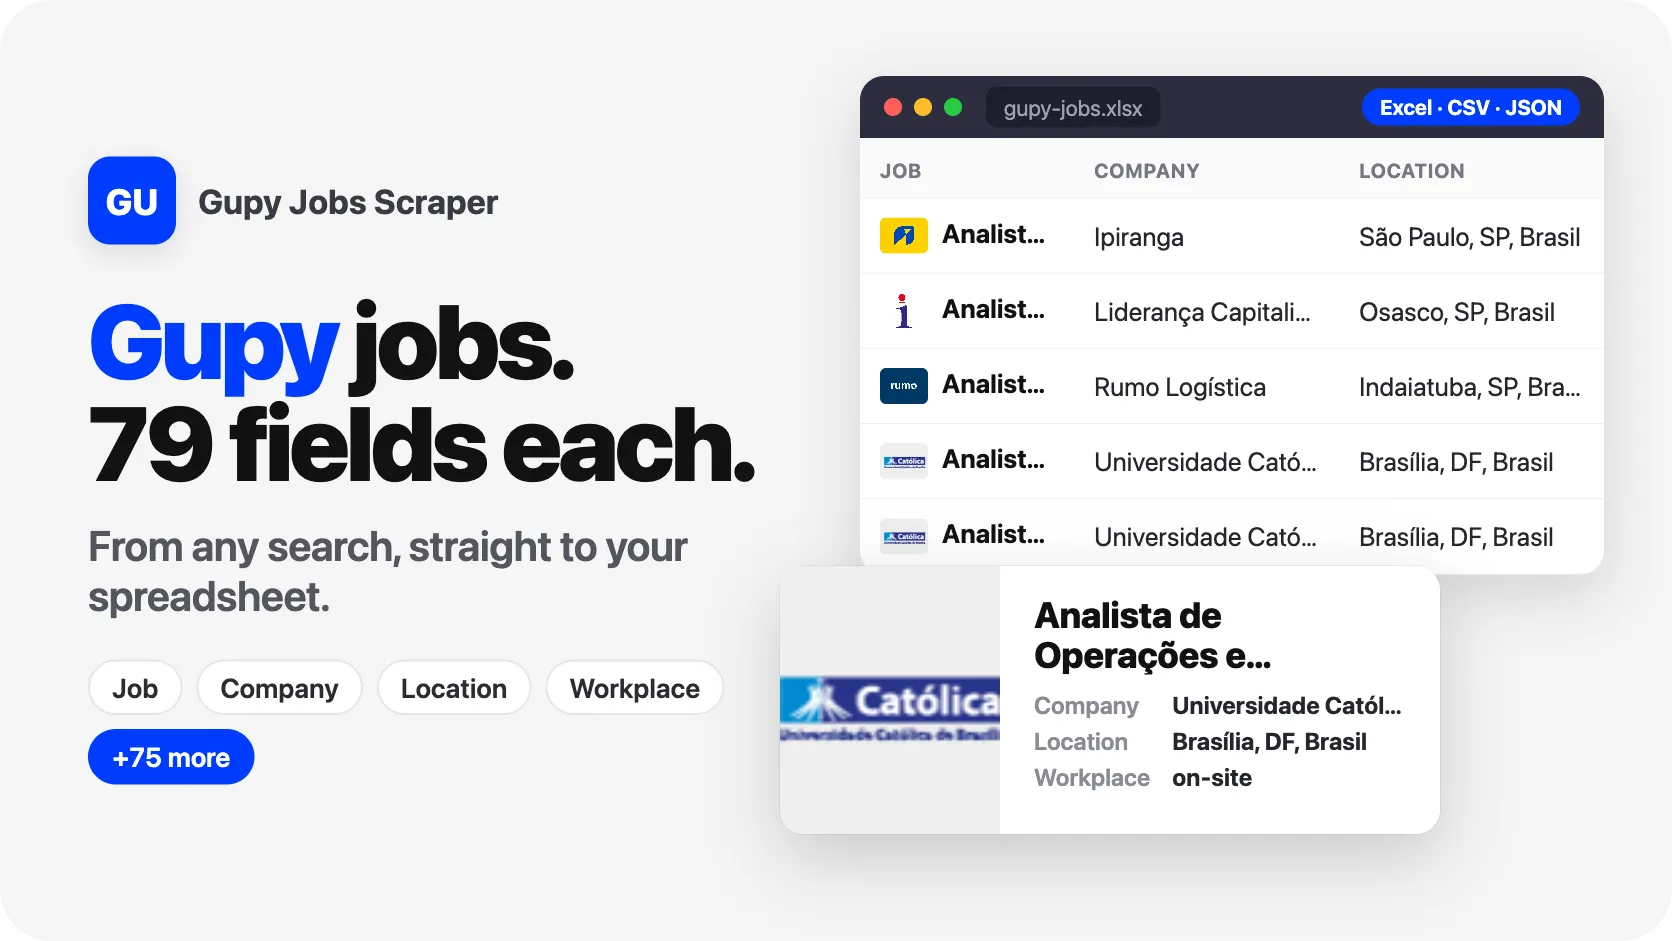
Gupy scraper for Vagas Gupy across Brazil: 50 jobs in 14 seconds, 79 fields each. Search by keyword, state, city, company or Gupy link and get the full description, requirements, benefits, hiring steps, contract type, address, application deadline and the employer's website and LinkedIn page.
Pricing
from $0.76 / 1,000 jobs
Rating
0.0
(0)
Developer
SilentFlow
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
2 days ago
Last modified
Categories
Share
Gupy Jobs Scraper (Vagas Gupy) | Brazil Jobs, Hiring Steps and Employers (2026)
From SilentFlow. Creators of Facebook Search Scraper and JD Products Scraper (#1 for “jd scraper” in Apify Store search), with 800,000+ combined lifetime runs.
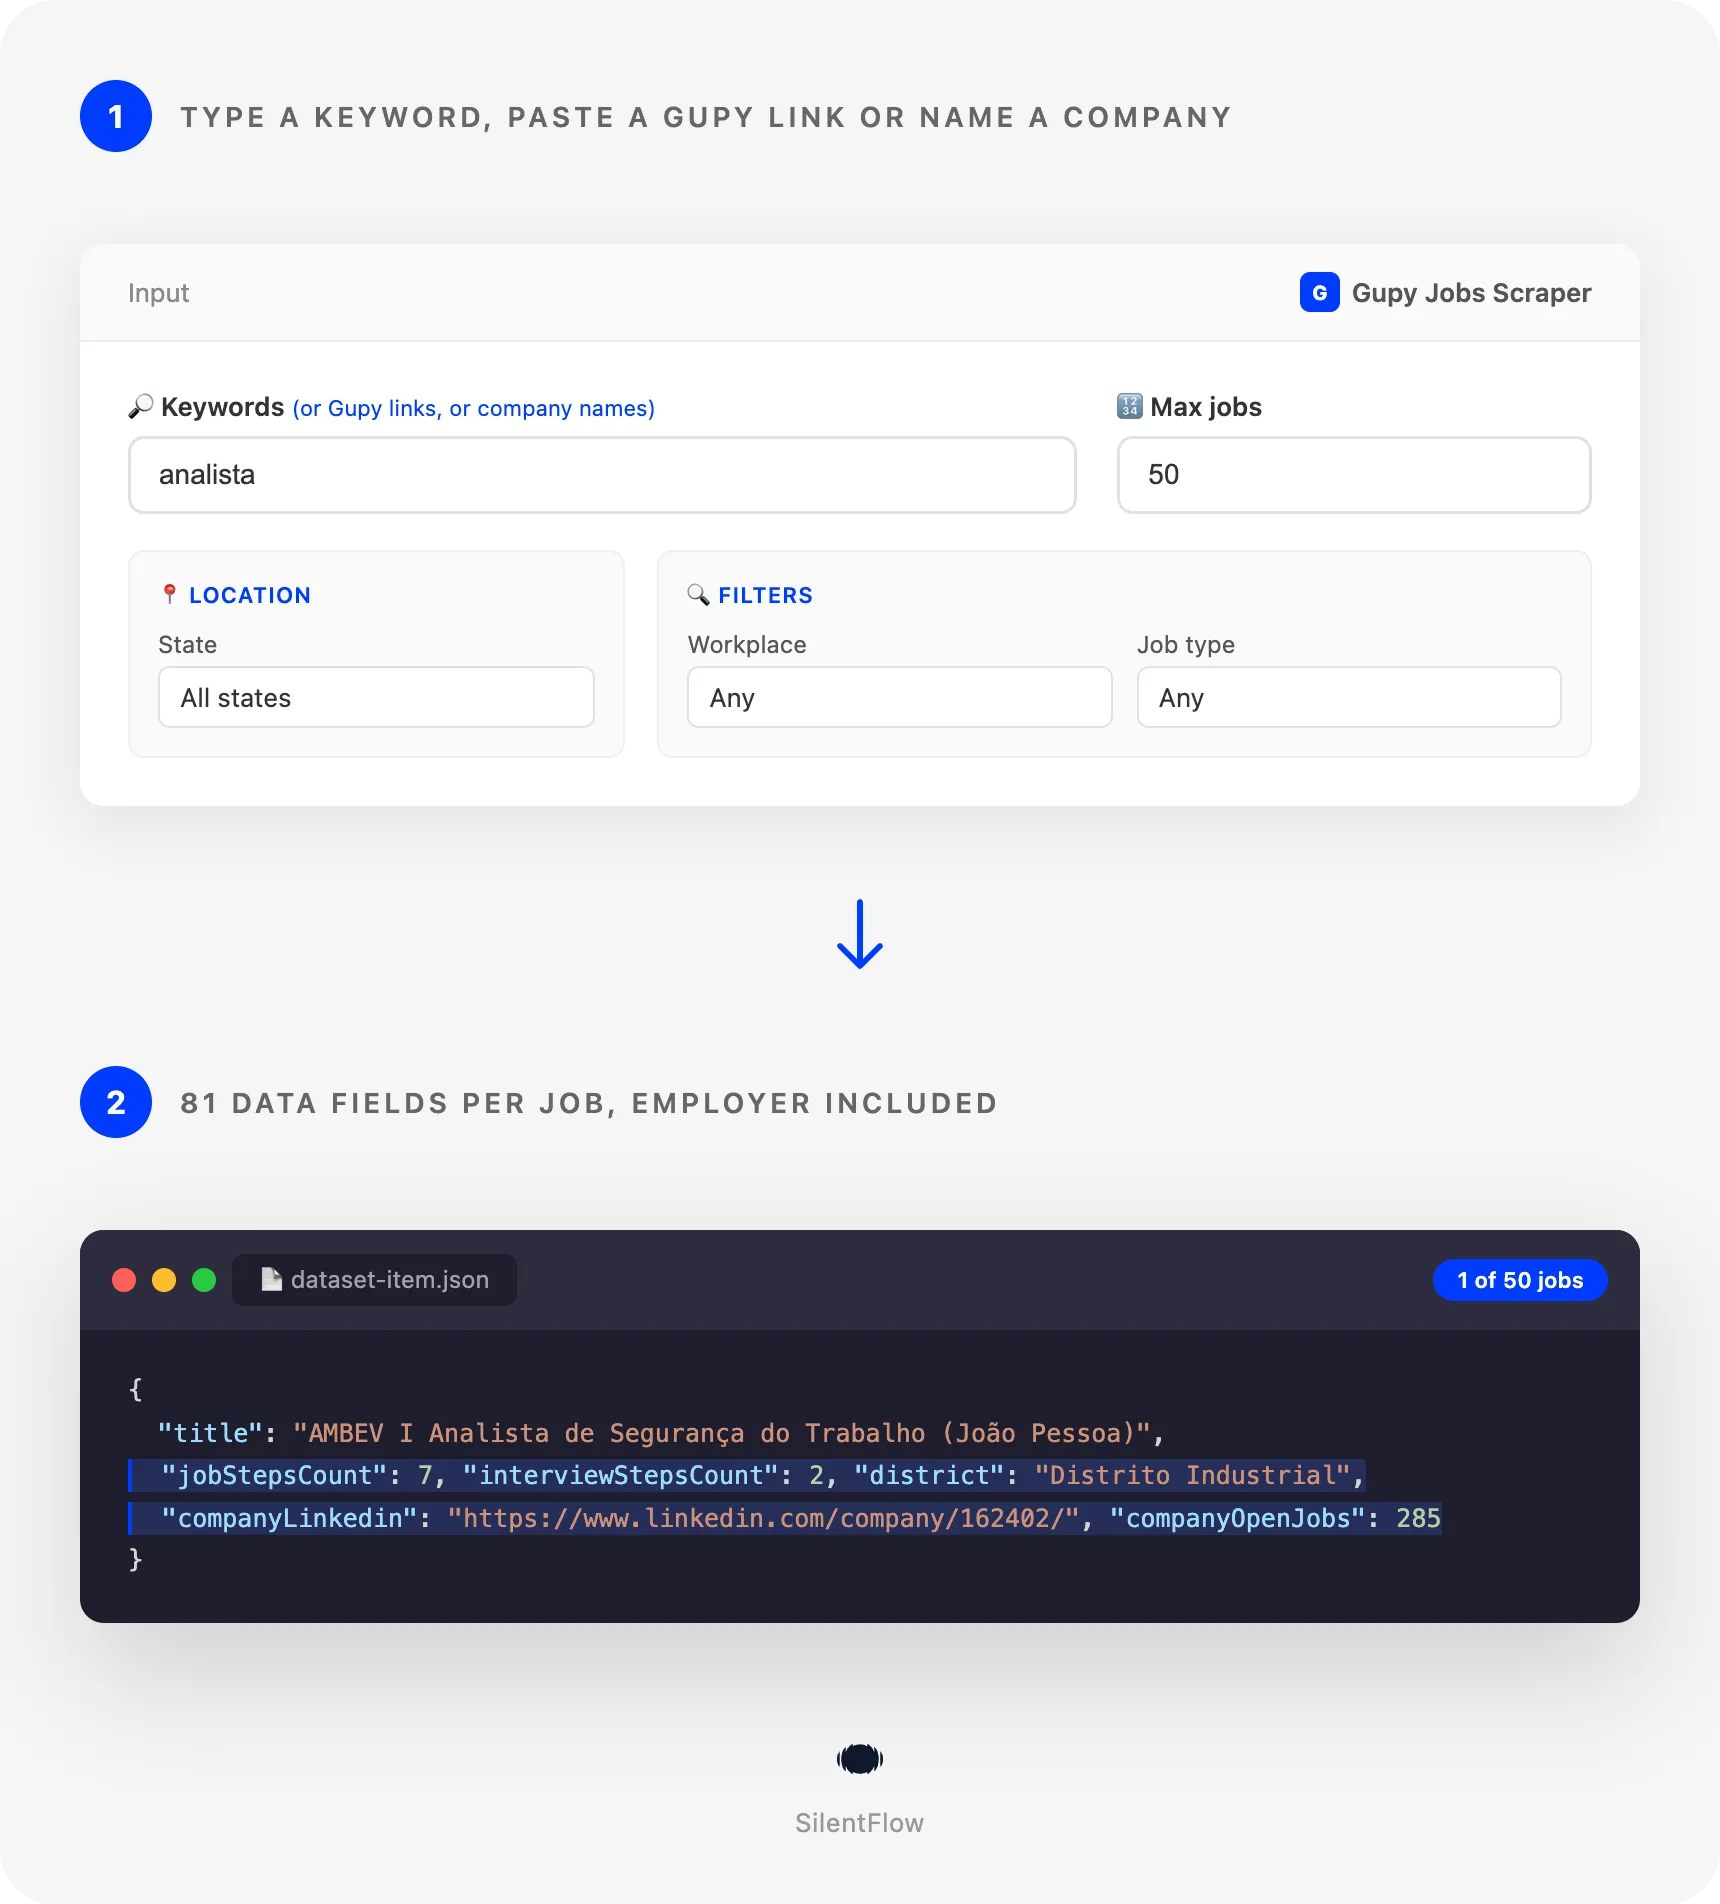
Every Gupy job (vaga) in Brazil as one clean row: the full description, the requirements, the benefits as a list, the contract and workplace type, every step of the hiring process, the address down to the district and CEP, and the employer behind it with its website, LinkedIn, Instagram and number of open jobs. Type a keyword, paste any Gupy link or name the companies you follow, and get a table you can filter, chart, load into a CRM or feed to a job board. The default input returned 50 analyst jobs from 35 employers in 14 seconds on 30 Oct 2026.
Why choose this actor?
Opening Gupy jobs one by one to read what they ask for and what they offer? Copying the company's name into a search engine to find its website and LinkedIn? Following ten employers' career pages by hand to see who is hiring this week?
- 76 fields per job, each one filled on at least half of the rows. On the default run (keyword
analista, 50 jobs, 30 Oct 2026), 76 data fields carried a value on at least half of the rows and 52 on every single row: the four text sections of the job in HTML and plain text, the benefits as a list (25 of 50 jobs), the contract type with its Portuguese label (Efetivo, Pessoa jurídica, Temporário), the workplace type, the department (50 of 50), the education level asked (45 of 50), the seniority, the hiring reason, every hiring step with the number of interviews, the street, district (40 of 50), CEP (49 of 50), city, state and region, and the publication date, deadline and days left to apply. - The employer on the same row, ready for outreach. 21 of those fields describe the company that posted the job: its name, Gupy id and career page, logo and banner, its own description, its website (35 of 50 jobs), LinkedIn page (37 of 50), Instagram (31 of 50), YouTube video, photos, brand color, timezone and the number of jobs it has open on Gupy (864 for Sicredi, 285 for Ambev on that run). No second tool, no extra step: the company comes with the job.
- Three ways in: keywords, Gupy links and company names. Type roles or skills (
analista,vendedor,desenvolvedor), paste any Gupy link (one job, a company's career page, or a portal search with its filters), or name the companies you track (ambev,renner,cogna) to get every job they have open. On 30 Oct 2026, one run mixing two companies, a job link and a remote portal search returned 60 jobs in 21 seconds, the job link first.
Try your first Gupy job search
Paste this input into the Input tab (JSON view) and press Start. It is the default input of the form: the newest analyst jobs (vagas de analista) on Gupy, up to 50.
The Apify Free plan is enough to run it and to try the actor on your own keywords, states and companies: no credit card, no Gupy account, no setup. Each job becomes one row of the dataset, which you can export as JSON, CSV or Excel, open in Google Sheets, or read from the Apify API. On 30 Oct 2026 this input returned 50 jobs published in the previous eight hours, from 35 employers in 12 states (26 in São Paulo, 7 in Ceará), with an average of 6.1 hiring steps each.
Copy to your AI assistant
Paste this block into Claude, ChatGPT or Cursor to give it the full context of this actor:
How to scrape Gupy jobs
Get the newest developer jobs in Brazil
One keyword, newest jobs first, every state at once. Each row carries the full job text, the hiring steps and the employer's website and LinkedIn.
Pull remote data jobs published this week
Three keywords, remote work only, published in the last seven days. Remote jobs carry no city or state on Gupy, so leave the location empty for them.
Find on-site internships in one city
Keywords, state, city, workplace and contract type combine: this returns on-site internships in Campinas only, each with its education level, address and CEP.
Input parameters
| Parameter | Type | What it does | Default |
|---|---|---|---|
searchQueries | array of strings | Roles or skills searched on the Gupy portal, each on its own | prefill ["analista"] |
startUrls | array of URLs | Gupy job links, career pages and portal search links | none |
companyIds | array of strings | Companies by their Gupy name (ambev) or career page address | none |
state | string | A Brazilian state, code or name | all states |
city | string | A city as Gupy writes it | all cities |
maxItems | integer | Cap on saved jobs across all inputs | 100 |
workplaceType | string | any, remote, hybrid or on-site | any |
jobType | string | any or one Gupy contract type | any |
postedWithinDays | integer | Only jobs published in the last N days | every open job |
debugMode | boolean | Detailed logs | false |
Formats accepted:
- Keywords: any text, as typed on portal.gupy.io (
analista financeiro,vendedor,motorista). Accents matter to Gupy's search the way they do on the site. - Job links:
https://ambev.gupy.io/jobs/12745756, the portal linkhttps://ambev.gupy.io/job/eyJqb2JJZCI6...?jobBoardSource=gupy_portal, and the apply linkhttps://ambev.gupy.io/candidates/jobs/12745756/apply. - Career pages:
https://renner.gupy.io/, with or without a path or query. - Portal searches:
https://portal.gupy.io/job-search/term=analista&state=Bahia&city[]=Salvador&workplaceTypes[]=hybrid&jobTypes[]=vacancy_type_internship. A link with several cities, workplace types or job types runs one search for each combination. - Companies:
ambev,Ambev,ambev.gupy.ioorhttps://ambev.gupy.io/. - States:
SP,sp,São Paulo,sao paulo,Estado de São Paulo. - Job numbers alone (
12745756) are not enough: Gupy needs the company too, so paste the job link instead.
What data can you extract from Gupy?
Each row has 84 keys: 81 data fields and 3 that say how the run found the job. On the default run, 76 data fields carried a value on at least half of the rows and 52 on every row.
| Group | Fields | What you get |
|---|---|---|
| Identity | 6 | id, url, title, code (the employer's own reference), jobUrl, applyUrl |
| Content | 10 | The description, responsibilities, requirements and additional information, each in HTML and plain text; benefits as a list; skills when listed |
| Attributes | 19 | Contract type (code, Portuguese label and normalized English type), workplace type and label, isRemote, seniority, education level, department, hiring reason, status, publication type, language, accessibility and badge flags, quick apply, Google for Jobs flag, internal mobility |
| Hiring process | 5 | Every step with its name, type, category and order, the step names, the number of steps and of interviews, and whether there is a test |
| Company | 22 | Name, career page title, Gupy id and name, career page id and link, logo, banner, description title and text, website, LinkedIn, Instagram, Facebook, Glassdoor, video, photos, open jobs count, timezone, brand color, page visibility |
| Place | 11 | Location line, full address, street, district, CEP, city, state, state code, IBGE region, country, country code |
| Time | 6 | Publication date, expiry date, application deadline, days since posted, days until the deadline, still open for applications |
| Media | 2 | The job image and video when the employer adds them |
| Run | 3 | searchQuery, sourceUrl, scrapedAt |
Good to know about the data:
idis Gupy's job number and never changes.urlis the job's permanent page while the job is open; once the employer closes it, the page redirects to the candidate sign-in.- Dates are RFC 3339 in UTC.
applicationDeadlineandexpiresAtare days, written at midnight UTC. - Remote jobs have no address on Gupy: their
city,state,address,district,zipCodeandregionare null, andlocationreadsBrasil. benefitsis the list under the job's "Benefícios" heading, whether written as bullets or emoji lines. Jobs that describe benefits only in prose have it null.seniorityis read from the title (Júnior, Pleno, Sênior, Estágio, Gerente...) andeducationLevelfrom the text: the lowest level the job asks for, so "Ensino médio completo, superior desejável" readshigh_school.companyNameis the name the career page is published under, unless that name is a recruiting slogan, in which case the page's own title is used.careerPageNamealways keeps the page's title as Gupy shows it.- Image and logo links point to Gupy's own file storage and stay valid as long as the employer keeps them.
Output example
One real row from the default run of 30 Oct 2026. Long texts are cut here for reading, and the lists show their first items; the dataset has them in full.
Advanced usage
Track every open job of the companies you follow
Every job each company has open on Gupy, with its department and district. Schedule it daily and compare runs on id to see which jobs opened and which closed.
Re-read a list of jobs you already track
Job links are read first, before companies and keywords, so a tracked list always comes back whole. Closed jobs are skipped and counted in the log, with no empty row.
Build a list of employers hiring for a role
Open the Employers view of the dataset: one line per job with the company, its website, LinkedIn page, open jobs count and career page. Sales and recruiting teams use it as a list of companies hiring right now.
Run a portal search exactly as you built it on Gupy
Build the search on portal.gupy.io, copy the address, paste it. A link with two cities runs one search per city and keeps each job once.
Feed a weekly report of the whole Brazilian job market
No keyword reads every job, newest first: here, one week of Minas Gerais. Without a state, a search that matches more than Gupy shows in one go continues state by state, then with remote jobs, so a large maxItems is not cut short. Export to CSV and pivot on region, jobTypeLabel, workplaceType or department.
FAQ
What is Gupy?
Gupy is the recruiting platform behind the career pages of thousands of Brazilian employers, from Ambev and Localiza to Lojas Renner and Cogna. Each company has its own site (ambev.gupy.io), and the portal portal.gupy.io lists all their open jobs in one search. It is one of the largest sources of job postings (vagas) in Brazil.
What does the scraper extract for each job? The four text sections of the job page, the benefits, the contract and workplace type, the hiring steps, the address, the dates, and the employer's profile: 81 data fields per row, null when the employer leaves one empty.
Do I need a Gupy account or an API key? No. The actor reads the public job pages anyone can open on Gupy. No login, no candidate profile, no key.
Can I search several keywords, states or companies at once?
Yes. List several keywords or companies, and mix them with links: each is read on its own and a job found twice is saved once. maxItems caps the total for the run. For several states, run one task per state or paste a portal search link per state.
How do the filters combine?
They all apply together. searchQueries: ["vendedor", "atendente"] with state: "MG", workplaceType: "on-site" and postedWithinDays: 7 returns on-site sales and service jobs in Minas Gerais published in the last seven days, and nothing else. On 30 Oct 2026 that input returned 50 jobs in 18 seconds, all in Minas Gerais, all on-site.
How fresh is the data?
Every run reads Gupy live, at the moment it runs, newest jobs first. scrapedAt says when each row was read and daysSincePosted how old the job was at that time.
How many jobs can I get?
As many as Gupy has for your input, up to your maxItems. A common keyword matches thousands of jobs; with no keyword the portal lists every open job in Brazil. Searches deeper than Gupy shows at once go on state by state.
Why are some fields empty? Employers fill in their pages differently. Remote jobs have no address. A job with no benefits heading has no benefits list. Some companies never set a website or LinkedIn on their career page. An empty field is null, never an invented value.
Why does a company name look like a slogan?
Some employers title their career page with a recruiting line ("Vem Pra Vivo"). The actor uses the cleaner of the two names Gupy gives, in companyName, and keeps the page title in careerPageName.
Are the links permanent?
url, jobUrl and applyUrl stay valid while the job is open. When the employer closes a job, its page redirects to the sign-in page, and a later run skips it. careerPageUrl stays valid as long as the company uses Gupy.
Can I use it from my code or an AI agent?
Yes. Call silentflow/gupy-jobs-scraper with apify-client for Python or JavaScript, the Apify API, or any AI agent connected to the Apify MCP server, and read the dataset as JSON, CSV or Excel.
More SilentFlow scrapers
🛒 E-commerce
- JD - JD Products Scraper | JD.com Prices, Brands and Barcodes
- Pinterest - Pinterest Scraper | Pins, Boards and Profiles
- Leboncoin - Leboncoin Scraper | Classified Ads, Prices and Sellers
- TikTok Shop - TikTok Shop Scraper | Products, Sellers and Creator Videos
- Back Market - Back Market Scraper | Refurbished Prices
- Leboncoin - Leboncoin Ad Details Scraper
- Naver - Naver Scraper | Shopping Products, Prices and Reviews
- ImportYeti - ImportYeti Scraper | Suppliers, Importers and Bills of Lading
- Amazon Seller - Amazon Seller Scraper | Emails, Phones and Ratings
- Udemy Course - Udemy Course Scraper
- Allegro - Allegro Scraper | Products, Prices and Sellers
- Naver - Naver Products Scraper | Shopping Prices, Sellers and Ratings
- Naver - Naver Reviews Scraper | Shopping Product Reviews
- 1688 - 1688 Scraper | Products, Reviews, Details, Wholesale Prices
- Store Leads Ecommerce - Store Leads Ecommerce Scraper
- Store Leads - Store Leads Scraper | Shopify Data
- Coupang - Coupang Detail Scraper | Product Prices and Options
- Avito - Avito Scraper | Listings, Prices and Sellers
- Bring a Trailer - Bring a Trailer Scraper
- Leboncoin - Leboncoin Scraper
- Lowes - Lowes Products Scraper | Prices, Stock and Specs
- Mobile.de - Mobile.de Scraper
- Pinterest - Pinterest Scraper
- Taobao - Taobao Scraper | Products, Details, Prices and Sellers
- Alibaba - Alibaba Products Scraper | Wholesale Prices and MOQ
- Avito - Avito Profiles Scraper | Sellers, Ratings and Reviews
- Eventim - Eventim Scraper | Events, Ticket Prices and Venues
- Leboncoin - Leboncoin Details Scraper | Full Ad Data and Sellers
- Udemy - Udemy Scraper
- Vinted Marketplace - Vinted Marketplace Scraper
- Agoda - Agoda Scraper | Hotel Prices and Guest Ratings
- Alibaba - Alibaba Scraper | Products, Supplier Companies and Prices
- AliExpress - AliExpress Reviews Scraper | Feedback, Ratings and Photos
- AliExpress - AliExpress Scraper | Products, Prices and Sales
- Back Market - Back Market Scraper | Refurbished Electronics Prices
- BAUHAUS - BAUHAUS Scraper | Product Prices, EAN and Specs
- CARFAX - CARFAX Scraper | Used Cars, Prices and History
- Che168 - Che168 Scraper | Used Car Listings and Prices
- eBay Marketplace - eBay Marketplace Scraper
- Europages - Europages Scraper | Suppliers and B2B Companies
- Google Hotels - Google Hotels Scraper | Prices, Offers and Ratings
- Homedepot - Homedepot Reviews Scraper | Customer Reviews and Ratings
- Judge - Judge Scraper | Reviews, Ratings and Store Profiles
- Keepa - Keepa Scraper | Amazon Price History and Offers
- MakersRow - MakersRow Scraper | Manufacturers, Capabilities and Reviews
- Mercari - Mercari Scraper | Listings, Sold Prices and Sellers
- Sahibinden - Sahibinden Scraper | Real Estate and Car Listings
- Ticombo - Ticombo Scraper | Ticket Prices and Listings
- Trip - Trip Scraper | Hotels, Prices and Reviews
- Walmart - Walmart Scraper | Prices, Reviews, Sellers, Availability
- Webmotors - Webmotors Scraper | Car Listings, Prices and FIPE
- Woolworths - Woolworths Products Scraper | Prices, Specials and Nutrition
- Amazon - Amazon Product Scraper
- Amazon Marketplace - Amazon Marketplace Scraper
- AutoScout24 - AutoScout24 Scraper
- eBay Listings - eBay Listings Scraper
- Europages Deep Dive Extractor - Europages Deep Dive Extractor | VAT, Decision Makers, ISO Certs
- GasBuddy - GasBuddy Scraper | Gas Prices by Station
- Goofish - Goofish Detail Scraper | Listings, Prices and Sellers
- Mafengwo - Mafengwo Scraper | Attractions, Ratings and Tickets
- Vinted - Vinted Scraper
- Walmart - Walmart Product Scraper
💼 Jobs
- ZipRecruiter - ZipRecruiter Jobs Scraper | Salary, Company & Location Filters
- Multi Board - Multi Board Job Scraper
- Indeed - Indeed Company Reviews Scraper
- Jobright - Jobright Scraper | Jobs, Salaries and H1B Sponsors
- Malt Freelancer - Malt Freelancer Scraper
- Glassdoor - Glassdoor Jobs Scraper
- Malt - Malt Scraper | Freelance Profiles
- Glassdoor Job Listings - Glassdoor Job Listings Scraper
- Jora - Jora Jobs Scraper
- LinkedIn Job Search - LinkedIn Job Search Scraper | Salaries & Seniority
- ATS - ATS Jobs Scraper | Greenhouse, Lever and Ashby
- 🔥 Glassdoor - 🔥 Glassdoor Scraper
- Dice - Dice Jobs Scraper | US Tech Jobs, Salaries, Skills
- Dice Tech - Dice Tech Jobs Scraper
- iimjobs - iimjobs Jobs Scraper | MBA, Finance and Hirist Tech Jobs
- Instahyre - Instahyre Jobs Scraper | Companies, Recruiters and Ratings
- Jora - Jora Scraper | Jobs in Australia, New Zealand, Singapore
- StepStone - StepStone Scraper
- Welcome to the Jungle - Welcome to the Jungle Job Scraper
- YCombinator - YCombinator Jobs Scraper | Startup Jobs, Salaries and Founders
- All - All Jobs Scraper
- Arbeitsagentur - Arbeitsagentur Scraper | German and Austrian Job Board
- Arbeitsagentur - Arbeitsagentur Jobs Scraper
- Cutshort - Cutshort Jobs Scraper | Salaries, Skills and Companies
- iimjobs - iimjobs Scraper | Jobs, Companies and Recruiters
- Indeed - Indeed Companies Scraper | Reviews, Salaries, Interviews
- Indeed - Indeed Jobs Scraper | NLP Skills
- Indeed - Indeed Jobs Scraper | Job Listings in 73 Countries
- LinkedIn - LinkedIn Jobs Scraper
- Naukri & NaukriGulf - Naukri & NaukriGulf Jobs Scraper
- Seek - Seek Job Scraper
- Welcome to the Jungle - Welcome to the Jungle Scraper | Jobs and Company Data
- Ziprecruiter - Ziprecruiter Scraper
🏠 Real estate
- SeLoger - SeLoger Scraper | Real Estate Listings
- Realtor Rental Listings - Realtor Rental Listings Scraper
- Airbnb Professional Host - Airbnb Professional Host Scraper | Emails, Phones, SIRET
- Airbnb Pro Host Contact & - Airbnb Pro Host Contact & Email Scraper
- Bien'ici - Bien'ici Scraper | Property Listings
- Idealista - Idealista Scraper
- SeLoger - SeLoger Scraper | French Property Listings and Agencies
- Trulia Rental Listings - Trulia Rental Listings Scraper
- Rightmove - Rightmove Scraper
- Airbnb Search - Airbnb Search Scraper
- Bienici - Bienici Scraper
- Domclick - Domclick Scraper | Real Estate Listings
- Realestate.com.au - Realestate.com.au Scraper
- Zapimoveis - Zapimoveis Scraper | Real Estate Listings and Prices
- Zillow - Zillow Scraper
- Airbnb Search - Airbnb Search Scraper | Prices, Fees, Amenities, Hosts
- Anjuke - Anjuke Scraper | Rental Listings, Prices and Agents
- Idealista - Idealista Scraper
- Realtor - Realtor Detail Scraper | Property Details and Price History
- Realtor Rental - Realtor Rental Scraper
- Trulia Rental - Trulia Rental Scraper | US Rentals, Prices, Pet Policy
📣 Social media
- LinkedIn Post Search - LinkedIn Post Search Scraper | Keywords, Hashtags & Profiles
- Facebook Search - Facebook Search Scraper
- Instagram - Instagram Story Scraper | Stories & Highlights
- LinkedIn Leads - LinkedIn Leads Scraper | Sales Navigator Export
- Facebook Search - Facebook Search Profiles Scraper | People by Name or Keyword
- TikTok Trend - TikTok Trend Scraper | Trending Hashtags and Videos
- YouTube - YouTube Channel Scraper | Videos, Shorts and Views
- TikTok - TikTok Scraper
- LinkedIn Sales Navigator - LinkedIn Sales Navigator Scraper
- Pinterest - Pinterest Ads Scraper | Ad Library, Reach & Targeting
- Reddit - Reddit Scraper | Posts, Comments and Subreddits
- Snapchat - Snapchat Videos Scraper | Spotlight Videos, MP4 and Stats
- TikTok Creative - TikTok Creative Ads Scraper | Top Ads, Landing Pages & Metrics
- Discord - Discord Scraper | Servers, Member Counts and Invites
- Kwai - Kwai Scraper | Videos, Creators and Hashtags
- Likee - Likee Scraper | Videos, Hashtags and Creators
- LinkedIn Event - LinkedIn Event Scraper
- LinkedIn Hashtag & - LinkedIn Hashtag & Post Scraper | No Cookies
- Meta Ad Library - Meta Ad Library Scraper
- Bandsintown - Bandsintown Scraper | Concerts and Tour Dates
- Bilibili - Bilibili Scraper | Videos, Profiles, Comments, Danmaku
- Discord - Discord Profiles Scraper | Users, Badges and Server Tags
- Facebook Thread - Facebook Thread Profiles Scraper | Followers, Bios & Engagement
- Instagram Engagement - Instagram Engagement Scraper
- Kuaishou - Kuaishou Scraper | Videos, Comments and Creator Stats
- LinkedIn Ads Library - No Cookies - LinkedIn Ads Library Scraper - No Cookies
- OnlyFans - OnlyFans Profile Scraper
- Pinterest - Pinterest Profiles Scraper | Followers, Emails and Bios
- Pinterest - Pinterest Videos Scraper | Video Downloader, MP4 Links, Stats
- Reddit - Reddit Comments Scraper | Search, Threads and Replies
- Reddit - Reddit Profiles Scraper | User Karma, Activity and Communities
- RedNote - RedNote Videos Scraper | Downloader, Transcripts and Stats
- Snapchat - Snapchat Contacts Scraper | Phones, Emails and Websites
- TikTok Lookalike - TikTok Lookalike Scraper | Influencers, Emails and Engagement
- TwitchTracker - TwitchTracker Scraper | Twitch Streamer Stats and Rankings
- X Timeline - X Timeline Scraper | Tweets and Engagement Stats
- Xigua - Xigua Scraper | Videos, Creators and Downloads
- YouTube Autocomplete - YouTube Autocomplete Scraper | Keyword Suggestions
- Douyin - Douyin Comments Scraper | Comments, Likes and IP Regions
- Facebook - Facebook Company Scraper | Emails, Phones, Ratings
- Facebook Business Page - Facebook Business Page Scraper
- OnlyFans - OnlyFans Creator Scraper
- Reddit - Reddit Scraper | Comments, Posts and Users
- RedNote - RedNote Detail Scraper | Xiaohongshu Details, Images, Videos
- Skool Group - Skool Group Scraper
- Skool Community - Skool Community Scraper
- Snapchat - Snapchat Ads Scraper | Ad Library, Impressions & Targeting
- Weibo - Weibo Scraper | Posts, Profiles and Engagement
- YouTube - YouTube Transcript Scraper
🏢 Business data
- LinkedIn Company Search - LinkedIn Company Search Scraper | Profiles & Firmographics
- Ctrip - Ctrip Scraper | Attractions, Tickets and Reviews
- LinkedIn People Search - LinkedIn People Search Scraper | Profiles & Companies
- 2GIS - 2GIS Reviews Scraper | Ratings, Photos and Owner Replies
- Teachable Course - Teachable Course Scraper
- Website Tech Stack - Website Tech Stack Scraper
- Teachable - Courses, Prices & Instructors - Teachable Scraper - Courses, Prices & Instructors
- Trustpilot - Trustpilot Scraper | Reviews, Ratings and Company Contacts
✈️ Travel
- Tencent - Tencent Scraper | Maps Places, Phones and Ratings
- Flight Price - Flight Price Scraper
- Zomato - Zomato Reviews Scraper | Restaurant Ratings and Replies
- Booking.com Hotel - Booking.com Hotel Scraper
- Despegar - Despegar Reviews Scraper | Hotel Reviews and Ratings
- Google Maps - Google Maps Scraper
- Kakao - Kakao Scraper | Map Places, Reviews and Phones
- OpenTable - OpenTable Reviews Scraper | Restaurant Reviews and Ratings
- TheFork - TheFork Scraper | Restaurants, Menus and Ratings
- Booking - Booking Scraper | Hotel Prices, Photos, Availability
- Trip - Trip Reviews Scraper | Hotel Reviews and Ratings
- Viator - Viator Reviews Scraper | Tour Reviews and Ratings
🎯 Lead generation
- Northdata - Northdata Company Scraper
- Dealroom - Dealroom Scraper | Companies and Investors
- ZocDoc - ZocDoc Scraper | Doctors, Reviews and Availability
- UK Companies House - UK Companies House Enricher
- BuiltWith - BuiltWith Scraper | Tech Stacks and Top Sites
- CNPJ Brazilian - CNPJ Brazilian Company Enricher
- Justdial - Justdial Companies Scraper | Business Leads, Phones and Emails
- PagesJaunes - PagesJaunes Scraper | French Business Emails and SIRET
- PagesJaunes - PagesJaunes Business Scraper
- SIRET - SIRET Company Enricher
- SoftwareAdvice - SoftwareAdvice Scraper | Reviews, Ratings and Pros & Cons
- Company Data - Company Data Scraper | Emails, Phones and Tech Stack
- Dealroom Startup Data - Dealroom Startup Data Scraper
- Delaware - Delaware Scraper | Corporations, LLCs and Registered Agents
- French Company Prospector - French Company Prospector
- G2 - G2 Reviews Scraper
- Pappers - Pappers Scraper | French Companies, Directors & Financials
- SEC - SEC Scraper | EDGAR Filings and Company Data
- Sunbiz - Sunbiz Companies Scraper | New Florida Business Leads
- Sunbiz - Sunbiz Scraper | Florida Companies and Officers
- USPTO - USPTO Scraper | Trademark Search and Status
- Clutch - Clutch Scraper | Agencies, Reviews, Ratings, Services
- Clutch Agency - Clutch Agency Scraper
- Domain - Domain Enricher
- Google Ads Transparency - Google Ads Transparency Scraper
- KVK - KVK Scraper | Dutch Companies and SBI Codes
- SIRET French - SIRET French Company Enricher
- ThomasNet Suppliers - ThomasNet Suppliers Scraper
- ZocDoc - ZocDoc Scraper
🔎 SEO
- Similarweb - Similarweb Scraper | Website Traffic, Rankings and Competitors
- Scribd - Scribd Scraper | Documents, Authors and Views
- SpyFu - SpyFu Scraper | SEO, PPC and Competitor Data
- Apple - Apple Reviews Scraper | App Store Reviews and Ratings
- Apple - Apple Scraper | App Store Apps, Ratings and Charts
- Bing - Bing Enricher Scraper | Mobile Friendly Test and Indexing
- Google News - Google News Scraper
- Yandexsearch - Yandexsearch Scraper | Search Results and Rankings
📈 Marketing
🎬 Video
📰 News
- ForexFactory - ForexFactory Scraper | Economic Calendar and Forecasts
🧰 More tools
- Maersk - Maersk Scraper | Vessel Schedules and Port Calls
- FanDuel - FanDuel Scraper | Odds, Spreads and Player Props
- PrizePicks - PrizePicks Scraper | Player Props, Lines and Projections
Support
Need something this scraper does not do yet? We ship features fast.
- Feature requests go straight to our backlog
- Enterprise needs? We do custom integrations and high-volume plans
- Pricing questions? Check the Monetization tab on the actor page
Response time: usually under 24 hours.
Legal compliance
This Actor extracts publicly available data from Gupy: job postings and company career pages that anyone can open without an account. It does not bypass any login, paywall, or CAPTCHA, and it reads no candidate profile or application. Users are responsible for complying with Gupy's terms of service and applicable data protection laws (GDPR, CCPA, PIPL, and Brazil's LGPD where relevant). Job rows describe positions and companies; when a text names a person (a recruiter in a description, for instance), handle it as personal data and only for a lawful purpose. The data returned is informational; verify it before any regulated use.
Built by SilentFlow for job boards, recruiters, sales teams and labor-market analysts who want Gupy's vagas as data, not browser tabs.


