
Urlscan Scraper | Scan Reports, Verdicts and IPs
Pricing
from $2.04 / 1,000 scans
Urlscan Scraper | Scan Reports, Verdicts and IPs
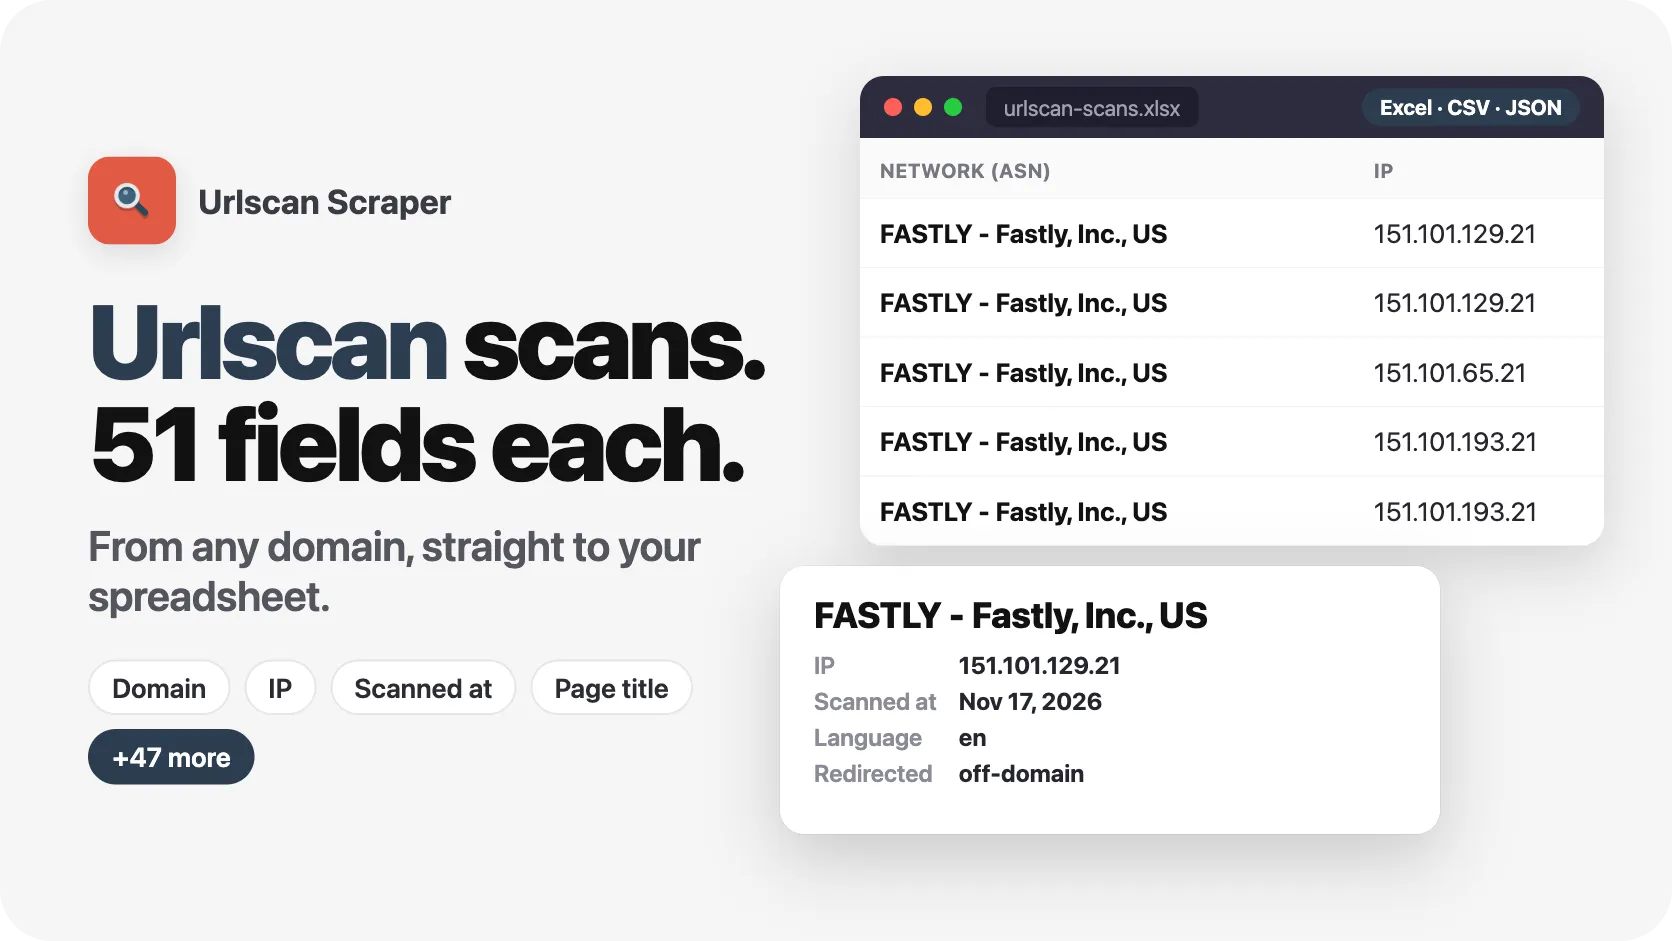
Urlscan scraper for urlscan.io public scan reports, no account or API key. Paste domains, URLs, IPs or scan IDs and get one flat row per scan with 51 fields: phishing verdict, targeted brands, hosting IP, ASN, country, TLS certificate, domain age and contacted domains. 20 scans in 2 seconds.
Pricing
from $2.04 / 1,000 scans
Rating
0.0
(0)
Developer
SilentFlow
Maintained by CommunityActor stats
0
Bookmarked
2
Total users
1
Monthly active users
2 days ago
Last modified
Categories
Features
Share
Urlscan Scraper | urlscan.io Scan Reports, Phishing Verdicts, IPs and Certificates (2026)
From SilentFlow. Creators of Facebook Search Scraper and JD Products Scraper (#1 for “jd” in Apify Store search), with 1,000,000+ combined lifetime runs.
Paste the domains, URLs and IPs from your alerts and get back every public urlscan.io scan of them as flat rows: verdict, targeted brands, hosting IP, network and country, certificate, domain age, the domains and IPs the page contacted, and a screenshot link. 20 full scan reports in 11 seconds, no urlscan.io account and no API key.
Why choose this actor?
Opening urlscan.io reports one tab at a time to triage an alert? Copying the IP, the network and the certificate issuer of a suspicious page into a ticket by hand? Writing a script against an API that needs a key, then flattening nested JSON before your SIEM or spreadsheet can read it?
- Look up a whole alert in one run. Put domains, full URLs, IPv4 and IPv6 addresses, network numbers (ASNs), SHA-256 file hashes and scan IDs in the same list, one per line, defanged or not (
hxxps://evil[.]comworks). Our test run took an IP, an ASN, a URL and a defanged domain (github[.]com) and returned the 4 latest scans of each: 16 rows in 36 seconds, each row tagged with the indicator that produced it. - The full scan report on every row, not just the search index. Each row carries the urlscan.io verdict, the brands the page imitates, the hosting IP with its network and country, the certificate issuer and age, the domain age, the Cisco Umbrella rank, every domain and IP the page contacted, its certificates and the hashes of the files it loaded. On the default run, 45 of the 53 columns were filled on all 20 rows, with 115 contacted domains and 82 certificates between them.
- Scans you already have, at any age. Paste scan IDs or report links from a ticket and each public scan comes back as one row, whatever its date. Our lookup of 3 IDs returned all 3, including a test phishing page scanned in February 2025 with its "Potentially Malicious" verdict and its targeted brand.
Try your first scan reports
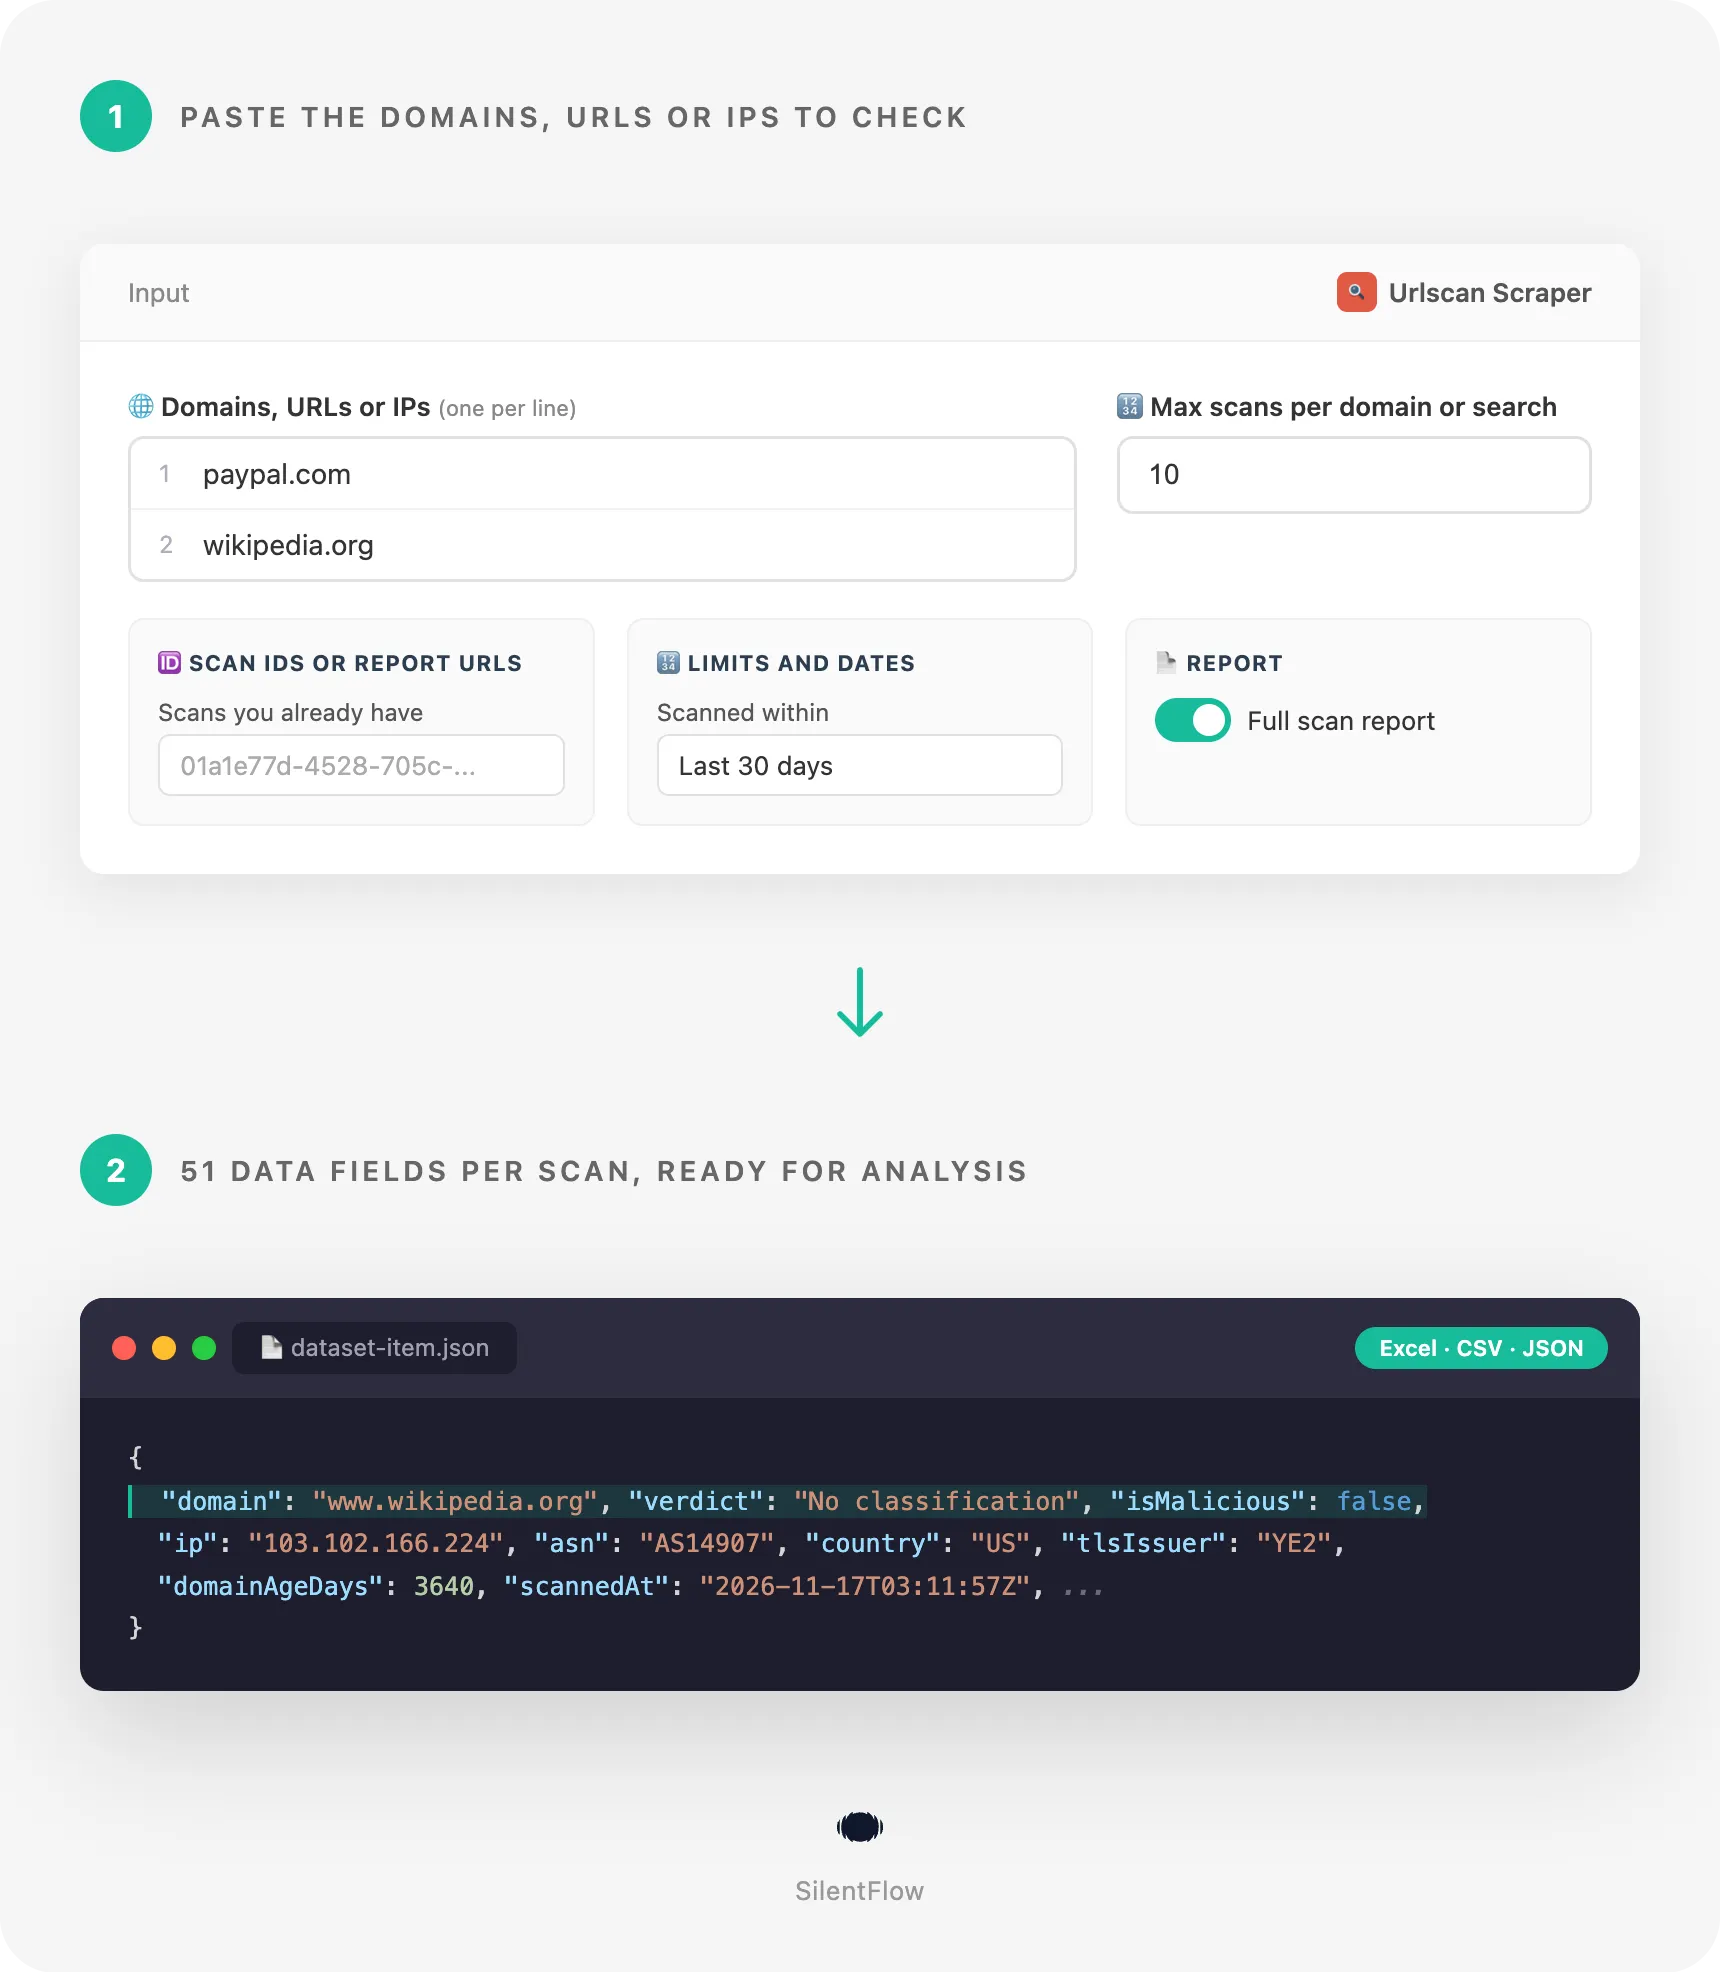
Paste this input in the Input tab, or send it from the API, and run. You get the 10 latest public scans of paypal.com and the 10 latest of wikipedia.org, subdomains included, each with its full report. Our test run returned 20 rows in 11 seconds, out of 617 public scans of paypal.com and 4,141 of wikipedia.org in the last 30 days.
The Apify Free plan is enough to run it: no credit card, no urlscan.io account, no API key.
Copy to your AI assistant
Paste this block into Claude, ChatGPT, Cursor or any coding assistant to give it the full picture of this actor:
How to scrape urlscan.io scan reports
Three inputs, from the simplest to the most targeted. Each one runs as is.
Get the latest scans of one domain
The 5 most recent public scans of a domain and its subdomains, with their full report.
Pull the reports of scans you already have
Paste scan IDs or report links from a ticket, a feed or a colleague. Each public scan returns one row, whatever its age.
Hunt pages tagged as phishing in the last 24 hours
A urlscan.io search, restricted to the last day, newest first. Our run of this input returned 15 rows in 19 seconds.
Input parameters
| Parameter | Type | Default | What it does |
|---|---|---|---|
domains | array of strings | Domains, URLs, IPs, ASNs or SHA-256 hashes to look up, all in one run. Each returns its latest public scans. | |
scanIds | array of strings | Scan IDs or report links. One row per public scan, at any age, whatever maxItems is. | |
query | string | A urlscan.io search, with the same syntax as the urlscan.io search page. | |
maxItems | integer | 10 | Maximum scans for each entry of domains, and for query. |
dateRange | string | 30 | Only scans from the last 1, 3, 7, 14 or 30 days. |
includeFullReport | boolean | true | Reads each scan's report page for the verdict, brands, contacted hosts, certificates and page stats. |
debugMode | boolean | false | Writes detailed progress to the log. |
Give at least one of domains, scanIds or query. The three can be combined in one run: scan IDs are read first, then each indicator, then the search. A scan found by two inputs is saved once.
What you can put in Domains, URLs or IPs
| You paste | The actor returns |
|---|---|
paypal.com | Scans whose page or submitted URL is on paypal.com or any subdomain (www.paypal.com, checkout.paypal.com) |
https://example.com/login | Scans of that exact URL, submitted or reached after redirects |
example.com/login | Scans of that URL over http or https |
103.102.166.224 or 2a00:1450:4001:800::2014 | Scans whose page was served from that IP |
AS13335 | Scans whose page was served from that network |
| a 64-character SHA-256 hash | Scans that loaded a file with that hash (script, image, page) |
hxxps://evil[.]example/x | Defanged forms are read as the real address |
https://urlscan.io/result/<id>/ | The scan behind the link, like in Scan IDs |
Values that are none of these are skipped with a note in the log, and the rest of the run goes on.
What you can put in Scan IDs or report URLs
The scan ID (01a1e77d-4528-705c-9a3d-a5dc65d254ad), the report link (https://urlscan.io/result/01a1e77d-4528-705c-9a3d-a5dc65d254ad/), the screenshot link, or a link from urlscan Pro. Upper or lower case both work.
What data can you extract from urlscan.io?
Every row is one public scan with 53 fields, in the same order on every row:
| Group | Fields | Count |
|---|---|---|
| Identity | id, url, submittedUrl, effectiveUrl, pageTitle, domain, apexDomain | 7 |
| Verdict | verdict, isMalicious, targetedBrands, tags, scanStatus | 5 |
| Hosting | ip, ptr, asn, asnName, country, server, httpStatus, mimeType, language, redirected, redirectChain | 11 |
| Certificate and domain | tlsIssuer, tlsValidFrom, tlsValidDays, tlsAgeDays, domainAgeDays, apexDomainAgeDays, umbrellaRank, timesScanned | 8 |
| Page stats | requests, uniqueIps, uniqueCountries, uniqueDomains, httpsPercent, dataLength, encodedDataLength, cookiesCount, outgoingLinks | 9 |
| Contacted hosts and content | contactedDomains, contactedIps, certificates, technologies, resourceHashes | 5 |
| Time and source | scannedAt, submissionMethod, submitterCountry, scanCountry, visibility | 5 |
| Media | screenshotUrl | 1 |
| Run | input, scrapedAt | 2 |
Good to know when you use the data:
idis urlscan.io's scan ID and never changes;urlis the permanent public report page of the scan.screenshotUrlpoints to the screenshot urlscan.io took during the scan, kept with the report.scannedAt,tlsValidFromandscrapedAtare RFC 3339 timestamps in UTC. Ages (domainAgeDays,tlsAgeDays) are counted on the day of the scan, not on the day of your run.inputrepeats the domain, URL, IP, scan ID or query that produced the row, so you can join results back to your alert list.- A field the page does not show is
null, never an empty string. Lists are empty ([]) when the report was read and holds nothing, for exampletargetedBrandson a page that imitates no brand. scanStatusisfailedwhen urlscan.io could not load the page (the site was down or refused the scanner). The row still tells you when it was submitted, from which country and for which URL.- With
includeFullReportoff, the 16 fields that only the report page shows stay empty:verdict,isMalicious,targetedBrands,redirectChain,timesScanned,uniqueDomains,httpsPercent,cookiesCount,outgoingLinks,contactedDomains,contactedIps,certificates,technologies,resourceHashes,submitterCountryandscanCountry.
Output example
One real row from the default run (17 November 2026): a page submitted on a Romanian domain that redirected to wikipedia.org.
Advanced usage
Five recipes for the jobs security teams run every day. Each JSON runs as is; swap in your own values.
Enrich every indicator of an alert with its latest scan
One row per indicator, the most recent scan of each, ready to paste into the ticket. Mixed types and defanged values can sit in the same list.
Watch for pages that copy your brand, every day
Schedule this search daily in Apify (Schedules tab) with the last 24 hours: pages titled like your brand that are not on your own domain. Sort the dataset by isMalicious and domainAgeDays to see young lookalike domains first. When we ran it over the last 7 days, urlscan.io held 4,925 matching scans, and 2 of the first 5 rows were "Potentially Malicious" pages with PayPal as the targeted brand, on a domain first seen 3 days earlier.
Find what is hosted on your network
For a hosting provider's abuse desk or an attack surface review: every page scanned on your network in the last week, with the verdict and the brands it targets.
Pivot from one file to every page that loaded it
Take a hash from resourceHashes of a phishing page (a kit's script, a logo) and find every other page that loaded the same file in the last 30 days.
Build a large list of scans quickly
Without the full report, each row keeps its URLs, IP, network, country, server, status, certificate, domain age, Umbrella rank and page stats, and a run reads up to 100 scans per page of results. Use it to size a campaign before you pull full reports for the scans that matter.
FAQ
What is urlscan.io? urlscan.io is a German service that opens a URL in a browser and records everything the page did: where it redirected, which servers and domains it contacted, which certificate it used, what it looked like (screenshot) and whether it looks like phishing. Security teams, researchers and automated feeds submit thousands of URLs every hour, and public scans are searchable by anyone.
Do I need a urlscan.io account or an API key? No. The actor reads the public scans and their public report pages. You do not create an account, you do not paste a key, and nothing is logged in on your behalf.
Which scans can I get? Public scans only. Unlisted and private scans, which urlscan.io keeps for its paying customers, are not visible without an account and are not returned. Searches by domain, URL, IP, ASN, hash or query cover the last 30 days, the window urlscan.io gives to anyone without an account. Scans you name by ID come back whatever their age.
Why do most rows say "No classification"?
That is urlscan.io's own verdict, copied as the report page shows it. Most scanned pages are ordinary websites, and urlscan.io only marks a page "Potentially Malicious" or "Malicious" when it has evidence. All 20 rows of our default run (paypal.com and wikipedia.org) read "No classification"; the February 2025 test phishing page of our lookup run reads "Potentially Malicious" with its targeted brand. Tags (tags) come from whoever submitted the scan, so a scan tagged "phishing" can still carry "No classification".
What does Max scans count?
For each entry of Domains, URLs or IPs, the number of its latest scans to save; for the search query, the total for the query. Scan IDs are never cut: each public ID returns its row. Use 1 to get the latest scan of each indicator, a few hundred to collect everything on one domain or network.
How fast is a run? In our tests on 17 November 2026: 20 scans with full reports in 11 seconds, 15 phishing-tagged scans in 19 seconds, and 16 scans of four different indicators in 36 seconds. Runs of thousands of scans take longer with the full report, because urlscan.io serves report pages at a steady pace; turn the full report off when you only need the list.
Can I mix domains, scan IDs and a search in one run?
Yes. Scan IDs are read first, then each domain, URL or IP, then the search. A scan found by two inputs is saved once, and the input field tells you which input brought it.
What happens with a scan ID that does not exist? It is skipped and the log names it. No empty or error row is added to your dataset, and the other IDs of the run are still read.
Are the report and screenshot links permanent?
The report link (url) and the scan ID are urlscan.io's permanent identifiers for the scan. The screenshot link points to the image urlscan.io stored with the report. Live pages change, so a scan is a picture of the page at scannedAt: run a new lookup to see what a domain serves today.
Can I watch my brand or my network every day?
Yes. Save an input with dateRange set to the last 24 hours and add a daily schedule in Apify. Each run returns the scans of that day; connect the dataset to Slack, email, Google Sheets or your SIEM through Apify integrations or webhooks.
More SilentFlow scrapers
🛒 E-commerce
- JD - JD Products Scraper | JD.com Prices, Brands and Barcodes
- Pinterest - Pinterest Scraper | Pins, Boards and Profiles
- Udemy Course - Udemy Course Scraper
- TikTok Shop - TikTok Shop Scraper | Products, Sellers and Creator Videos
- Leboncoin - Leboncoin Scraper | Classified Ads, Prices and Sellers
- Leboncoin - Leboncoin Ad Details Scraper
- Allegro - Allegro Scraper | Products, Prices and Sellers
- Back Market - Back Market Scraper | Refurbished Prices
- Naver - Naver Scraper | Shopping Products, Prices and Reviews
- Coupang - Coupang Scraper | Product Details, Prices and Options
- Naver - Naver Reviews Scraper | Shopping Product Reviews
- Taobao - Taobao Scraper | Products, Details, Prices and Sellers
- ImportYeti - ImportYeti Scraper | Suppliers, Importers and Bills of Lading
- Amazon Seller - Amazon Seller Scraper | Emails, Phones and Ratings
- Keepa - Keepa Scraper | Amazon Price History and Offers
- 1688 - 1688 Scraper | Products, Reviews, Details, Wholesale Prices
- Eventim - Eventim Scraper | Events, Ticket Prices and Venues
- Naver - Naver Products Scraper | Shopping Prices, Sellers and Ratings
- Wildberries - Wildberries Scraper | Product Details, Prices and Sellers
- Avito - Avito Scraper | Listings, Prices and Sellers
- Pinterest - Pinterest Scraper
- Leboncoin - Leboncoin Scraper
- 1688 - 1688 Reviews Scraper | Ratings, Buyer Photos and Variants
- Alibaba - Alibaba Scraper | Products, Supplier Companies and Prices
- Back Market - Back Market Scraper | Refurbished Electronics Prices
- Bring a Trailer - Bring a Trailer Scraper
- Ctrip - Ctrip Scraper | Attractions, Tickets and Reviews
- GasBuddy - GasBuddy Scraper | Gas Prices by Station
- Store Leads Ecommerce - Store Leads Ecommerce Scraper
- Store Leads - Store Leads Scraper | Shopify Data
- Vinted Marketplace - Vinted Marketplace Scraper
- Avito - Avito Profiles Scraper | Sellers, Ratings and Reviews
- BAUHAUS - BAUHAUS Scraper | Product Prices, EAN and Specs
- CARFAX - CARFAX Scraper | Used Cars, Prices and History
- Goofish - Goofish Detail Scraper | Listings, Prices and Sellers
- Leboncoin - Leboncoin Details Scraper | Full Ad Data and Sellers
- Lowes - Lowes Products Scraper | Prices, Stock and Specs
- Sahibinden - Sahibinden Scraper | Real Estate and Car Listings
- VividSeats - VividSeats Scraper | Tickets, Prices and Events
- Acquire - Acquire Scraper | Startups for Sale & Prices
- Agoda - Agoda Scraper | Hotel Prices and Guest Ratings
- Alibaba - Alibaba Products Scraper | Products, Suppliers, Prices and MOQ
- Barnes and Noble - Barnes and Noble Scraper | Book Prices and Availability
- Che168 - Che168 Scraper | Used Car Listings and Prices
- Coles - Coles Products Scraper | Prices, Specials and Nutrition
- eBay Marketplace - eBay Marketplace Scraper
- Encar - Encar Scraper | Used Car Listings and Accident History
- Europages - Europages Scraper | Suppliers and B2B Companies
- Fashionphile - Fashionphile Scraper | Listings, Prices and Sold Items
- GetYourGuide - GetYourGuide Scraper | Tours, Activities, Prices & Reviews
- Google Hotels - Google Hotels Scraper | Prices, Offers and Ratings
- Homedepot - Homedepot Reviews Scraper | Customer Reviews and Ratings
- Judge - Judge Scraper | Reviews, Ratings and Store Profiles
- MakersRow - MakersRow Scraper | Manufacturers, Capabilities and Reviews
- Mobile.de - Mobile.de Scraper
- OfferUp - OfferUp Scraper | Listings, Prices and Sellers
- OLX - OLX Scraper | Brazil Listings, Prices and Sellers
- RA - RA Scraper | Events, Lineups and Tickets
- Ticombo - Ticombo Scraper | Ticket Prices and Listings
- Tradeindia - Tradeindia Scraper | Suppliers, Products and Contacts
- Trip - Trip Scraper | Hotels, Prices and Reviews
- Udemy - Udemy Scraper
- Walmart - Walmart Scraper | Prices, Reviews, Sellers, Availability
- Webmotors - Webmotors Scraper | Car Listings, Prices and FIPE
- Woolworths - Woolworths Products Scraper | Prices, Specials and Nutrition
- YandexMarket - YandexMarket Scraper | Products, Prices and Sellers
- Zap - Zap Scraper | Prices and Store Offers
- AliExpress - AliExpress Reviews Scraper | Product Reviews, Ratings, Feedback
- AliExpress - AliExpress Scraper | Products, Prices and Sales
- Amazon - Amazon Product Scraper
- Amazon Marketplace - Amazon Marketplace Scraper
- Apple - Apple Scraper | App Store Apps, Ratings and Charts
- AutoScout24 - AutoScout24 Scraper
- Carousell - Carousell Scraper | Listings, Prices and Sellers
- eBay Listings - eBay Listings Scraper
- Europages Deep Dive Extractor - Europages Deep Dive Extractor | VAT, Decision Makers, ISO Certs
- Mercari - Mercari Scraper | Listings, Sold Prices and Sellers
- TickPick - TickPick Scraper | Ticket Prices and Events
- Uniqlo - Uniqlo Scraper | Products, Prices and Stock
- Vinted - Vinted Scraper
- Walmart - Walmart Product Scraper
💼 Jobs
- ZipRecruiter - ZipRecruiter Jobs Scraper | Salary, Company & Location Filters
- Jobright - Jobright Scraper | Jobs, Salaries and H1B Sponsors
- Malt Freelancer - Malt Freelancer Scraper
- Glassdoor Job Listings - Glassdoor Job Listings Scraper
- Multi Board - Multi Board Job Scraper
- Indeed - Indeed Company Reviews Scraper
- Glassdoor - Glassdoor Jobs Scraper
- Jora - Jora Jobs Scraper
- LinkedIn Job Search - LinkedIn Job Search Scraper | Salaries & Seniority
- Malt - Malt Scraper | Freelance Profiles
- Welcome to the Jungle - Welcome to the Jungle Scraper | Jobs and Company Data
- Arbeitsagentur - Arbeitsagentur Jobs Scraper
- Cutshort - Cutshort Jobs Scraper | Salaries, Skills and Companies
- Dice - Dice Scraper | US Tech Jobs, Salaries and Skills
- Dice Tech - Dice Tech Jobs Scraper
- Francetravail - Francetravail Scraper | Job Offers and Salaries
- Freelancermap - Freelancermap Scraper | Projects, Skills and Companies
- 🔥 Glassdoor - 🔥 Glassdoor Scraper
- Gupy - Gupy Jobs Scraper | Brazil Jobs and Employers
- iimjobs - iimjobs Jobs Scraper | MBA, Finance and Hirist Tech Jobs
- Indeed - Indeed Companies Scraper | Reviews, Salaries, Interviews
- Instahyre - Instahyre Jobs Scraper | Companies, Recruiters and Ratings
- Jora - Jora Scraper | Jobs in Australia, New Zealand, Singapore
- Kununu - Kununu Scraper | Employee Reviews, Ratings and Interviews
- Naukri & NaukriGulf - Naukri & NaukriGulf Jobs Scraper
- Totaljobs - Totaljobs Jobs Scraper | UK Job Listings and Salaries
- Welcome to the Jungle - Welcome to the Jungle Job Scraper
- YCombinator - YCombinator Jobs Scraper | Startup Jobs, Salaries and Founders
- All - All Jobs Scraper
- Arbeitsagentur - Arbeitsagentur Scraper | German and Austrian Job Board
- ATS - ATS Jobs Scraper | Greenhouse, Lever and Ashby
- iimjobs - iimjobs Scraper | Jobs, Companies and Recruiters
- Indeed - Indeed Jobs Scraper | NLP Skills
- Indeed - Indeed Jobs Scraper | Job Listings in 73 Countries
- LinkedIn - LinkedIn Jobs Scraper
- Seek - Seek Job Scraper
- StepStone - StepStone Scraper
- Zhaopin - Zhaopin Scraper | Jobs, Salaries and Companies
- Ziprecruiter - Ziprecruiter Scraper
🏠 Real estate
- SeLoger - SeLoger Scraper | Real Estate Listings
- Airbnb Pro Host Contact & - Airbnb Pro Host Contact & Email Scraper
- Realtor Rental Listings - Realtor Rental Listings Scraper
- Airbnb Professional Host - Airbnb Professional Host Scraper | Emails, Phones, SIRET
- Bien'ici - Bien'ici Scraper | Property Listings
- Idealista - Idealista Scraper
- Realestate.com.au - Realestate.com.au Scraper
- SeLoger - SeLoger Scraper | French Property Listings and Agencies
- Trulia Rental Listings - Trulia Rental Listings Scraper
- Bienici - Bienici Scraper
- Domclick - Domclick Scraper | Real Estate Listings
- Realtor - Realtor Detail Scraper | Property Details and Price History
- Airbnb - Airbnb Detail Scraper | Listings, Hosts and Availability
- Cian - Cian Scraper | Real Estate Listings and Phones
- Fincaraiz - Fincaraiz Scraper | Real Estate Listings and Prices
- Imovelweb - Imovelweb Scraper | Real Estate Listings
- Propwire - Propwire Scraper | Property Owner Leads
- Redfin - Redfin Detail Scraper | Property Data, Estimates and Flood Risk
- Redfin - Redfin Scraper | Listings, Sold Homes and Agents
- Rightmove - Rightmove Scraper
- SeLoger - SeLoger Products Scraper | Property Listings and Agencies
- Zapimoveis - Zapimoveis Scraper | Real Estate Listings and Prices
- Zillow - Zillow Scraper
- Airbnb Search - Airbnb Search Scraper | Prices, Fees, Amenities, Hosts
- Airbnb Search - Airbnb Search Scraper
- Anjuke - Anjuke Scraper | Rental Listings, Prices and Agents
- Idealista - Idealista Scraper
- OpenRent - OpenRent Scraper | Rental Listings and Landlords
- Realtor Rental - Realtor Rental Scraper
- Trulia Rental - Trulia Rental Scraper | US Rentals, Prices, Pet Policy
📣 Social media
- Douyin - Douyin Transcript Scraper | Transcripts, Subtitles and SRT
- Facebook Search - Facebook Search Scraper
- LinkedIn Post Search - LinkedIn Post Search Scraper | Keywords, Hashtags & Profiles
- Instagram - Instagram Story Scraper | Stories & Highlights
- Facebook Search - Facebook Search Profiles Scraper | People by Name or Keyword
- TikTok Creative - TikTok Creative Ads Scraper | Top Ads, Landing Pages & Metrics
- LinkedIn Leads - LinkedIn Leads Scraper | Sales Navigator Export
- TikTok Trend - TikTok Trend Scraper | Trending Hashtags and Videos
- OnlyFans - OnlyFans Profile Scraper
- Reddit - Reddit Scraper | Posts, Comments and Subreddits
- TwitchTracker - TwitchTracker Scraper | Twitch Streamer Stats and Rankings
- Discord - Discord Scraper | Servers, Member Counts and Invites
- LinkedIn Hashtag & - LinkedIn Hashtag & Post Scraper | No Cookies
- Pinterest - Pinterest Ads Scraper | Ad Library, Reach & Targeting
- Snapchat - Snapchat Videos Scraper | Spotlight Videos, MP4 and Stats
- Discord - Discord Profiles Scraper | Users, Badges and Server Tags
- LinkedIn People Search - LinkedIn People Search Scraper | Profiles & Companies
- LinkedIn Sales Navigator - LinkedIn Sales Navigator Scraper
- Reddit - Reddit Comments Scraper | Search, Threads and Replies
- Snapchat - Snapchat Contacts Scraper | Phones, Emails and Websites
- Twitch - Twitch Contacts Scraper | Emails and Social Links
- YouTube - YouTube Channel Scraper | Videos, Shorts and Views
- Douyin - Douyin Hashtags Scraper | Views, Creators and Topics
- Facebook Business Page - Facebook Business Page Scraper
- Kwai - Kwai Scraper | Videos, Creators and Hashtags
- Likee - Likee Scraper | Videos, Hashtags and Creators
- LinkedIn Ads Library - No Cookies - LinkedIn Ads Library Scraper - No Cookies
- LinkedIn Event - LinkedIn Event Scraper
- Pornhub - Pornhub Videos Scraper | Search, Tags and Stream Links
- Reddit - Reddit Profiles Scraper | User Karma, Activity and Communities
- Skool Community - Skool Community Scraper
- TikTok Lookalike - TikTok Lookalike Scraper | Influencers, Emails and Engagement
- X Timeline - X Timeline Scraper | Tweets and Engagement Stats
- Bandsintown - Bandsintown Scraper | Concerts and Tour Dates
- Bilibili - Bilibili Scraper | Videos, Comments, Profiles, Danmaku
- Bluesky - Bluesky Scraper | Posts, Profiles and Followers
- Douyin - Douyin Comments Scraper | Comments, Likes and IP Regions
- Facebook Thread - Facebook Thread Profiles Scraper | Followers, Bios & Engagement
- Kuaishou - Kuaishou Scraper | Videos, Comments and Creator Stats
- Meta Ad Library - Meta Ad Library Scraper
- Pikabu - Pikabu Scraper | Posts, Comments and Views
- Pinterest - Pinterest Profiles Scraper | Followers, Emails and Bios
- Pinterest Trends - Pinterest Trends Scraper | Trending Keywords and Forecasts
- Pinterest - Pinterest Videos Scraper | Video Downloader, MP4 Links, Stats
- RedNote - RedNote Videos Scraper | Xiaohongshu Videos, Transcripts, Stats
- Snapchat - Snapchat Enricher Scraper | Account Age, Activity and Contacts
- Telegram - Telegram Comments Scraper | Replies, Authors and Reactions
- Telegram - Telegram Scraper | Channel Posts, Views and Reactions
- TikTok - TikTok Scraper
- Twitch - Twitch Scraper | Streamers, Emails and Clips
- Xigua - Xigua Scraper | Videos, Creators and Downloads
- YouTube Autocomplete - YouTube Autocomplete Scraper | Keyword Suggestions
- YouTube - YouTube Transcript Scraper
- Facebook - Facebook Company Scraper | Emails, Phones, Ratings
- Instagram Engagement - Instagram Engagement Scraper
- LoyalFans - LoyalFans Scraper | Creator Profiles and Prices
- OnlyFans - OnlyFans Profiles Scraper | Creator Prices, Stats & Links
- OnlyFans - OnlyFans Creator Scraper
- Reddit - Reddit Scraper | Comments, Posts and Users
- RedNote - RedNote Detail Scraper | Xiaohongshu Details, Images, Videos
- Skool Group - Skool Group Scraper
- Snapchat - Snapchat Ads Scraper | Ad Library, Impressions & Targeting
- Telegram - Telegram Posts Scraper | Views, Reactions and Comments
- Weibo - Weibo Scraper | Posts, Profiles, Followers and Engagement
🏢 Business data
- LinkedIn Company Search - LinkedIn Company Search Scraper | Profiles & Firmographics
- Teachable Course - Teachable Course Scraper
- Website Tech Stack - Website Tech Stack Scraper
- Teachable - Courses, Prices & Instructors - Teachable Scraper - Courses, Prices & Instructors
- Trustpilot - Trustpilot Scraper | Reviews, Ratings and Company Contacts
✈️ Travel
- Tencent - Tencent Scraper | Maps Places, Phones and Ratings
- Viator - Viator Reviews Scraper | Tour Reviews and Ratings
- Booking.com Hotel - Booking.com Hotel Scraper
- Despegar - Despegar Reviews Scraper | Hotel Reviews and Ratings
- 2GIS - 2GIS Reviews Scraper | Ratings, Photos and Owner Replies
- Apple Maps - Apple Maps Scraper | Places, Phones and Emails
- Flightpoints - Flightpoints Scraper | Award Flights, Miles and Seats
- Kakao - Kakao Scraper | Map Places, Reviews and Phones
- Mafengwo - Mafengwo Scraper | Attractions, Ratings and Tickets
- OpenTable - OpenTable Reviews Scraper | Restaurant Reviews and Ratings
- Resy - Resy Scraper | Restaurants and Open Tables
- TheFork - TheFork Scraper | Restaurants, Menus and Ratings
- Trip - Trip Reviews Scraper | Hotel Reviews and Ratings
- Zomato - Zomato Reviews Scraper | Restaurant Ratings and Replies
- Booking - Booking Scraper | Hotel Prices, Photos, Availability
- Flight Price - Flight Price Scraper
- Google Maps - Google Maps Scraper
🎯 Lead generation
- Dealroom - Dealroom Scraper | Companies and Investors
- Northdata - Northdata Company Scraper
- ZocDoc - ZocDoc Scraper | Doctors, Reviews and Availability
- UK Companies House - UK Companies House Enricher
- KVK - KVK Scraper | Dutch Companies and SBI Codes
- SIRET - SIRET Company Enricher
- PagesJaunes - PagesJaunes Scraper | French Business Emails and SIRET
- Dealroom Startup Data - Dealroom Startup Data Scraper
- Similarweb - Similarweb Scraper | Website Traffic, Rankings and Competitors
- BuiltWith - BuiltWith Scraper | Tech Stacks and Top Sites
- Justdial - Justdial Companies Scraper | Business Leads, Phones and Emails
- PagesJaunes - PagesJaunes Business Scraper
- ThomasNet Suppliers - ThomasNet Suppliers Scraper
- ZocDoc - ZocDoc Scraper
- ALEO - ALEO Scraper | Polish Companies and Financials
- Allabolag - Allabolag Detail Scraper | Company Data, Financials and Board
- BBB - BBB Scraper | Ratings, Reviews and Complaints
- BetaList - BetaList Scraper | Startups, Websites and Contacts
- Clutch - Clutch Scraper | Agencies, Reviews, Ratings, Services
- Company Data - Company Data Scraper | Emails, Phones and Tech Stack
- CSLB - CSLB Scraper | Contractor Licenses, Bonds and Leads
- Delaware - Delaware Scraper | Corporations, LLCs and Registered Agents
- French Company Prospector - French Company Prospector
- G2 - G2 Reviews Scraper
- Google Ads Transparency - Google Ads Transparency Scraper
- Oregon - Oregon Scraper | Contractor Licenses and Complaints
- Paginasamarillas - Paginasamarillas Scraper | Business Leads, Emails and Phones
- Pappers - Pappers Scraper | French Companies, Directors & Financials
- SEC - SEC Scraper | EDGAR Filings and Company Data
- SIRET French - SIRET French Company Enricher
- SoftwareAdvice - SoftwareAdvice Scraper | Reviews, Ratings and Pros & Cons
- Sunbiz - Sunbiz Scraper | Florida Companies and Officers
- TrustRadius - TrustRadius Scraper | Software Reviews, Ratings, Pros and Cons
- USPTO - USPTO Scraper | Trademark Search and Status
- Clutch Agency - Clutch Agency Scraper
- CNPJ Brazilian - CNPJ Brazilian Company Enricher
- Domain - Domain Enricher
- Sunbiz - Sunbiz Companies Scraper | New Florida Business Leads
🔎 SEO
- SpyFu - SpyFu Scraper | SEO, PPC and Competitor Data
- Scribd - Scribd Scraper | Documents, Authors and Views
- Bing - Bing Enricher Scraper | Mobile Friendly Test and Indexing
- Google News - Google News Scraper
- Yandexsearch - Yandexsearch Scraper | Search Results and Rankings
- Apple - Apple Reviews Scraper | App Store Reviews and Ratings
🎬 Video
📰 News
- ForexFactory - ForexFactory Scraper | Economic Calendar and Forecasts
- FT - FT Scraper | Financial Times Articles, Authors and Topics
- OpenAI - OpenAI Scraper | News, Blog Posts and Research
- DEV - DEV Scraper | Articles, Full Text and Authors
- Reuters - Reuters Scraper | News Articles, Tickers and Journalists
- TipRanks - TipRanks Scraper | Analyst Ratings and Price Targets
- Bloomberg - Bloomberg Scraper | News Articles and Full Text
🧰 More tools
- PrizePicks - PrizePicks Scraper | Player Props, Lines and Projections
- FanDuel - FanDuel Scraper | Odds, Spreads and Player Props
- Equibase - Equibase Scraper | Horse Racing Entries and Results
- Screener - Screener Scraper | Stock Fundamentals, NSE & BSE
- Maersk - Maersk Scraper | Vessel Schedules and Port Calls
- Twelvedata - Twelvedata Scraper | Stock Data and Analyst Estimates
- Wunderground - Wunderground Scraper | Weather History and Stations
Support
Need something this scraper doesn't do yet? We ship features fast.
- Feature requests go straight to our backlog
- Enterprise needs? We do custom integrations and high-volume plans
- Pricing questions? Check the Monetization tab on the actor page
Response time: usually under 24 hours.
Legal compliance
This Actor extracts publicly available data from urlscan.io: public scans and their public report pages. It does not bypass any login, paywall, or CAPTCHA, and it does not return unlisted or private scans. Users are responsible for complying with urlscan.io's terms of service and applicable data protection laws (GDPR, CCPA, and PIPL where relevant). Submitted URLs sometimes contain personal data, such as an email address or a token in a query string: handle such rows as personal data, for a legitimate security purpose, and keep them no longer than needed. Verdicts are urlscan.io's assessment at scan time; confirm a finding before you act on it, for example before a takedown request.
Built by SilentFlow for SOC analysts, threat hunters and brand protection teams who triage URLs, domains and IPs every day.


